T
traeai
Sign in

traeai topic radar

本地 LLM 推理、开源模型部署与端侧 AI

追踪 Ollama、llama.cpp、vLLM、LM Studio、量化、GPU/CPU 推理、私有化部署与端侧模型应用。

What searchers are trying to solve

想在本地或私有环境运行大模型,比较工具链、性能成本和部署方案。

Why this is worth tracking

本地推理把 AI 能力从云 API 扩展到隐私、成本、低延迟和离线场景,是长期基础设施方向。

本地 LLMlocal LLMOllamallama.cppvLLMLM Studio量化端侧 AI

长尾组合

这个专题可以沿着工具、实践、对比等搜索意图持续扩展,不靠空壳换词,而是用真实材料更新。

本地 LLM 工具本地 LLM 实践本地 LLM 对比local LLM 工具local LLM 实践local LLM 对比Ollama 工具Ollama 实践

可自动化内容模块

精选材料

持续抓取与 本地 LLM 推理 相关的高分文章、播客、视频和推文。

趋势判断

把最近变化、反复出现的观点和争议点整理成稳定摘要。

实体关联

自动连接相关公司、模型、产品、人物和概念,形成可继续深挖的入口。

Featured content

Filtered by relevance, score, and recency.

Search more
1-Bit Bonsai Image 4B: Image Generation for Local Devices

1-Bit Bonsai Image 4B: Image Generation for Local Devices

Hacker News Best1412 字 (约 6 分钟)
92

Bonsai Image 4B is the first 4B-parameter image model to run natively on iPhone, using 1-bit and ternary quantization to reduce memory by 6-8x and generate 512x512 images in 9.4s on mobile.

入选理由:1-bit Bonsai compresses diffusion transformer from 7.75GB to 0.93GB (8.3x reduct

FeaturedArticle#Image Generation#Model Compression#Local Deployment#Quantization#Apple Silicon英文
Stragglers, Not Failures: How Adaptive Hedged Requests Reduce p99 Latency by 74 Percent

Adaptive hedged requests reduce p99 latency by 74% by dynamically triggering hedges based on real-time latency distribution learning—not static thresholds or retries; DDSketch enables O(1) memory quantile estimation, paired with token-bucket rate limiting to prevent load amplification.

入选理由:In a fan-out architecture with 100 downstream services each having 1% straggler

FeaturedArticle#Distributed Systems#Latency Optimization#Hedged Requests#DDSketch#Microservices英文
Chinese AI Company Breaks Bottleneck to Run 60 Billion Parameter Model on Mobile

A Chinese AI company has broken the bottleneck of running a 60 billion parameter model on mobile devices using ternary quantization, saving 6x memory with minimal performance loss.

入选理由:Ternary quantization saves 6x memory while retaining 97% model capability, enabl

FeaturedArticle#AI Model#Ternary Quantization#Ascend Chip#Edge AI#Model Compression中文
We're open-sourcing Hy-MT1.5-1.8B-1.25bit — a 440MB translation model that runs fully offline on you...

腾讯混元开源 Hy-MT1.5-1.8B-1.25bit 翻译模型:仅440MB,支持33种语言+5种方言,1.25-bit量化无损精度,手机端全离线运行,性能超越Google Translate及部分商用API。

入选理由:25-bit超低比特量化实现440MB体积,较FP16压缩7.5倍且零精度损失

FeaturedTweet#机器翻译#模型量化#开源模型#端侧AI#腾讯中英混合
How to Build a Multi-Agent AI System with LangGraph, MCP, and A2A [Full Book]

How to Build a Multi-Agent AI System with LangGraph, MCP, and A2A [Full Book]

freeCodeCamp.org27840 字 (约 112 分钟)
92

本书深入讲解如何构建多智能体AI系统,通过LangGraph、MCP、A2A协议及Ollama实现状态管理、工具集成、跨框架协调及本地LLM推理,以实战代码构建学习加速器,展现生产级架构设计。

入选理由:使用LangGraph进行状态化智能体编排,解决多智能体系统可靠性问题。

FeaturedArticle#多智能体系统#LangGraph#MCP#A2A#Ollama#人工智能英文
Redis Creator Steps In to Build a Dedicated Inference Engine for DeepSeek V4

Redis founder antirez developed ds4.c — a dedicated inference engine for DeepSeek V4 Flash — enabling high-speed local execution on Macs with up to 58.52 token/s prefill speed.

入选理由:ds4.c uses Metal-only architecture, optimized exclusively for Apple Silicon with

FeaturedArticle#DeepSeek V4#ds4.c#Apple Silicon#Local Inference#antirez中文
ADeLe: Predicting and explaining AI performance across tasks

ADeLe: Predicting and explaining AI performance across tasks

Microsoft Research Blog1198 字 (约 5 分钟)
90

微软研究院联合高校提出ADeLe评估框架,通过18项核心能力维度对大模型与任务进行双向量化评分。该方法能构建模型能力画像,以约88%的准确率预测未知任务表现,并精准定位模型失败原因,有效弥补传统基准测试缺乏解释性与预测力的缺陷。

入选理由:ADeLe将模型与任务映射至18项核心能力维度(0-5分),实现需求与能力的结构化对齐。

FeaturedArticle#大模型评估#AI基准测试#能力画像#微软研究院#LLM评测英文
Architectural Change Cases: A Practical Tool for Evolutionary Architectures

Architectural Change Cases evaluate how decisions evolve over time rather than just recording current states, mitigating system decay by quantifying change probability and reversal costs. Complementing static ADRs with pre-mortems and chaos engineering, this tool exposes hidden assumptions and addresses maintainability risks from AI-generated code and business uncertainty.

入选理由:Change cases include QAR shifts, change probability, affected decision lists, an

FeaturedArticle#Evolutionary Architecture#ADR#System Design#Technical Debt#AI Engineering英文
New Claude Opus 4.8: 15 Things You May’ve Missed

New Claude Opus 4.8: 15 Things You May’ve Missed

AI Explained5477 字 (约 22 分钟)
87

Claude Opus 4.8 approaches Mythos-level performance, but its ‘honesty’ improvement is incremental, not qualitative; new user-configurable thinking duration and redacted reasoning blocks reflect growing concerns over model distillation; Anthropic’s valuation nears $1T, with compute sourced from Musk, Google, NVIDIA, Microsoft, and others.

入选理由:Opus 4.8 supports user-defined thinking duration (replacing prior adaptive-only

FeaturedVideo#Claude#Anthropic#LLM#AI Safety#Model Distillation英文
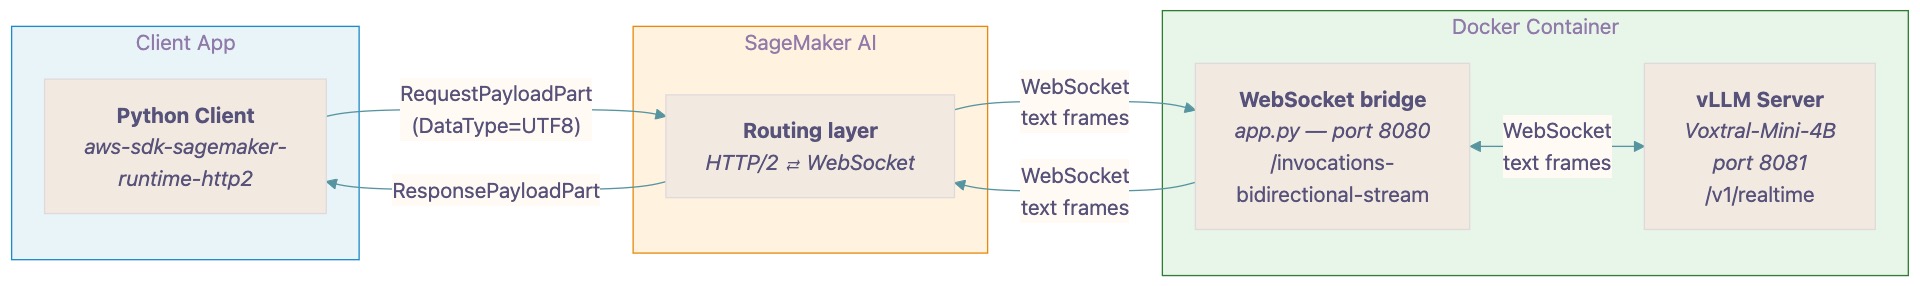
Build Real-Time Voice Applications with Amazon SageMaker AI and vLLM

Build Real-Time Voice Applications with Amazon SageMaker AI and vLLM

AWS Machine Learning Blog2911 字 (约 12 分钟)
87

AWS combines SageMaker AI with vLLM to enable bidirectional streaming speech-to-text inference, supporting real-time voice assistants, live captions, and more with significantly reduced latency.

入选理由:SageMaker AI provides native HTTP/2 bidirectional streaming on port 8443, automa

FeaturedArticle#AWS#SageMaker#vLLM#Voice AI#Streaming Inference英文
How to Build Optimal AI Agents That Actually Work – A Handbook for Devs

How to Build Optimal AI Agents That Actually Work – A Handbook for Devs

freeCodeCamp.org5915 字 (约 24 分钟)
87

The optimal organization of AI agent systems depends on task complexity and model type; Google's research with 150+ experiments shows centralized/hybrid structures work best for OpenAI models, while Google models excel in decentralized coordination.

入选理由:Over 150 experiments show OpenAI models improve performance by 37% under central

FeaturedArticle#AI Agents#LLM#Google Research#Multi-Agent Systems#Ollama英文
vLLM V0 to V1: Correctness Before Corrections in RL

vLLM V0 to V1: Correctness Before Corrections in RL

Hugging Face Blog1640 字 (约 7 分钟)
87

The vLLM upgrade from V0 to V1 focuses on backend inference correctness, fixing critical issues like logprob semantics, runtime defaults, and inflight weight updates to ensure reliable results in reinforcement learning training.

入选理由:vLLM V1 prioritizes fixing backend inference correctness over performance optimi

FeaturedArticle#vLLM#Reinforcement Learning#Inference Engine#Hugging Face#Model Deployment英文
Google Developers Blog 图标

MaxText Expands Post-Training Capabilities: Introducing SFT and RL on Single-Host TPUs

Google Developers Blog621 字 (约 3 分钟)
87

Google MaxText 新增单机 TPU 上的监督微调(SFT)和强化学习(RL)支持,集成 Tunix 和 vLLM,简化 LLM 后训练流程。

入选理由:MaxText 现支持在单机 TPU(如 v5p-8)上运行 SFT 和 RL,降低后训练门槛。

FeaturedArticle#MaxText#LLM#TPU#SFT#Reinforcement Learning英文
PureblueAI 鲁扬:把 prompt 当货架空间,把 GEO 当量化交易

PureblueAI 鲁扬:把 prompt 当货架空间,把 GEO 当量化交易

AI炼金术2675 字 (约 11 分钟)
85

GEO是AI时代品牌优化新范式,需用量化交易思维解构大模型黑盒,与SEO存在本质差异。

入选理由:GEO需研究AI信任内容的特征,而非单纯优化文章写法

FeaturedPodcast#GEO#AI可解释性#量化交易#SEO#品牌优化中文
4-bit Rotational Quantization

4-bit Rotational Quantization

Weaviate Blog1993 字 (约 8 分钟)
85

Weaviate 1.39通过4位旋转量化技术实现向量搜索性能提升3.8倍,内存占用减少45%,并引入SIMD加速的FWHT转换。

入选理由:4位RQ在保持相似召回率情况下减少45%堆内存使用

FeaturedArticle#量化技术#Weaviate#向量搜索#SIMD优化英文
How Shopify built a continual learning loop with PyTorch and vLLM

How Shopify built a continual learning loop with PyTorch and vLLM

PyTorch Blog2165 字 (约 9 分钟)
85

Shopify通过PyTorch和vLLM构建持续学习循环,将生产失败转化为模型权重,提升质量并降低96%服务成本。

入选理由:使用PyTorch和vLLM构建持续学习循环可降低96%服务成本

FeaturedArticle#PyTorch#vLLM#持续学习#机器学习#Shopify英文
Hardware-Agnostic Models in vLLM

Hardware-Agnostic Models in vLLM

PyTorch Blog2004 字 (约 9 分钟)
85

vLLM引入硬件无关层,在NVIDIA H100上实现接近原生性能,吞吐量差异仅3.4%。

入选理由:HW agnostic层在NVIDIA H100上实现3.4%吞吐量差异(几何平均值)

FeaturedArticle#vLLM#PyTorch#GPU优化#模型兼容性英文
Benchmarking Local LLM Servers: llama.cpp, llamafile, LM Studio, and Ollama

Benchmarking Local LLM Servers: llama.cpp, llamafile, LM Studio, and Ollama

Mozilla AI Blog3105 字 (约 13 分钟)
85

配置优化对本地LLM服务器性能影响显著,不同平台的设置可带来最高63%的性能提升。

入选理由:启用CUDA graphs可使L40S解码速度提升16.8%(0.8B模型)

FeaturedArticle#LLM#性能优化#本地服务器#benchmarking英文
Building a RAG Pipeline for Semantic Code Search: A Developer Diary and Field Notes

Building a RAG Pipeline for Semantic Code Search: A Developer Diary and Field Notes

The JetBrains Blog3917 字 (约 16 分钟)
85

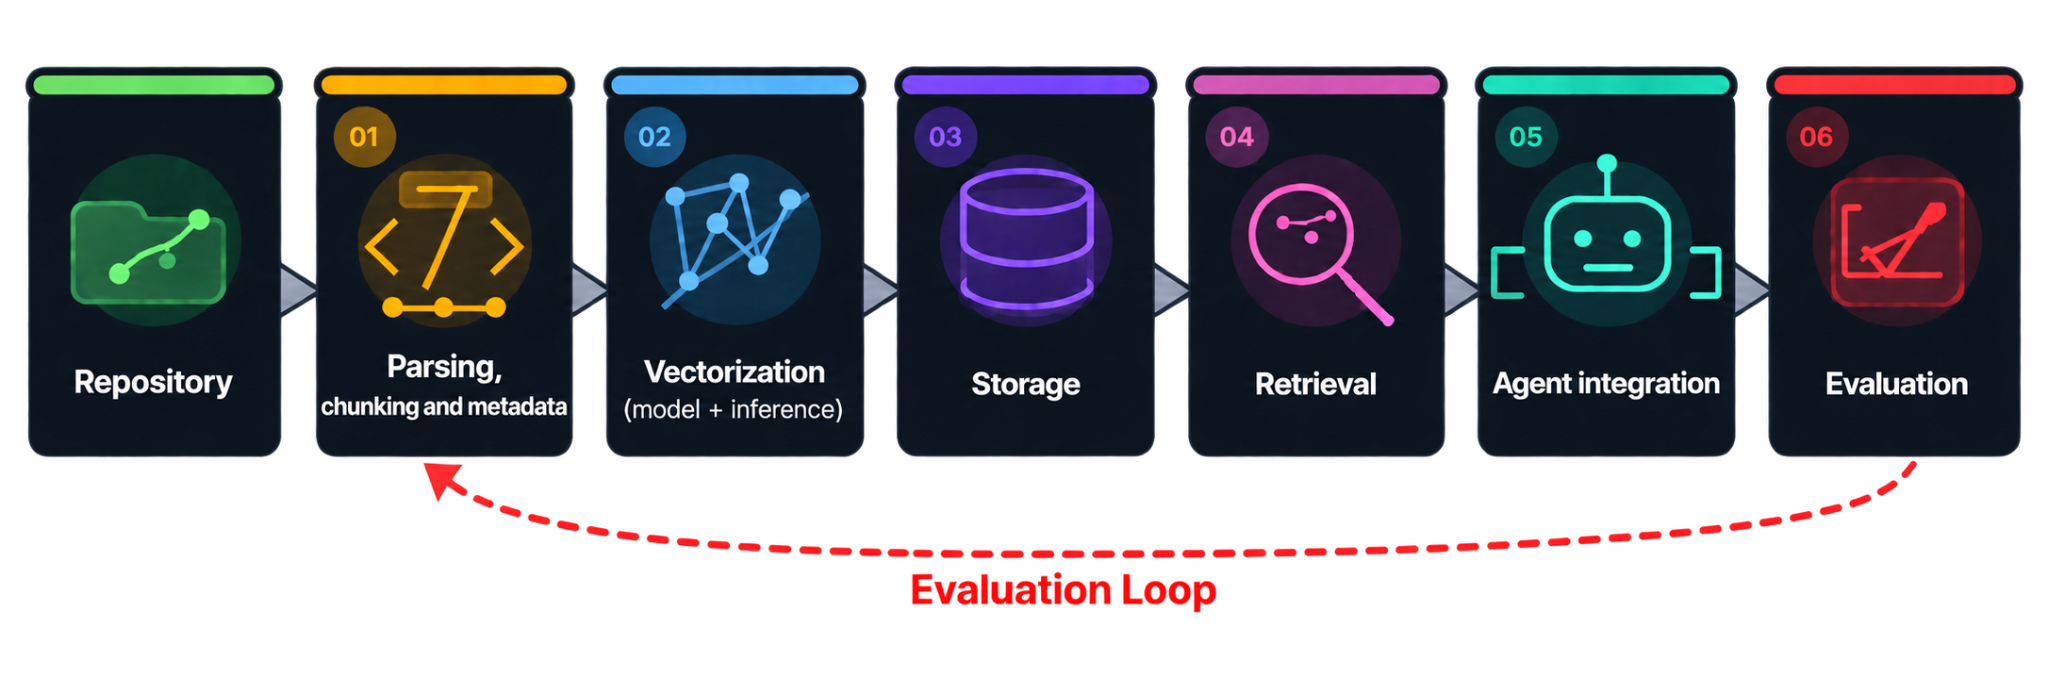
JetBrains分享了构建RAG管道进行语义代码搜索的实践经验,涵盖解析、分块、向量化等关键步骤,揭示生产环境中的技术挑战与优化策略。

入选理由:代码解析与分块是RAG管道的基础,需处理多语言语法差异

FeaturedArticle#RAG#语义搜索#代码库#JetBrains#AI英文

Related topics

跨材料问答 · 本地 LLM 推理、开源模型部署与端侧 AI

回答基于:本地 LLM 推理、开源模型部署与端侧 AI 专题下 21 条材料
    0 / 500

    AI may generate inaccurate information. Please verify important content.