T
traeai
Sign in

公司

什么是 DeepSeek?

也叫:DeepSeek公司

提供AI模型补偿的公司,可能涉及商业合作。

为什么现在值得关注?

最近变化

2026-10-21 · 攻击者主要使用Anthropic Claude和Deepseek模型的旧版本实施攻击

DeepSeek 被反复提及时,通常意味着它正在影响产品路线、开发者工作流或 AI 产业判断。这个页面把分散材料合并成一个可持续更新的观察入口。

📰 DeepSeek 最新动态

已收录 30 篇与「DeepSeek」相关的 AI 资讯和分析。

科技爱好者周刊(第 399 期):中国 AI 大厂访问记

Weekly for Tech Enthusiasts (Issue 399): Visiting China's AI Giants

阮一峰的网络日志4694 字 (约 19 分钟)
92

US analysts' visit reveals China's AI compute is 1/8th of the US, but a 4-7x efficiency gain bridges the hardware gap.

入选理由:2025年底美国AI算力约为中国8倍,中国当前总算力仅相当于美国2023年水平。

FeaturedArticle#AI Infrastructure#Compute Efficiency#LLM Open Source#US-China AI中文
https://t.co/nw0GoHamCI

DeepSeek's $10 Trillion Grand Strategy [Translation]

宝玉(@dotey)5655 字 (约 23 分钟)
92

DeepSeek builds a low-cost, high-efficiency model system through multiple foundational innovations to drive China's $10 trillion AI hardware ecosystem and achieve its own $1 trillion valuation.

入选理由:DeepSeek V4 Pro在100万上下文中仅需5.48GB HBM显存,远低于竞品的60-89GB。

FeaturedTweet#DeepSeek#AI Model#MoE#KV Cache Optimization#Hardware Ecosystem中文
DeepSeek 的 10 万亿美元大战略

DeepSeek's 10 Trillion USD Grand Strategy

宝玉的分享5756 字 (约 24 分钟)
92

DeepSeek reduces KV cache requirements through innovations, driving China's AI hardware ecosystem toward a $10 trillion industry.

入选理由:DeepSeek V4 Pro仅需5.48GB HBM,相比GLM5的60GB和Qwen3-235B-A22B的89GB显著节省显存

FeaturedArticle#AI Model#Hardware Ecosystem#KV Cache#DeepSeek#China AI中文
#546. 电力、晶圆与 AI 基础设施的未来

#546. Power, Wafers, and the Future of AI Infrastructure

跨国串门儿计划3114 字 (约 13 分钟)
92

AI infrastructure is undergoing an unprecedented systemic重构 in capitalist history, with power and wafers as the core bottlenecks; Anthropic's $11B monthly ARR surge reveals explosive demand, while TSMC, NVIDIA, and SpaceX are reshaping the global geopolitics of compute.

入选理由:Anthropic单月ARR增长110亿美元,远超市场预期,证明AI基础设施需求远超资本定价能力。

FeaturedPodcast#AI Infrastructure#Semiconductor#TSMC#NVIDIA#Compute Bottleneck中文
Latent Space 图标

Scaling Past Informal AI - Carina Hong, Axiom Math

Latent Space1535 字 (约 7 分钟)
87

Axiom Math advances Verified AI to scale brilliance and compound it through formal proofs with Lean, achieving 12/12 on Putnam and 99% (187/189) on Verina Codegen, far exceeding OpenAI o3’s 4.9%, providing critical capability verification and knowledge propagation for AGI.

入选理由:Axiom在Putnam考试中取得12/12,优于顶尖本科生与当时最接近的AI系统DeepSeek(103/120)。

FeaturedArticle#Verified AI#Formal Verification#Lean#AGI#Putnam Exam英文
#558.AI时代的个人革命:Garry Tan 谈开源 AI、创业信仰、创伤动力

Garry Tan argues that AI is triggering the next personal computing revolution, where open-source Agents and personal AI will empower ordinary people with unprecedented creative capacity; YC’s core tenet is “make something people want”; entrepreneurs must convert trauma into creativity through authentic perception and strong agency.

入选理由:Garry Tan 提出‘个人AI必须由自己拥有和控制’,并正在开发 G Brain——整合邮件、日历、联系人与笔记的个人知识记忆系统。

FeaturedPodcast#AI#Open Source#Startup#YC#Personal Computing中文
DeepSeek’s New AI Is A Game Changer

DeepSeek’s New AI Is A Game Changer

Two Minute Papers1580 字 (约 7 分钟)
87

DeepSeek’s visual pointing lets open-source VLMs slash visual tokens by 90 % while matching or beating GPT-4V on seven public benchmarks and delivering traceable reasoning paths.

入选理由:视觉指针机制将视觉 token 用量压缩 90%,仍保持 SOTA 精度

FeaturedVideo#DeepSeek#Vision-Language Models#Visual Pointing#Token Efficiency#Open Research英文
AI Guardrails Aren’t Stopping Criminal Hackers

AI Guardrails Aren’t Stopping Criminal Hackers

Wired AI1020 字 (约 5 分钟)
85

黑客利用AI工具绕过安全防护,使用Anthropic Claude等模型实施长期自动化攻击,暴露AI防御体系重大漏洞。

入选理由:攻击者主要使用Anthropic Claude和Deepseek模型的旧版本实施攻击

FeaturedArticle#AI安全#网络攻击#威胁情报#AI模型#安全防护英文
Fun and crazy napkin math: Meta, NVIDIA, Alibaba, DeepSeek, Moonshot, Mistral and ~30 other labs hav...

截至2023年底,Meta、NVIDIA等30多个实验室在Hugging Face Hub共享了近10亿美元的AI训练计算资源,远超维基百科的志愿者工时。

入选理由:Hugging Face Hub上共享的AI训练计算资源在2023年底已达近10亿美元,是维基百科志愿者工时的25倍。

FeaturedTweet#AI训练资源#Hugging Face#Meta#NVIDIA#开源英文
国产之光!刚把 RSS 网站的模型从 4.1 flash 升级到 DeepSeek-V4.1-Flash-1017

思考强度设置为 High,看翻译质量有没有提升。

DeepSeek-V4.1-Flash-1017模型在性能、速度和输出效率上实现帕累托改进,已部署至官网、APP和API接口。

入选理由:DeepSeek-V4.1-Flash-1017模型输出长度缩短23%且推理速度提升18%

FeaturedTweet#DeepSeek#模型优化#AI推理#大模型中英混合
AI HOT 精选 图标

DeepSeek 开放自研搜索 API

AI HOT 精选41 字 (约 1 分钟)
85

DeepSeek 推出自研搜索 API,支持多语言及 SEO 优化,日均处理数亿次查询。

入选理由:DeepSeek 搜索 API 日均处理数亿次查询,支持多语言检索

FeaturedArticle#DeepSeek#搜索API#AI#SEO优化中英混合
量子位 图标

DeepSeek Bot来了!民间版,DSH装个插件就能用

量子位1715 字 (约 7 分钟)
85

DeepSeek Bot通过DSH插件实现多Bot管理与持久化记忆,适合开发者快速部署。

入选理由:DSH插件支持Bot持久化记忆与团队协作管理

FeaturedArticle#DeepSeek#DSH#开源#AI#插件中文
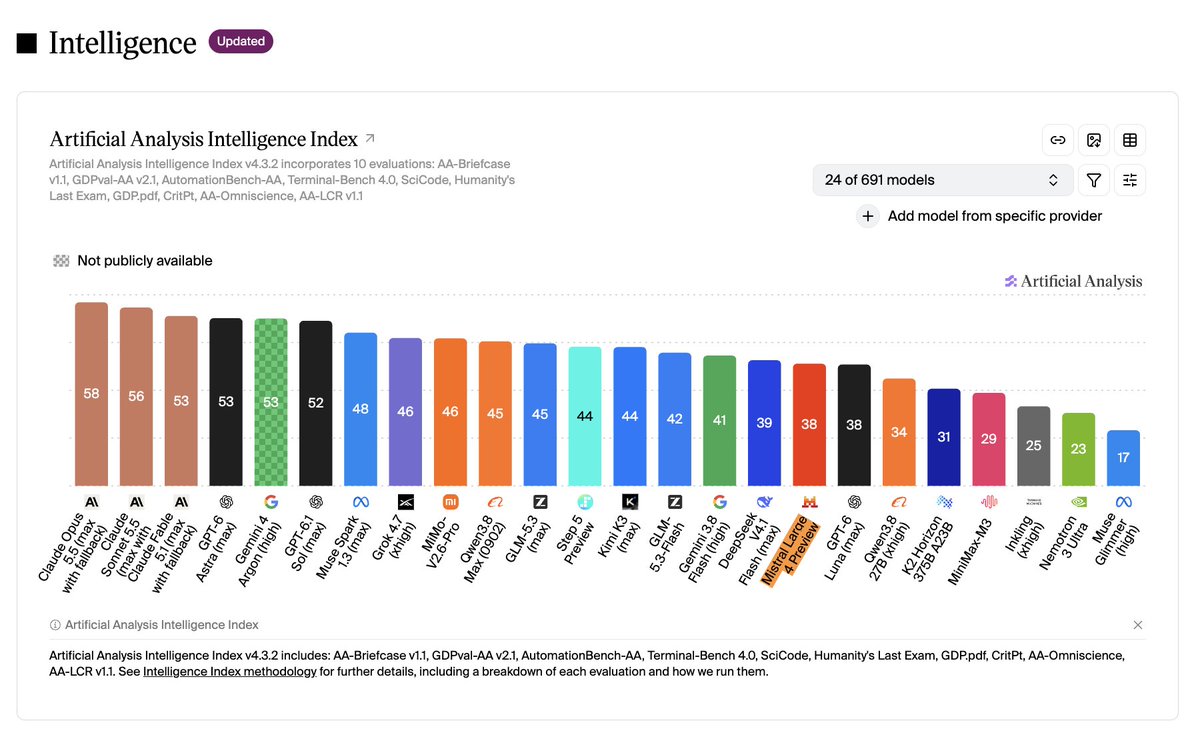
🇪🇺 Respect for @MistralAI for actually getting close now

38th in intelligence and only just behind the Chinese open weight models like DeepSeek, GLM and Kimi and ahead of any US open weight model!

It shows Europe can still do stuff if they just all get on the same page

👏

Mistral AI的Mistral Large 4模型在综合基准测试中排名38,接近中国顶尖开源模型,且在关键领域表现优于美国模型。

入选理由:Mistral Large 4拥有1T参数和多模态能力,是欧美最佳开源模型

FeaturedTweet#MistralAI#开源模型#AI排名#多模态模型中英混合
量子位 图标

DeepSeek通过DSec基础设施优化沙盒环境,实现资源利用率提升50倍以上,支撑百万级Agent并发训练。

入选理由:镜像分层策略使磁盘写入量减少57%,构建时间缩短1.71倍

FeaturedArticle#弹性计算#沙盒基础设施#资源调度#DeepSeek中文
Can Jev replace your LLM judge? Evaluating quality, cost, and latency

Can Jev replace your LLM judge? Evaluating quality, cost, and latency

MLflow Blog1503 字 (约 7 分钟)
85

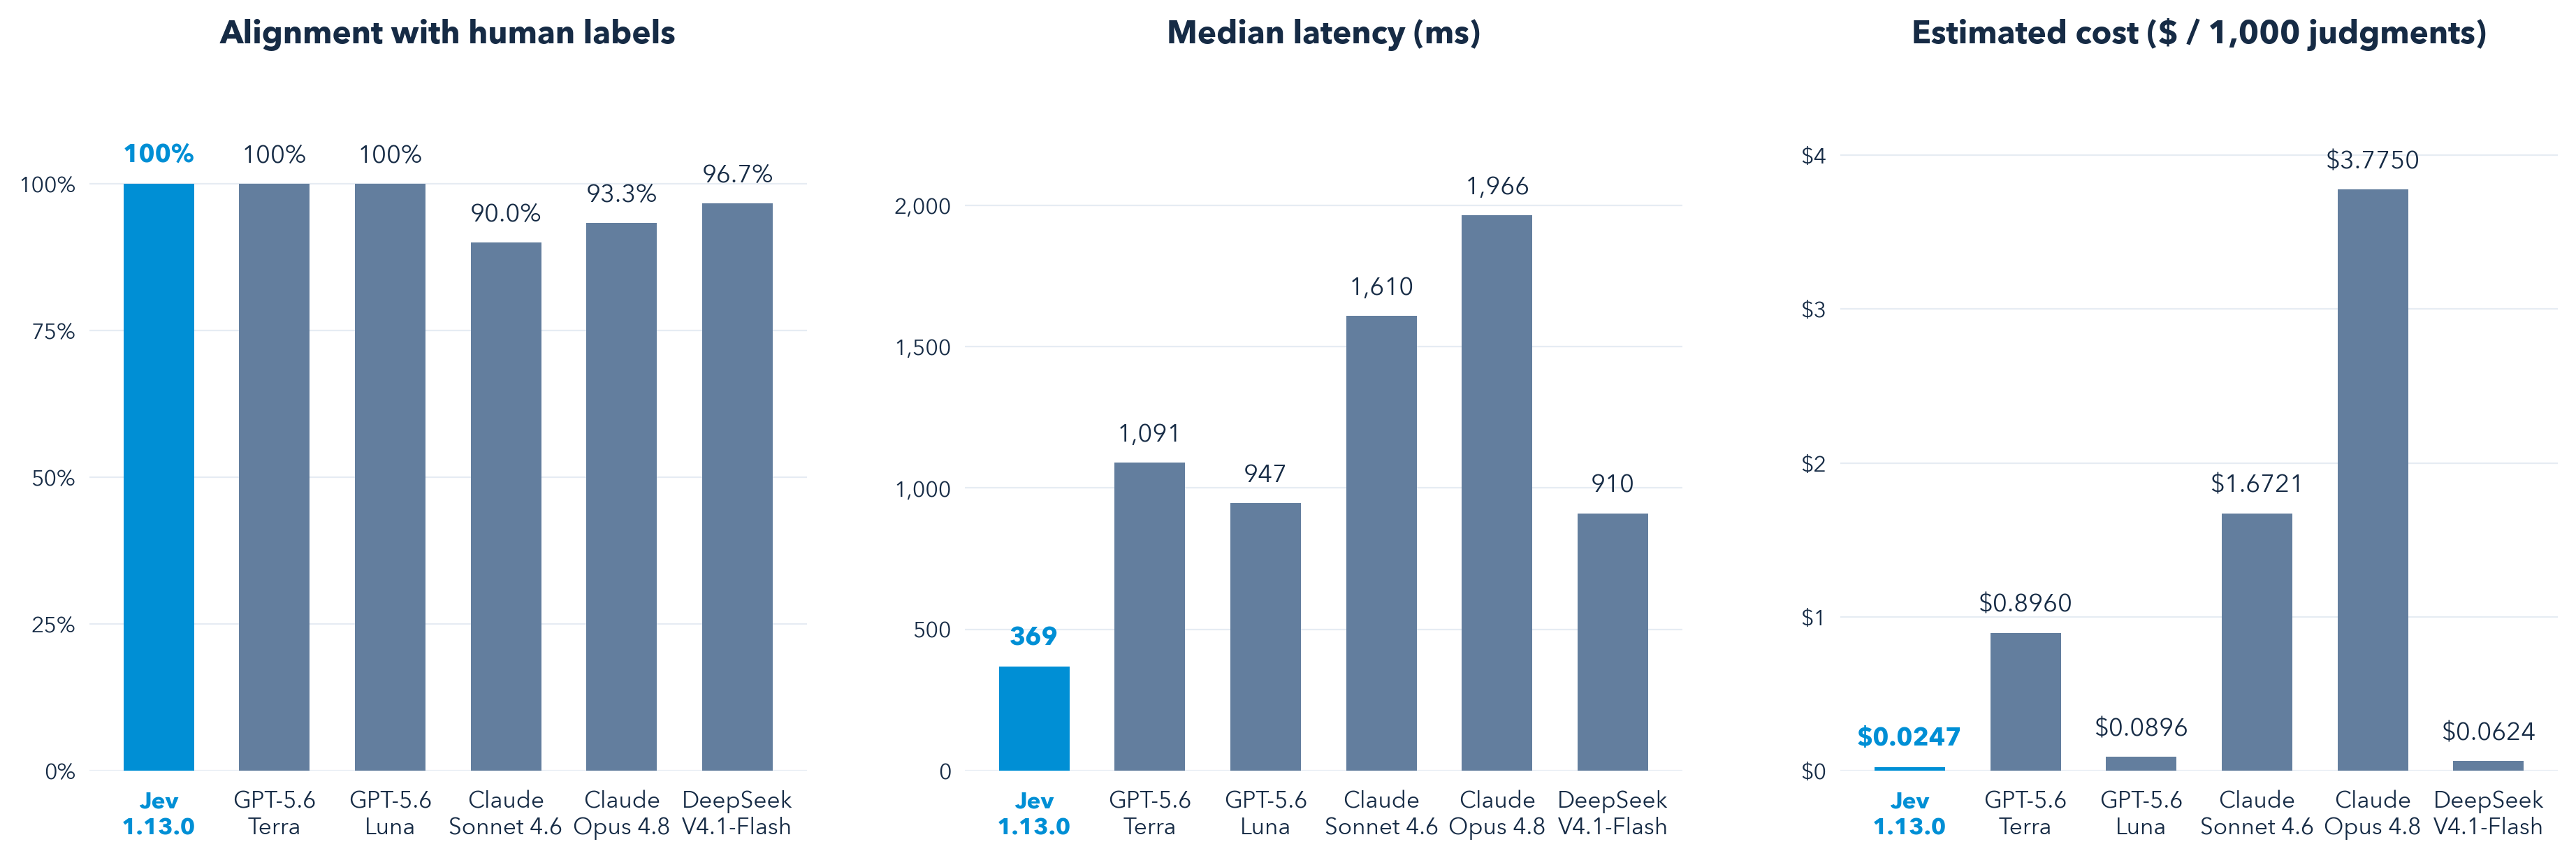
Jev通过结构化输出实现更低延迟和成本,但无法替代LLM judge的解释能力,在技术问答评估中表现优异。

入选理由:Jev的结构化输出使成本降至$0.042/百万输入token,比传统LLM低50%以上

FeaturedArticle#Jev#LLM judge#MLflow#模型评估#TypeSafe英文
DeepSeek Harness桌面版实测:更像「个人助理」,还给你送钱

DeepSeek Harness桌面版通过本地化安装和插件系统,将AI助手转变为可自动化办公的生产力工具,支持文档处理、定时任务和自定义插件开发。

入选理由:DeepSeek Harness桌面版支持Office/PDF文件处理,处理速度达300 tok/s

FeaturedArticle#AI助手#插件系统#自动化办公#DeepSeek中文
FeaturedTweet#Agent Harness#GPT Wrappers#AI模型#技术架构英文
DeepSeek’s New AI System Shouldn’t Be Possible

DeepSeek’s New AI System Shouldn’t Be Possible

Two Minute Papers937 字 (约 4 分钟)
85

DeepSeek推出可自我扩展的AI系统,通过动态重写程序实现功能定制,但缺乏详细技术原理说明。

入选理由:自扩展AI系统可通过用户指令动态生成功能模块

FeaturedVideo#AI#DeepSeek#自扩展系统#开源英文
DeepSeek is back... and Silicon Valley is terrified

DeepSeek is back... and Silicon Valley is terrified

Fireship1559 字 (约 7 分钟)
85

DeepSeek发布新模型DeepSeek Coder引发行业关注,OpenAI因安全风险暂停训练,Claude代码泄露事件被深度分析。

入选理由:DeepSeek Coder成为GitHub最快获得星标的历史性项目

FeaturedVideo#AI模型#DeepSeek#OpenAI#代码安全#GitHub中英混合
DeepSeek(@deepseek_ai) 图标

DeepSeek推出支持多模态的API,允许通过图像和文本混合输入进行交互,适用于需要视觉和文本处理的应用场景。

入选理由:DeepSeek的'deepseek-v4-flash-vision-exp'模型支持图像和文本混合输入,每个图像最多384个token计费。

FeaturedTweet#API#多模态#DeepSeek#图像处理中英混合
KDnuggets 图标

Speed Up LLM Inference with DSpark Speculative Decoding

KDnuggets1718 字 (约 7 分钟)
85

DSpark推测解码通过结合并行和顺序组件,可提升LLM生成速度60-85%。

入选理由:DSpark结合并行与顺序组件,提升生成速度达60-85%

FeaturedArticle#LLM#DSpark#推测解码#CUDA#llama.cpp英文

与「DeepSeek」经常一起出现的 AI 术语。

💡 想追踪「DeepSeek」的长期趋势?去 实体雷达 · DeepSeek 查看详细分析和跨材料问答。

AI may generate inaccurate information. Please verify important content.