T
traeai
Sign in

公司

什么是 Databricks?

也叫:Databricks Inc.

提供湖仓一体架构的美国数据分析公司

为什么现在值得关注?

最近变化

2026-10-20 · MemCurrent使代理通过率提升3倍,同时减少31%的token使用和26%的运行时间

Databricks 被反复提及时,通常意味着它正在影响产品路线、开发者工作流或 AI 产业判断。这个页面把分散材料合并成一个可持续更新的观察入口。

📰 Databricks 最新动态

已收录 30 篇与「Databricks」相关的 AI 资讯和分析。

Databricks 图标

Databricks' Instructed-Retriever-1 cuts search latency by 3x and TTFT to ~2s via parallel test-time scaling without quality loss. The unified model handles query generation and reranking in parallel using multi-pivot groupwise reranking, achieving Pareto-optimal recall-precision tradeoffs for enterprise RAG systems.

入选理由:Instructed-Retriever-1使搜索延迟降低3倍以上,TTFT降至约2秒,无需重新配置。

FeaturedArticle#RAG#Test-Time Scaling#Instructed-Retriever-1#Databricks#Retrieval英文
Databricks 图标

Databricks Lakebase enables Martin Fowler’s long-aspirational Practice #4—“every developer gets their own database instance”—via copy-on-write branching, making evolutionary database development operational at production scale for the first time.

入选理由:Lakebase 支持秒级创建 TB 级生产数据库的零存储开销分支(O(1) 操作)

FeaturedArticle#Databricks#Lakebase#database branching#evolutionary database design#CI/CD英文
Databricks 图标

Octopus Energy reduced margin data engineering costs by 50x to handle 48x data growth from UK’s MHHS policy, using a three-stream architecture and Delta Lake CDF for incremental processing—cutting daily rows from 25B to 300M.

入选理由:采用三流分离架构(Settlement/Half-Hourly/Monthly)适配不同结算粒度,避免单体流水线重复处理未变更数据。

FeaturedArticle#Delta Lake#MHHS#Data Architecture#Incremental Processing#Energy Data英文
Databricks 图标

Databricks built Pantheon, a custom TSDB based on Thanos, to handle 10 trillion daily samples and 5B active time series, solving scalability, cost, and cardinality challenges across 70+ cloud regions using tiered storage and lakehouse integration.

入选理由:自研Pantheon基于Thanos改造,支撑每日10万亿样本与50亿活跃时序,降低云成本数百万美元。

FeaturedArticle#TimeSeriesDatabase#Monitoring#Databricks#Thanos#HighCardinalityMetrics英文
Databricks 图标

Databricks has announced the general availability of three complementary capabilities in Unity Catalog: Attribute-Based Access Control (ABAC) policies for row filtering and column masking, governed tags, and agentic data classification, enabling dynamic, standardized, and automated data governance.

入选理由:Databricks 推出了 ABAC 策略,实现了一次定义多次应用的数据访问控制。

FeaturedArticle#Unity Catalog#ABAC#Data Governance#Automated Classification中英混合
How Superhuman and Databricks built a 200K QPS inference platform together

Superhuman and Databricks jointly built a 200K QPS AI inference platform using Lakehouse architecture and model optimization for low-latency, high-throughput real-time applications.

入选理由:平台峰值达到200,000 QPS,支持超大规模实时推理。

FeaturedArticle#AI Inference#Databricks#Lakehouse#High-Performance Computing#Superhuman英文
Databricks 图标

Databricks Genie redefines enterprise conversational intelligence by democratizing data access through natural language, delivering cross-industry and functional solutions across financial planning, legal compliance, and IT operations to accelerate insights and decision-making.

入选理由:AI4BI Command Center提供决策者统一、受治理的智能界面,含上下文洞察、主动预警与what-if能力,提升决策效率30%+。

FeaturedArticle#Databricks Genie#Conversational AI#Unity Catalog#AI4BI Command Center#AgentOps英文
Databricks 图标

Leverages Apache Spark Real-Time Mode and transformWithState to deliver a unified, sub-second real-time sessionization architecture, replacing Flink or in-house solutions to power personalization, recommendation engines, and dynamic content scheduling for millions of players.

入选理由:使用 transformWithState + Real-Time Mode 实现单引擎统一架构,输入处理与定时触发均可达亚秒级精度。

FeaturedArticle#Apache Spark#Real-Time Mode#transformWithState#Structured Streaming#Gaming英文
Databricks 图标

Starting Jan 1, 2026, 700+ U.S. hospitals must manage total cost and quality across 5 high-cost surgical episodes over 30 days; legacy analytics cannot enable proactive intervention—success hinges on unified lakehouse platforms, embedded AI workflows, and scalable architecture, or 66% will lose revenue due to data latency.

入选理由:CMS TEAM要求医院对5类手术(如关节置换、CABG)承担30天全周期成本责任, 未达标者5年内或面临超1000万美元追偿

FeaturedArticle#Value-Based Care#CMS TEAM#Healthcare Analytics#Lakehouse#AI Clinical Decision Support英文
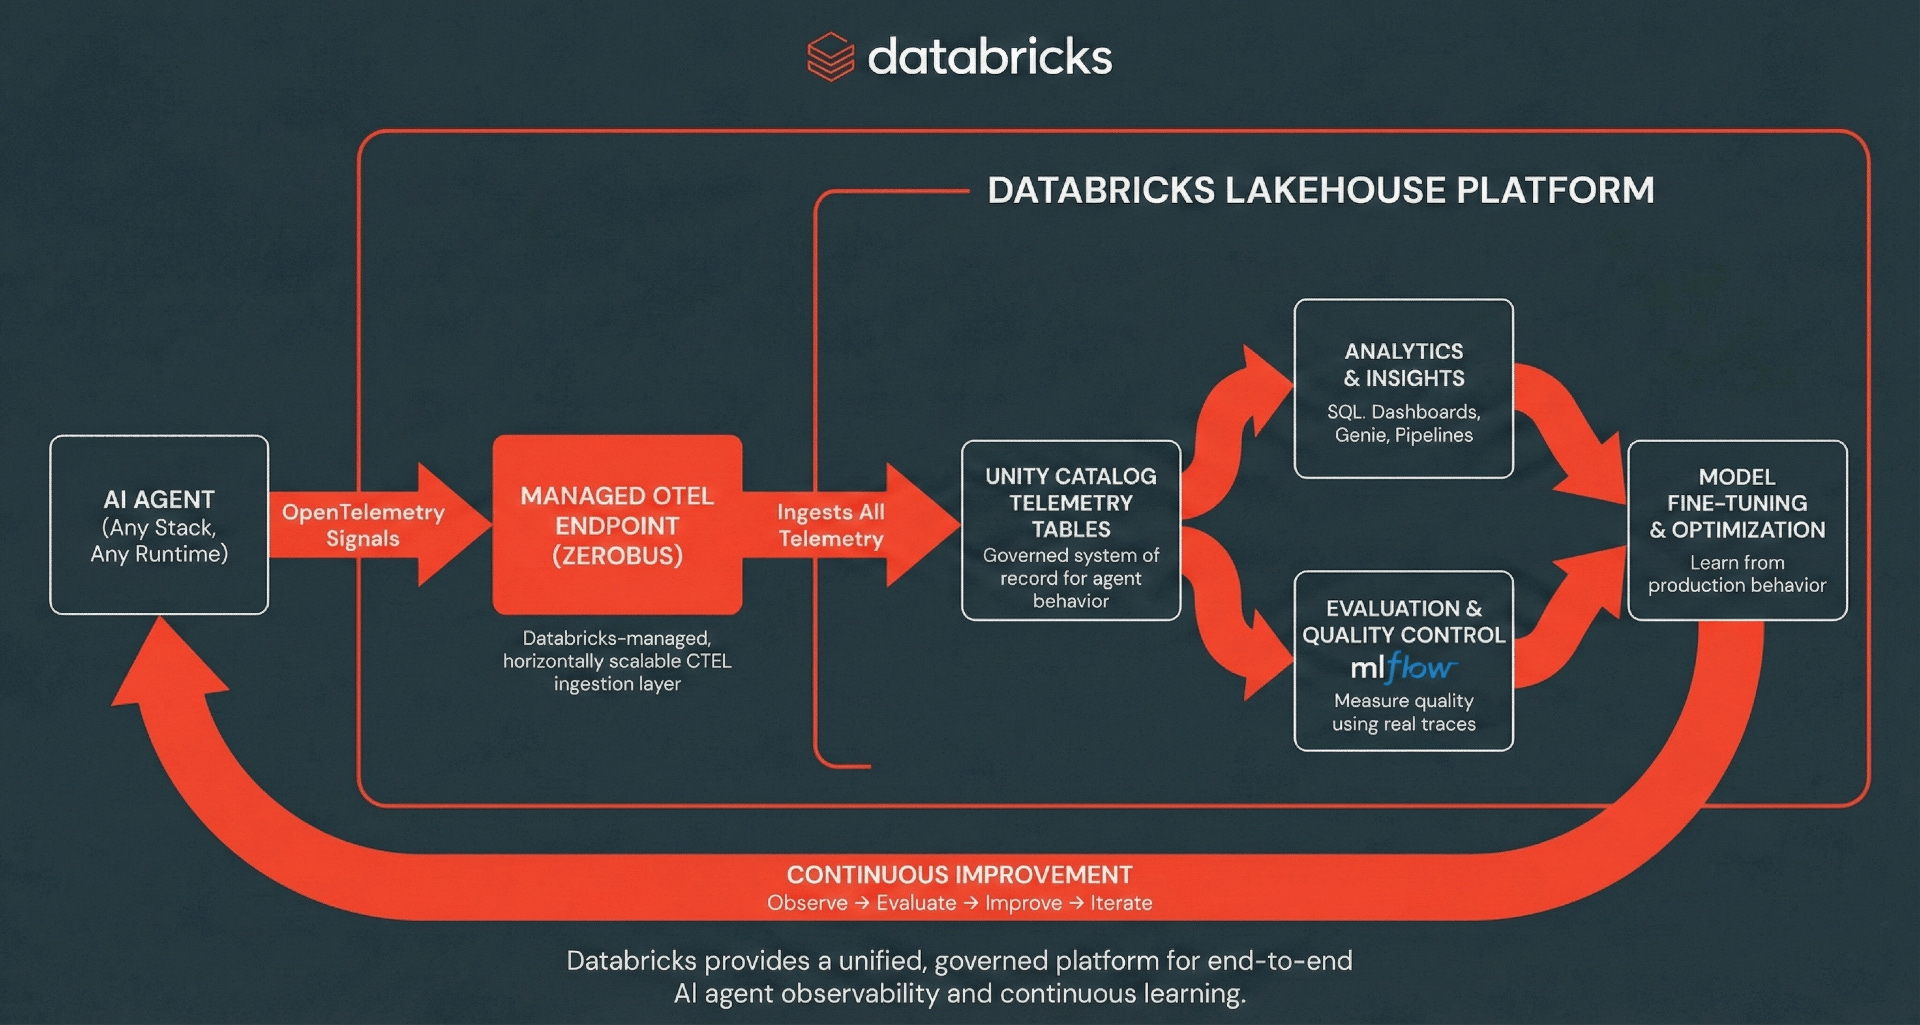
Observability for any agent, anywhere: Production-ready tracing with OpenTelemetry & Unity Catalog on Databricks

Databricks introduces a production-ready AI agent observability solution using Unity Catalog and OpenTelemetry, storing traces as Delta tables in the Lakehouse to enable long-term retention, SQL analytics, PII governance, and MLflow-based evaluation loops.

入选理由:Databricks 支持通过 OTLP/gRPC 将 OpenTelemetry traces 实时写入 Unity Catalog Delta 表,实现零基础设施开销的 serverless ingestion。

FeaturedArticle#OpenTelemetry#Unity Catalog#Databricks#AI Observability#Lakehouse英文
Databricks 图标

Addressing HR's Widening Capacity Gap with AI

Databricks2106 字 (约 9 分钟)
87

HR teams face unprecedented strain: 84% report frequent stress, 95% describe workloads as 'too much'; while AI hasn't delivered significant value yet (88% say so), it's emerging as the key lever to overcome talent capacity constraints.

入选理由:84% HR领导者报告频繁压力,95%称工作量‘太多且充满压力’

FeaturedArticle#HR#AI#organizational change#talent management#digital transformation英文
Databricks 图标

Hamlet通过Databricks Lakebase Postgres为每个代码变更创建独立生产数据分支,AI代理自动测试确保安全,探索向量搜索等新功能。

入选理由:每个Pull Request获得独立的生产数据分支用于测试

FeaturedArticle#Databricks#Lakebase Postgres#AI测试#数据分支英文
Databricks 图标

Introducing Agent Memory on Databricks

Databricks1188 字 (约 5 分钟)
85

Databricks推出Agent Memory技术,通过MemCurrent架构实现代理记忆功能,使企业级任务处理效率提升3倍且减少31%的token消耗。

入选理由:MemCurrent架构包含插件、按需工具和离线梦境流水线三类访问模式

FeaturedArticle#Databricks#Agent Memory#MemCurrent#AI平台英文
Databricks 图标

MemCurrent: Designing Persistent Memory for Production Agents

Databricks2453 字 (约 10 分钟)
85

MemCurrent通过结合插件、工具和离线管道三种记忆访问模式,显著提升代理性能并减少资源消耗。

入选理由:MemCurrent使代理通过率提升3倍,同时减少31%的token使用和26%的运行时间

FeaturedArticle#MemCurrent#持久化记忆#Databricks#Agent#生产环境英文
Databricks 图标

Databricks的Agentic CDP CustomerLake进入Beta,实现转化率提升10点、受众构建时间减少90%、成本降低40%。

入选理由:CustomerLake Beta阶段实现受众构建时间减少90%,2小时内完成

FeaturedArticle#CDP#AI#Databricks#Marketing Lakehouse英文
Databricks 图标

How to get the most out of running dbt on Databricks

Databricks1743 字 (约 7 分钟)
85

在Databricks上运行dbt时,采用增量策略和原生编排可显著降低成本并提升性能。

入选理由:使用replace_where策略可减少30%以上的重复计算开销

FeaturedArticle#dbt#Databricks#数据工程#Lakehouse英文
Databricks 图标

What makes a catalog open? Unity Catalog Advances the Open Lakehouse

Databricks1751 字 (约 8 分钟)
85

Unity Catalog通过支持Apache Iceberg REST catalog spec实现数据可移植性,允许在不同目录间移动表而无需复制数据。

入选理由:Unity Catalog支持Apache Iceberg的REGISTER和UNREGISTER操作,实现零数据复制迁移

FeaturedArticle#Databricks#Apache Iceberg#Lakehouse#数据可移植性#云存储英文
Databricks 图标

How HP Is Building an AI-Ready CDP with Databricks CustomerLake

Databricks1487 字 (约 6 分钟)
85

HP通过Databricks CustomerLake和Genie将CDP构建时间缩短至2小时,成本降低40%,数据扩展90%。

入选理由:HP使用Databricks CustomerLake将受众创建时间从2-3个月缩短至2小时。

FeaturedArticle#Databricks#CDP#AI#数据平台#营销技术英文
Ben Horowitz on what it would take to actually see an AI "fast takeoff" scenario, using a framework ...

AI实现‘快速起飞’需同时满足四条件:资源消耗递减、训练时间缩短、准确率提升且持续迭代,但目前四条件均未达成,风险尚属理论范畴。

入选理由:AI模型训练资源消耗需呈指数级下降才能实现快速迭代

FeaturedTweet#AI#技术趋势#Databricks#Ben Horowitz英文
a16z(@a16z) 图标

AI自我改进需满足资源减少、训练时间缩短、准确率提升及可重复性四个条件,但当前进展尚未达到超级智能。

入选理由:AI模型需同时满足资源消耗减少、训练时间缩短、准确率提升和可重复性四项条件才能实现自我迭代。

FeaturedTweet#AI#机器学习#Databricks#超级智能英文
Databricks 图标

Databricks在Delta Lake和Apache Iceberg上实现多语句事务,推动湖仓一体架构发展,提升数据仓库工作负载的效率和一致性。

入选理由:多语句事务减少数据复制和治理碎片化,降低运营成本30%以上

FeaturedArticle#Delta Lake#Apache Iceberg#湖仓一体#数据仓库#事务处理英文
Databricks 图标

How our AI Research team uses AI Runtime

Databricks1423 字 (约 6 分钟)
85

Databricks AI研究团队通过AI Runtime实现大规模模型训练,提升8倍实验效率,集成MLflow和Unity Catalog优化GPU资源管理。

入选理由:AI Runtime支持从单GPU到数百GPU的弹性扩展,集成MLflow实现自动化实验

FeaturedArticle#AI Runtime#Databricks#GPU管理#MLflow#研究实践英文
Databricks 图标

Reducing Qwen training time by 6x on AI Runtime

Databricks2358 字 (约 10 分钟)
85

通过优化内核和数据管道,Databricks将Qwen 27B模型微调训练时间从7小时44分钟缩短至1小时17分钟,提升6倍。

入选理由:使用FSDP2和激活检查点技术可提升大模型训练效率

FeaturedArticle#AI训练优化#Databricks#Qwen#FSDP2英文
Databricks 图标

Power real-time applications and agents with Document Intelligence

Databricks854 字 (约 4 分钟)
85

Databricks推出实时文档处理API,通过同步REST接口实现文档解析、分类和决策,解决传统异步流程的效率瓶颈。

入选理由:Document Intelligence的ai_parse_document可将表格和图表转为结构化文本

FeaturedArticle#Document Intelligence#REST API#Databricks#实时处理英文
Databricks 图标

Introducing Private Network Gateway

Databricks1177 字 (约 5 分钟)
85

Databricks推出Private Network Gateway(PNG),简化无服务器工作负载连接私有网络,提升安全性与效率。

入选理由:PNG通过一次网络配置替代多个连接,减少75%的网络配置复杂性

FeaturedArticle#Databricks#网络#无服务器计算#云服务英文
Databricks 图标

Sizing Lakebase Search: lessons from a real app and 4 million passages

Databricks4039 字 (约 17 分钟)
85

Lakebase Search通过PostgreSQL扩展实现混合搜索,优化缓存和索引策略可显著降低延迟并控制成本。

入选理由:本地文件缓存匹配向量索引可使95-98%页面保留在内存,延迟降至毫秒级

FeaturedArticle#PostgreSQL#向量搜索#BM25#Lakebase#数据库优化英文
Databricks 图标

加州通过Databricks平台整合58个县行为健康数据,建立首个统一公共仪表盘,实现数据标准化和透明化治理。

入选理由:加州整合58个县数据到Databricks平台,统一管理4000万居民行为健康信息

FeaturedArticle#Databricks#数据治理#公共部门#大数据平台英文
Databricks 图标

Solving defense supply chain visibility through governed data sharing

Databricks1474 字 (约 6 分钟)
85

Databricks通过联邦数据交换解决国防供应链可见性问题,实现实时成本和供应链数据共享,无需供应商锁定。

入选理由:联邦数据交换使200,000+供应商实时共享验证数据,无需暴露源系统

FeaturedArticle#联邦数据交换#数据治理#Databricks#供应链管理英文
Databricks 图标

Introducing Funke: Native HL7v2 Parsing on Databricks

Databricks1479 字 (约 6 分钟)
85

Databricks推出Funke,原生解析HL7v2医疗消息为Spark数据结构,无需FHIR转换或第三方工具。

入选理由:Funke使用Python/PySpark重写,集成Unity Catalog和Spark Declarative Pipelines

FeaturedArticle#HL7v2#Databricks#Spark#开源#医疗数据英文
Databricks 图标

Announcing Workday Data Connect federation in Unity Catalog

Databricks1699 字 (约 7 分钟)
85

Databricks推出Workday Data Connect联邦连接器,实现零拷贝访问Workday数据并集成到Unity Catalog中。

入选理由:零拷贝访问:通过Workday Data Connect连接器,Unity Catalog可直接读取Workday的Iceberg表,无需数据复制。

FeaturedArticle#Unity Catalog#Workday Data Connect#数据联邦#Databricks英文

与「Databricks」经常一起出现的 AI 术语。

💡 想追踪「Databricks」的长期趋势?去 实体雷达 · Databricks 查看详细分析和跨材料问答。

AI may generate inaccurate information. Please verify important content.