T
traeai
Sign in

traeai topic radar

大模型评测、Benchmark 与生产质量监控

覆盖 LLM eval、benchmark、人工评测、自动评分、Evals、回归测试、幻觉检测与模型选择。

What searchers are trying to solve

想比较模型质量、设计评测集,并建立上线后的质量监控流程。

Why this is worth tracking

模型更新速度太快,没有评测闭环就无法判断新模型是否真的适合自己的业务。

LLM 评测LLM evalbenchmarkEvals模型选择幻觉检测回归测试自动评分

长尾组合

这个专题可以沿着工具、实践、对比等搜索意图持续扩展,不靠空壳换词,而是用真实材料更新。

LLM 评测 工具LLM 评测 实践LLM 评测 对比LLM eval 工具LLM eval 实践LLM eval 对比benchmark 工具benchmark 实践

可自动化内容模块

精选材料

持续抓取与 大模型评测 相关的高分文章、播客、视频和推文。

趋势判断

把最近变化、反复出现的观点和争议点整理成稳定摘要。

实体关联

自动连接相关公司、模型、产品、人物和概念,形成可继续深挖的入口。

Featured content

Filtered by relevance, score, and recency.

Search more
Frontier models are powerful advisors.

Frontier models are powerful advisors.

Fireworks AI(@FireworksAI_HQ)188 字 (约 1 分钟)
87

Fireworks AI demonstrates that GLM 5.1, when using Claude Opus 4.7 as a sparse advisor in the Legal Agent Benchmark, achieves 18/100 all-pass versus 14/100 for Opus alone at 39% of the cost.

入选理由:On the Legal Agent Benchmark, GLM 5.1 with Claude Opus 4.7 as a sparse advisor r

FeaturedTweet#Frontier Models#Legal Agent Benchmark#harness design#advisor pattern#Claude Opus 4.7英文
How DoorDash Built a Testing System to Evaluate LLMs

How DoorDash Built a Testing System to Evaluate LLMs

ByteByteGo Newsletter2258 字 (约 10 分钟)
87

DoorDash built a 'simulation and evaluation flywheel' system that uses offline realistic multi-turn conversation simulation and automated grading to reduce LLM chatbot hallucination fixes from weeks to hours, dramatically improving iteration speed and deployment confidence.

入选理由:Offline simulator generates test conversations without real users, eliminating p

FeaturedArticle#LLM#Testing System#DoorDash#AI Engineering#Hallucination Detection英文
Ghost AI: Let’s AI Agents Build Disposable Worlds

Ghost AI: Let’s AI Agents Build Disposable Worlds

Wes Roth5242 字 (约 21 分钟)
87

Ghost AI proposes disposable database copies for AI Agents to safely experiment with data-layer changes; the author validates LLMs’ physics-control learning via the Gravell GPT benchmark with 30 iterative feedback rounds.

入选理由:Direct database access for AI Agents is highly risky; each agent must be given a

FeaturedVideo#AI Agents#Database Safety#LLM Benchmark#Simulation英文
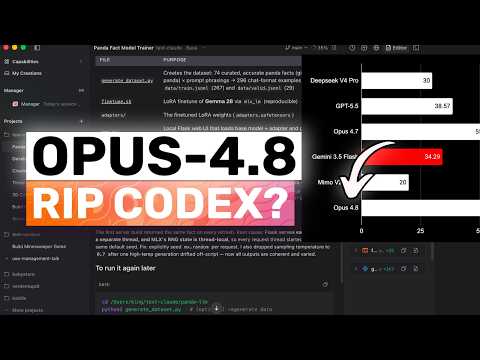
Opus 4.8 (Fully Tested): Is IT ACTUALLY GOOD?

Opus 4.8 (Fully Tested): Is IT ACTUALLY GOOD?

AICodeKing3777 字 (约 16 分钟)
87

Claude Opus 4.8 scores 87.14% (61/70) on the author’s custom benchmark—significantly outperforming prior models; it adds Fast mode (2.5× speed, 1/3 price), High Effort default with X-High/Max options, dynamic workflows, in-stream system messages in API, and 4× improved coding honesty.

入选理由:Opus 4.8 scores 61/70 (87.14%) on a 70-question custom benchmark, beating GPT-4.

FeaturedVideo#Claude#LLM#Anthropic#AI Coding#Benchmark英文
Claude Opus 4.8 is here. Is it as good as they say?

Claude Opus 4.8 is here. Is it as good as they say?

Lenny's Newsletter1002 字 (约 5 分钟)
87

Opus 4.8 scores 69.2% on Sweet Bench Pro—~5 pts above Opus 4.7, ~10 above GPT-4.5—but real-world coding reveals persistent ‘last 10%’ failures and hallucinations; pricing is steep at $5/k input tokens.

入选理由:Scores 69.2% on Sweet Bench Pro, +5 pts vs Opus 4.7, +10 vs GPT-4.5, +15 vs Gemi

FeaturedArticle#Claude#LLM#Anthropic#AI coding#benchmark英文
VSCode Team Introduces Five Pillars of Agent-First Development

VSCode Team Introduces Five Pillars of Agent-First Development

meng shao(@shao__meng)926 字 (约 4 分钟)
87

VSCode team proposes five pillars of Agent-First Development: model selection, action boundaries, context, prompt precision, and tool control, emphasizing the shift from human+editor to human+Agent+editor development paradigm, improving AI programming efficiency through fine-grained configuration.

入选理由:Copilot provides four levels of thinking depth (Low/Medium/High/Auto) to match d

FeaturedTweet#VSCode#Agent-First#Copilot#AI Programming中文
SocialReasoning-Bench: Measuring whether AI agents act in users’ best interests

SocialReasoning-Bench: Measuring whether AI agents act in users’ best interests

Microsoft Research Blog3099 字 (约 13 分钟)
87

SocialReasoning-Bench reveals that current frontier AI models often accept suboptimal outcomes when negotiating on behalf of users, despite completing tasks successfully.

入选理由:In calendar coordination, frontier models accept meeting times more than 15% bel

FeaturedArticle#AI Agent#Social Reasoning#Benchmark#Microsoft Research英文
Databricks 图标

Databricks leverages MemAlign to enhance the evaluation of Genie Code’s traditional ML code generation, enabling automated 9-dimensional scoring via LLM judges and significantly narrowing the gap with human experts.

入选理由:MemAlign increases LLM judge agreement with human experts to 0.85 correlation.

FeaturedArticle#Genie Code#MLflow#MemAlign#LLM Evaluation#Machine Learning英文
Your RAG System Produces 'Higher-Fluency Hallucinations'

Your RAG System Produces 'Higher-Fluency Hallucinations'

Weaviate • vector database(@weaviate_io)245 字 (约 1 分钟)
87

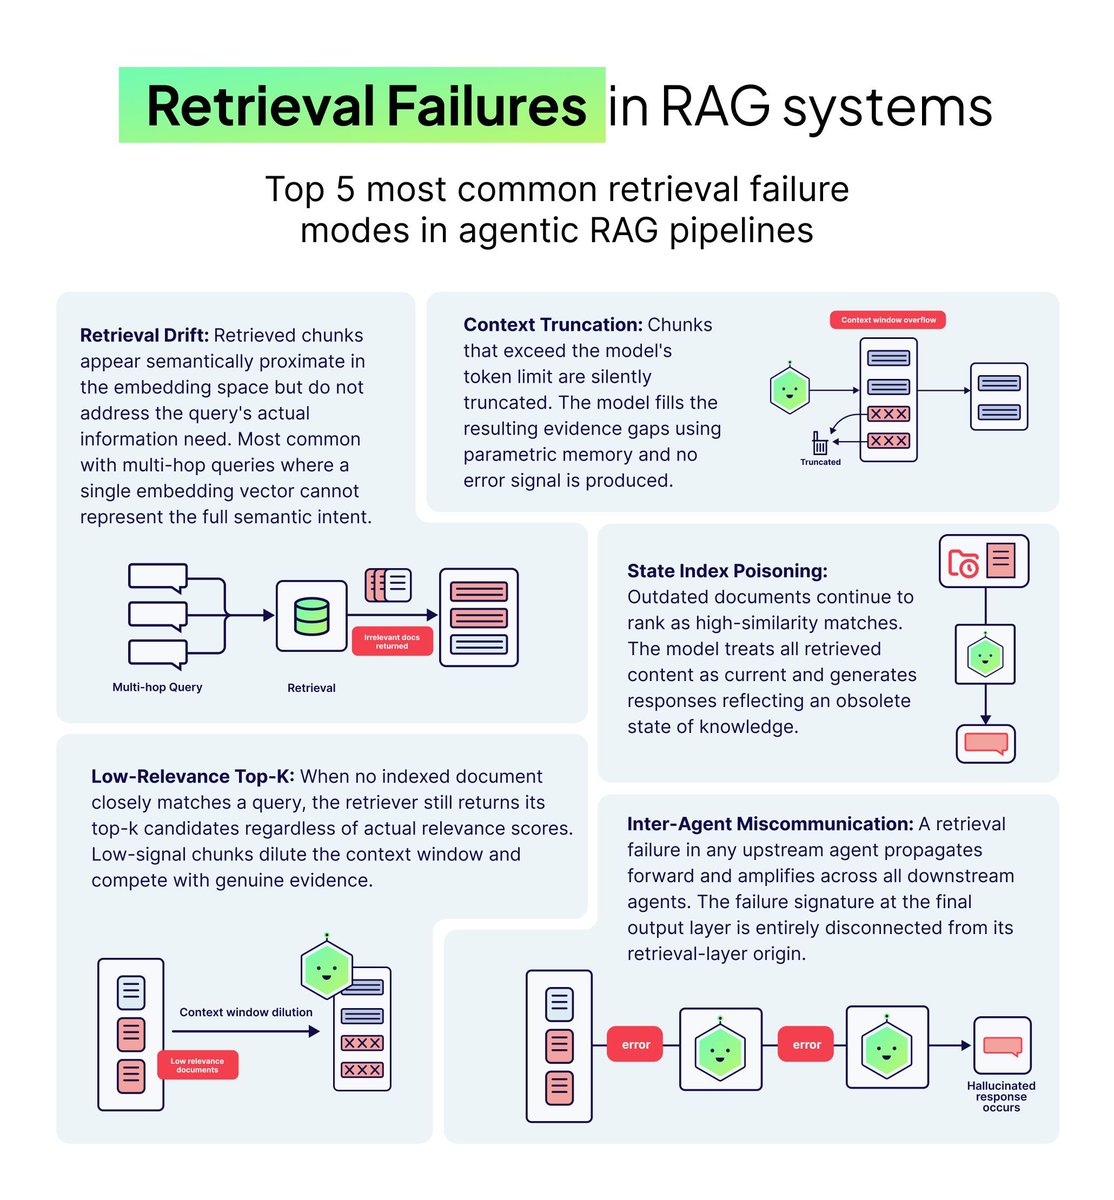
Research reveals poor retrieval quality is the primary cause of high-fluency hallucinations in RAG systems—more convincing, confident, and wrong—while scaling models fails to fix the root issue.

入选理由:Poor retrieval quality is the strongest predictor of degraded RAG output; larger

FeaturedTweet#RAG#Vector Database#Weaviate#LLM#Hallucination Detection中英混合
QIMMA قِمّة ⛰: A Quality-First Arabic LLM Leaderboard

QIMMA قِمّة ⛰: A Quality-First Arabic LLM Leaderboard

Hugging Face Blog1876 字 (约 8 分钟)
87

QIMMA是首个对阿拉伯语LLM基准进行质量预验证的排行榜,揭示现有评测集普遍存在翻译失真、标注错误等问题,确保模型评分真实反映阿拉伯语能力。

入选理由:多数阿拉伯语基准未经过质量验证,存在翻译偏差和标注错误,影响评估可信度。

FeaturedArticle#LLM#阿拉伯语NLP#Benchmark#HuggingFace#AI评估英文
How We Benchmark ARIA—and Why It Runs on Weave

How We Benchmark ARIA—and Why It Runs on Weave

CoreWeave2786 字 (约 12 分钟)
85

CoreWeave通过Weave平台实现ARIA的生产对齐评估,确保基准测试与实际运行环境一致。

入选理由:生产环境重试成功不等于问题解决,需对比配置变更效果

FeaturedArticle#ARIA#Weave#基准测试#生产环境#CoreWeave英文
Advanced evals: How to find (and fix) hidden AI failures in your product

Advanced evals: How to find (and fix) hidden AI failures in your product

Lenny's Newsletter3317 字 (约 14 分钟)
85

AI产品评估(evals)是AI产品经理的核心技能,能系统性提升产品效果,Shopify等公司通过evals实现效率和成本的显著优化。

入选理由:Shopify用evals使AI工作流构建速度提升2.2倍,成本降低68%。

FeaturedArticle#AI产品#评估系统#工程实践#AI优化英文
Benchmarking Local LLM Servers: llama.cpp, llamafile, LM Studio, and Ollama

Benchmarking Local LLM Servers: llama.cpp, llamafile, LM Studio, and Ollama

Mozilla AI Blog3105 字 (约 13 分钟)
85

配置优化对本地LLM服务器性能影响显著,不同平台的设置可带来最高63%的性能提升。

入选理由:启用CUDA graphs可使L40S解码速度提升16.8%(0.8B模型)

FeaturedArticle#LLM#性能优化#本地服务器#benchmarking英文
MLCommons 图标

MLPerf Inference v6.1引入端到端RAG和边缘代理推理测试,性能较去年提升5.7倍,推动AI部署标准化。

入选理由:MLPerf v6.1新增End-to-End RAG和Edge Agentic Inference测试,覆盖复杂AI部署场景。

FeaturedArticle#MLPerf#AI推理#基准测试#边缘计算英文
AI Musings by Mu 图标

What AI enterprise leaders care about

AI Musings by Mu491 字 (约 2 分钟)
85

企业AI部署聚焦ROI测算困难、成本控制、网络安全和开源采用,但ROI与成本管理成CEO级优先事项,开源仍处早期阶段。

入选理由:90%的token支出集中在编码,但ROI测算困难

FeaturedArticle#AI企业#成本管理#网络安全#开源技术#模型选择英文
Ethan Mollick(@emollick) 图标

Epoch AI推出Benchmark Reviews项目,揭示当前AI基准测试存在严重缺陷,15个基准中9个被标记为有缺陷。

入选理由:Epoch AI审计发现15个AI基准中9个存在严重缺陷

FeaturedTweet#AI#基准测试#Epoch AI#技术评估英文

Related topics

跨材料问答 · 大模型评测、Benchmark 与生产质量监控

回答基于:大模型评测、Benchmark 与生产质量监控 专题下 19 条材料
    0 / 500

    AI may generate inaccurate information. Please verify important content.