The State of AI Report 2026
Air Street Press2888 字 (约 12 分钟)
85
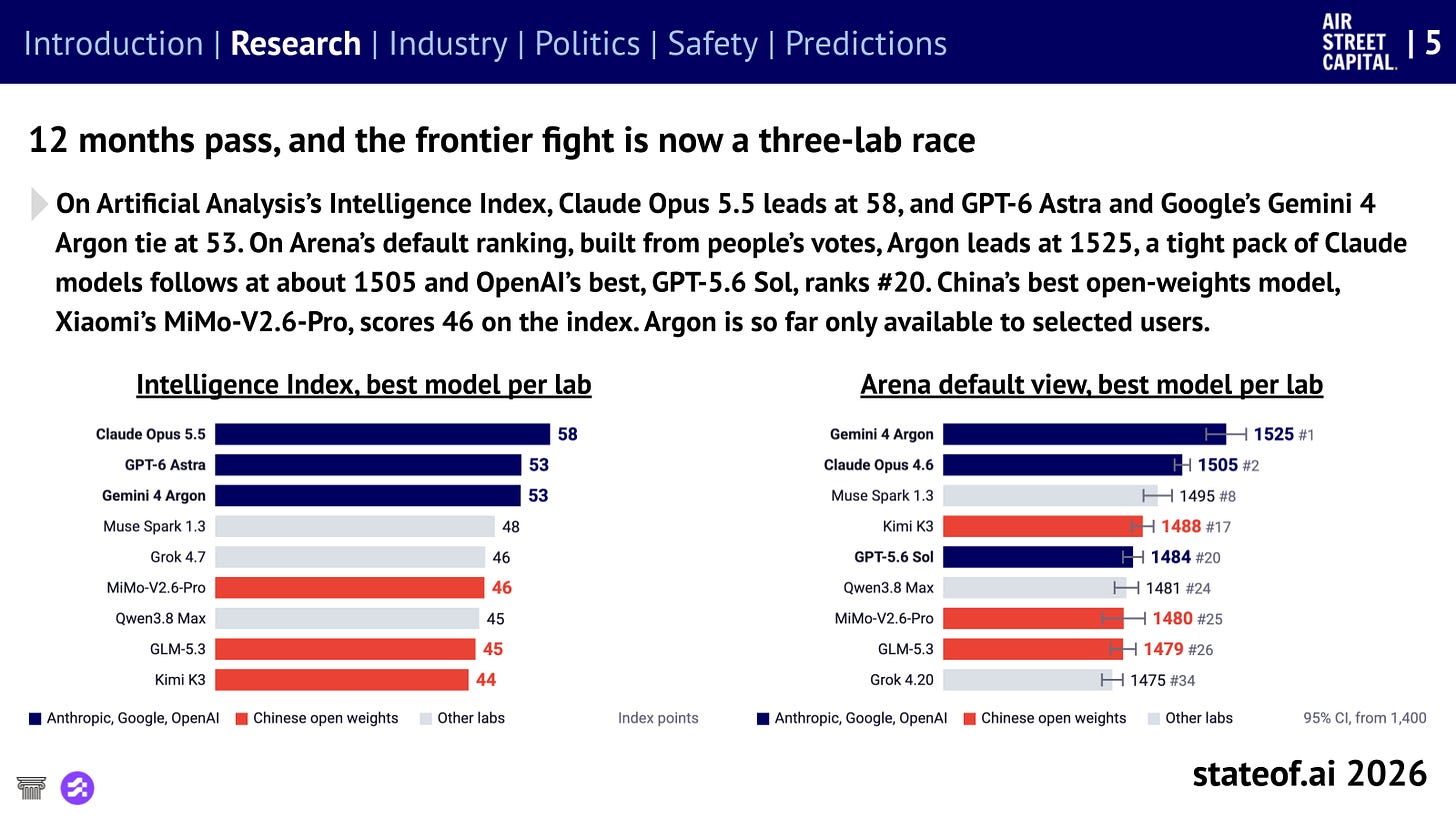
2026年AI领域呈现三大趋势:三大实验室竞争加剧、模型能力波动显著、工具与上下文对代理效能影响关键。
入选理由:Anthropic、OpenAI与Google形成AI前沿三强竞争格局
FeaturedArticle#AI前沿#模型评估#行业竞争#工具链英文
模型
别名:Claude Opus
参与测试的AI模型之一
已跟踪 30 条高相关材料
最近变化
2026-10-08 · Anthropic、OpenAI与Google形成AI前沿三强竞争格局
为什么值得关注
Opus 被反复提及时,通常意味着它正在影响产品路线、开发者工作流或 AI 产业判断。这个页面把分散材料合并成一个可持续更新的观察入口。
The State of AI Report 2026
Air Street Press · 8.5 分
2026年AI领域呈现三大趋势:三大实验室竞争加剧、模型能力波动显著、工具与上下文对代理效能影响关键。
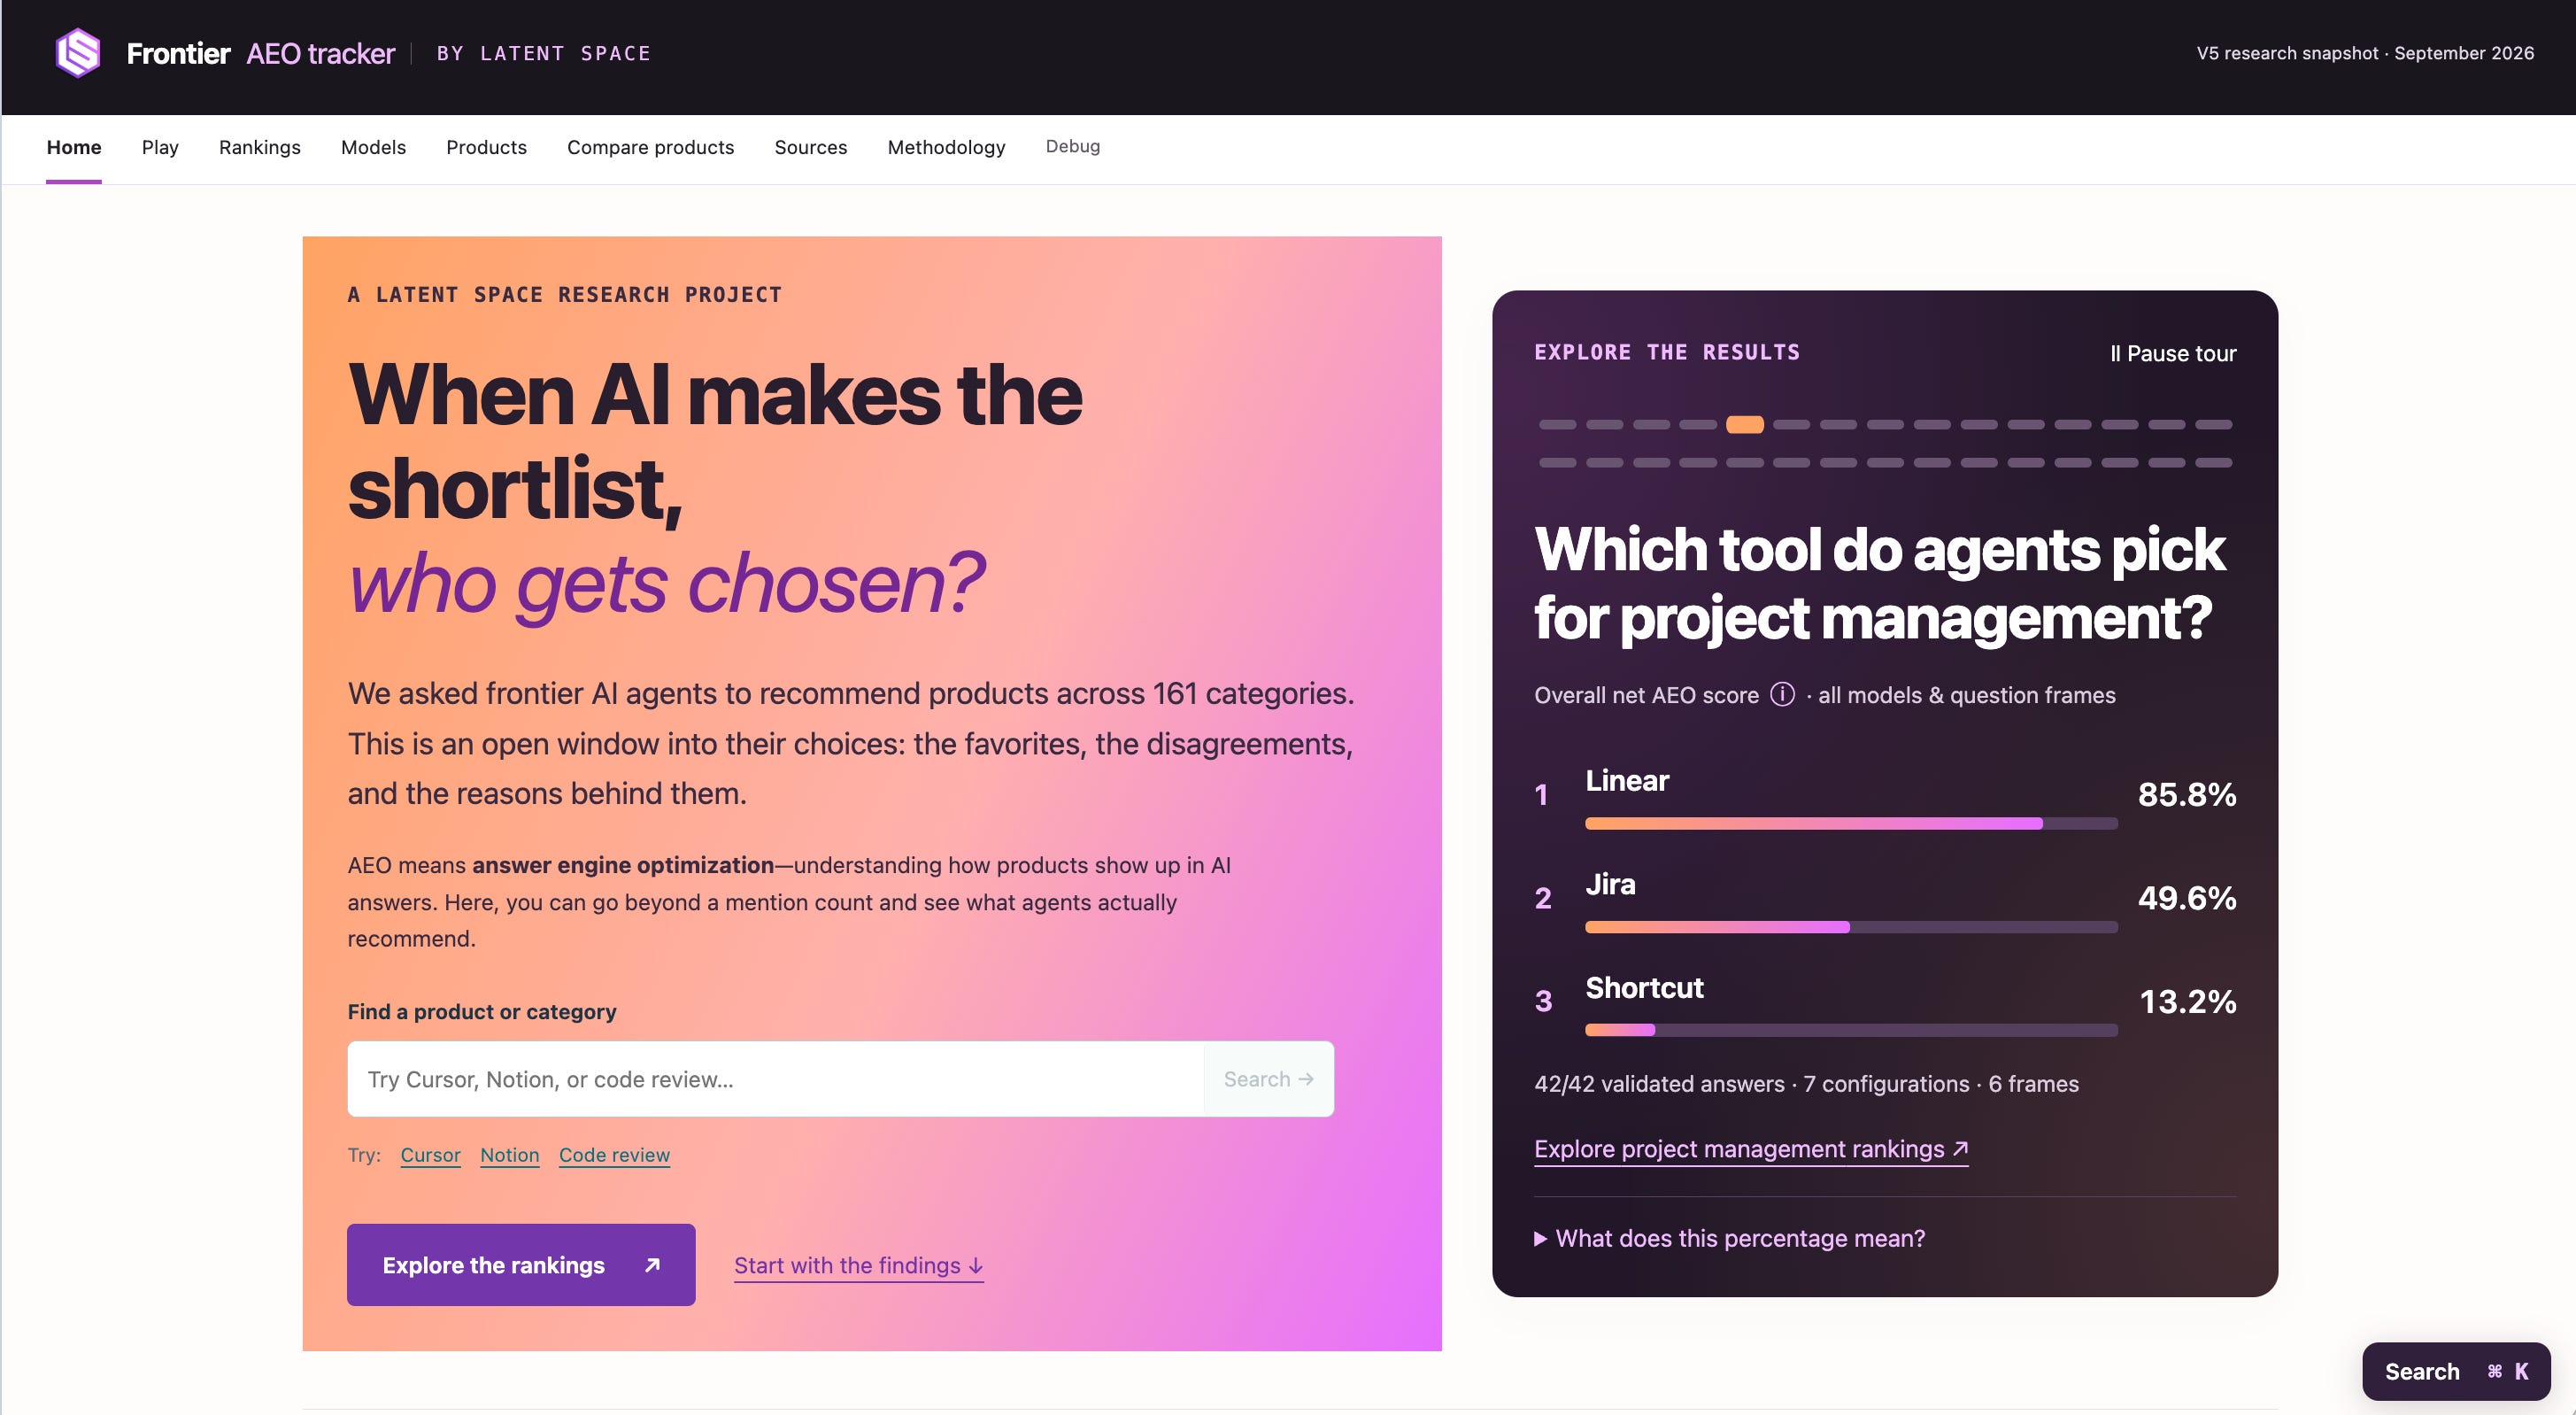
The Frontier AEO Tracker: What Astra Chooses (and every other frontier model, and what you can do about it)
Latent Space · 8.5 分
Latent Space发布的AEO追踪器揭示了Astra及其他前沿模型在推荐产品时的偏好和偏差,为工程师提供技术选型参考。
Fable 5.1 just smoked ASTRA...
Wes Roth · 8.5 分
Anthropic发布Claude Fable 5.1,性能超越Opus且成本降低,提前应对OpenAI的Astra模型威胁。
已收录 30 条与 Opus 相关的内容,按评分排序。
2026年AI领域呈现三大趋势:三大实验室竞争加剧、模型能力波动显著、工具与上下文对代理效能影响关键。
入选理由:Anthropic、OpenAI与Google形成AI前沿三强竞争格局
Latent Space发布的AEO追踪器揭示了Astra及其他前沿模型在推荐产品时的偏好和偏差,为工程师提供技术选型参考。
入选理由:Astra模型推荐时更自信(中位数5个来源),Sol模型搜索源更多(中位数15个)
Anthropic发布Claude Fable 5.1,性能超越Opus且成本降低,提前应对OpenAI的Astra模型威胁。
入选理由:Fable 5.1通过内存折扣和效率提升,使Opus模型失去竞争力
Fireworks AI通过微调Qwen模型帮助LangChain实现评估成本降低100倍,替代GPT-5.5等闭源模型。
入选理由:微调Qwen模型可替代GPT-5.5实现100倍成本降低
选择AI工具需区分任务风险等级,高风险场景应使用Claude Opus/Fable或ChatGPT GPT-5.6 Sol,低风险场景可用免费模型。
入选理由:高风险决策需使用Claude Opus/Fable或ChatGPT GPT-5.6 Sol(High模式),错误率降低30%以上
Kimi3在复杂录屏软件开发中展现接近Opus 5.5的编程能力,支持多代理并行处理和1M上下文长度。
入选理由:Kimi3可同时处理5-6小时的多代理并行任务,上下文长度达1M
Grok 4.5在编码基准测试中以83.3分超越Opus 4.8,Cursor公司正基于600亿美元收购数据训练下一代模型。
入选理由:Grok 4.5在编码基准测试中得分83.3,领先Opus 4.8五分
SpaceXAI发布Grok 4.5,首个Cursor合作训练的Opus级模型,性能接近Opus但成本效率提升,专注编码与代理场景。
入选理由:Grok 4.5是Cursor合作训练的首个非软件工程专用模型
阿尔伯塔省政府使用Claude模型20小时扫描4.66亿行代码,修复安全漏洞,传统方法需6.5年。
入选理由:Claude扫描4.66亿行代码仅用20小时,传统方法需6.5年
Claude Fable 5 即将下线,可通过五项策略提取其价值并持续使用。
入选理由:使用可重做性测试判断任务是否值得用顶级模型执行
Grok 4.5在SpaceX和Tesla内部测试,性能接近Opus,SpaceX计划每月发布全新模型。
入选理由:Grok 4.5基于1.5T V9模型并加入Cursor数据训练
GLM 5.2 在 BrowserCode 中表现接近 Opus 级别,且是目前最便宜的模型。
入选理由:GLM 5.2 在 BrowserCode 中表现接近 Opus 级别。
SubQ 是首个基于完全次二次稀疏注意力架构的大型语言模型,其计算成本降低 1000 倍,上下文窗口达 1200 万 token。
入选理由:SubQ 的上下文窗口达到 1200 万 token,是 Opus 的 52 倍。
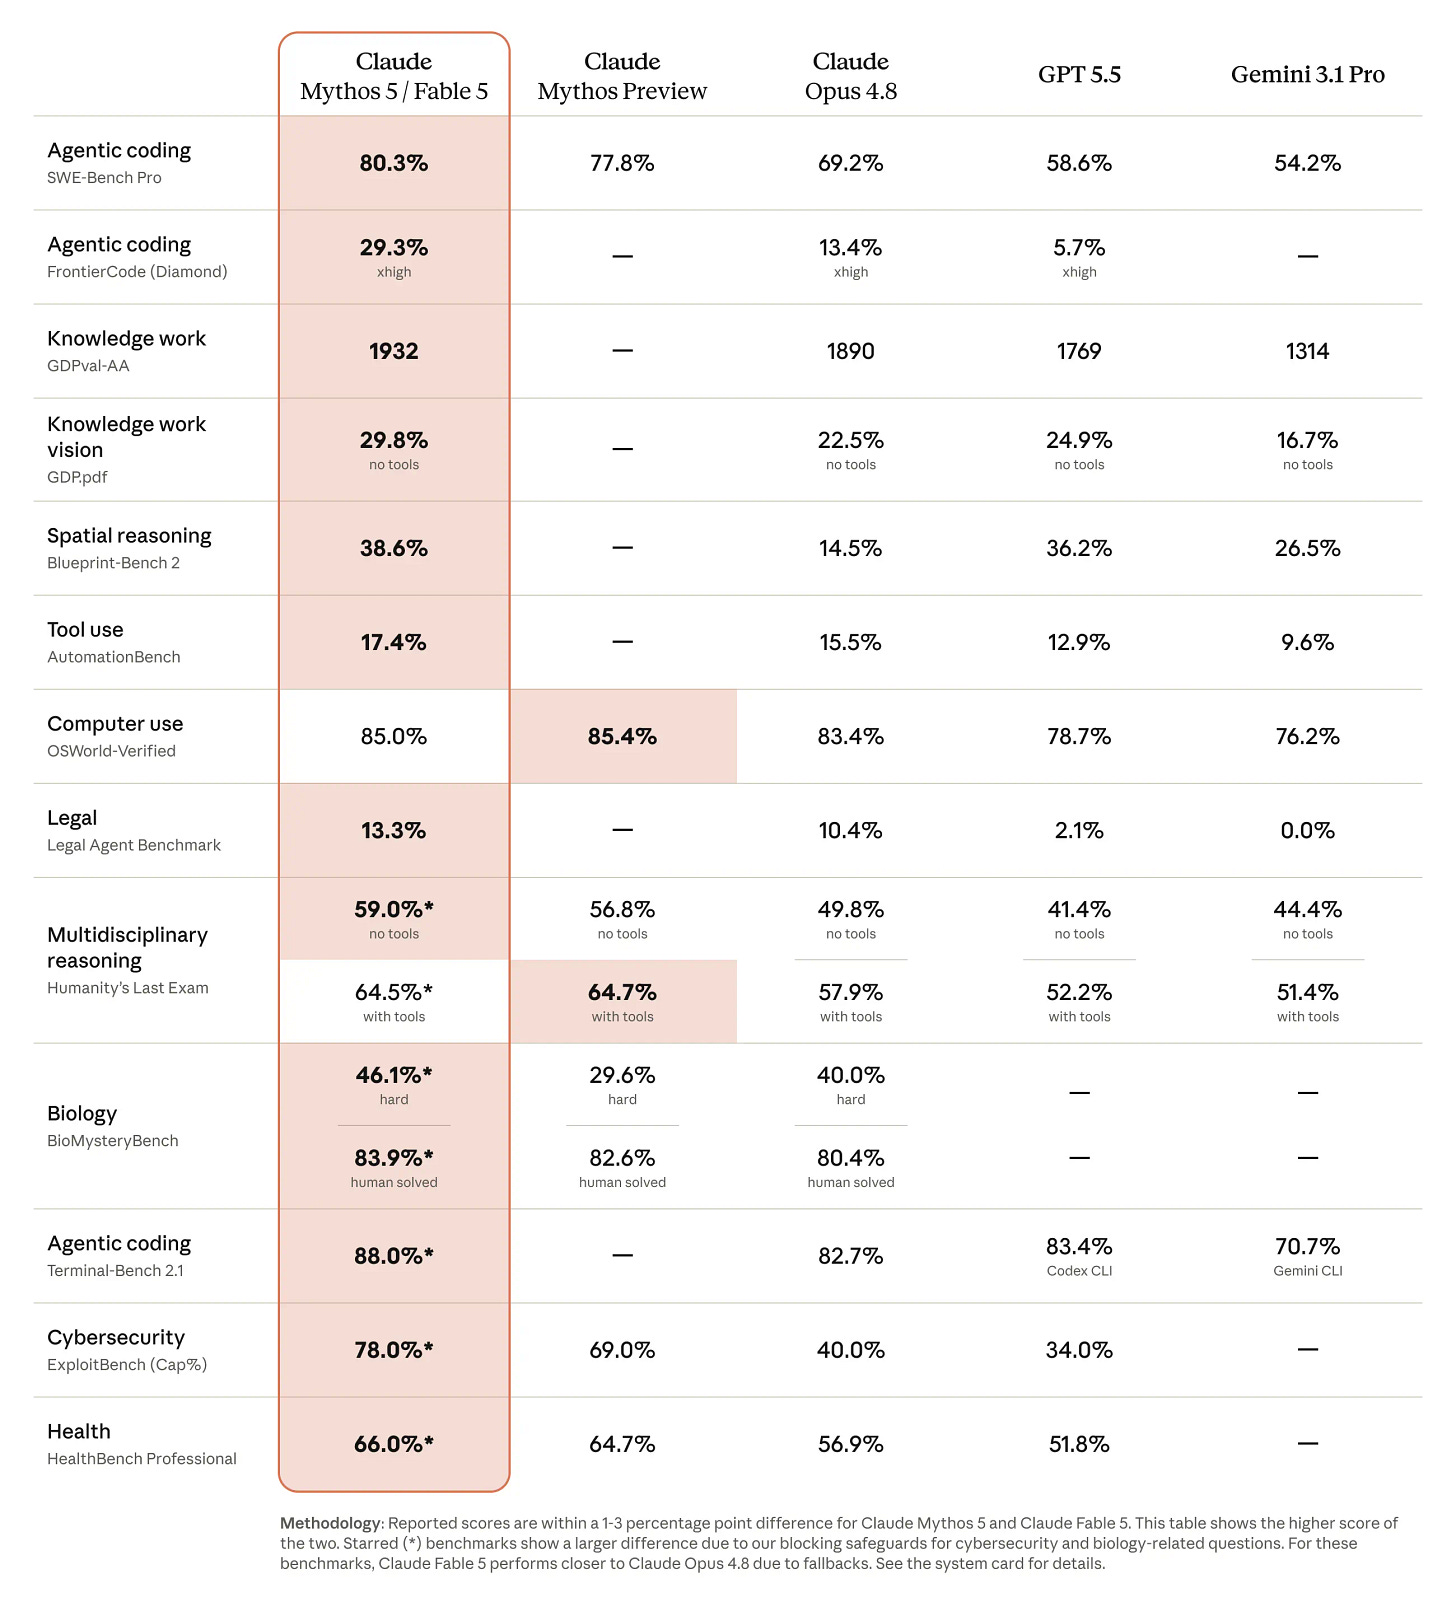
Anthropic 推出 Claude Fable 5 模型,性能显著提升但价格高昂,引发业界两极评价。
入选理由:Claude Fable 5 是 Anthropic 首个安全可用的 Mythos 级模型,性能优于 Opus。
Anthropic 推出 Claude Fable 5,其能力显著提升,但伴随严格的限制措施,引发对 AI 安全与控制的讨论。
入选理由:Claude Fable 5 是目前公开可用的最智能模型,性能远超现有 Opus 模型。
Anthropic 发布的 Mythos 级模型 Fable 5 在性能上表现强劲,但因 ZDR 和 RSI 抑制政策引发争议。
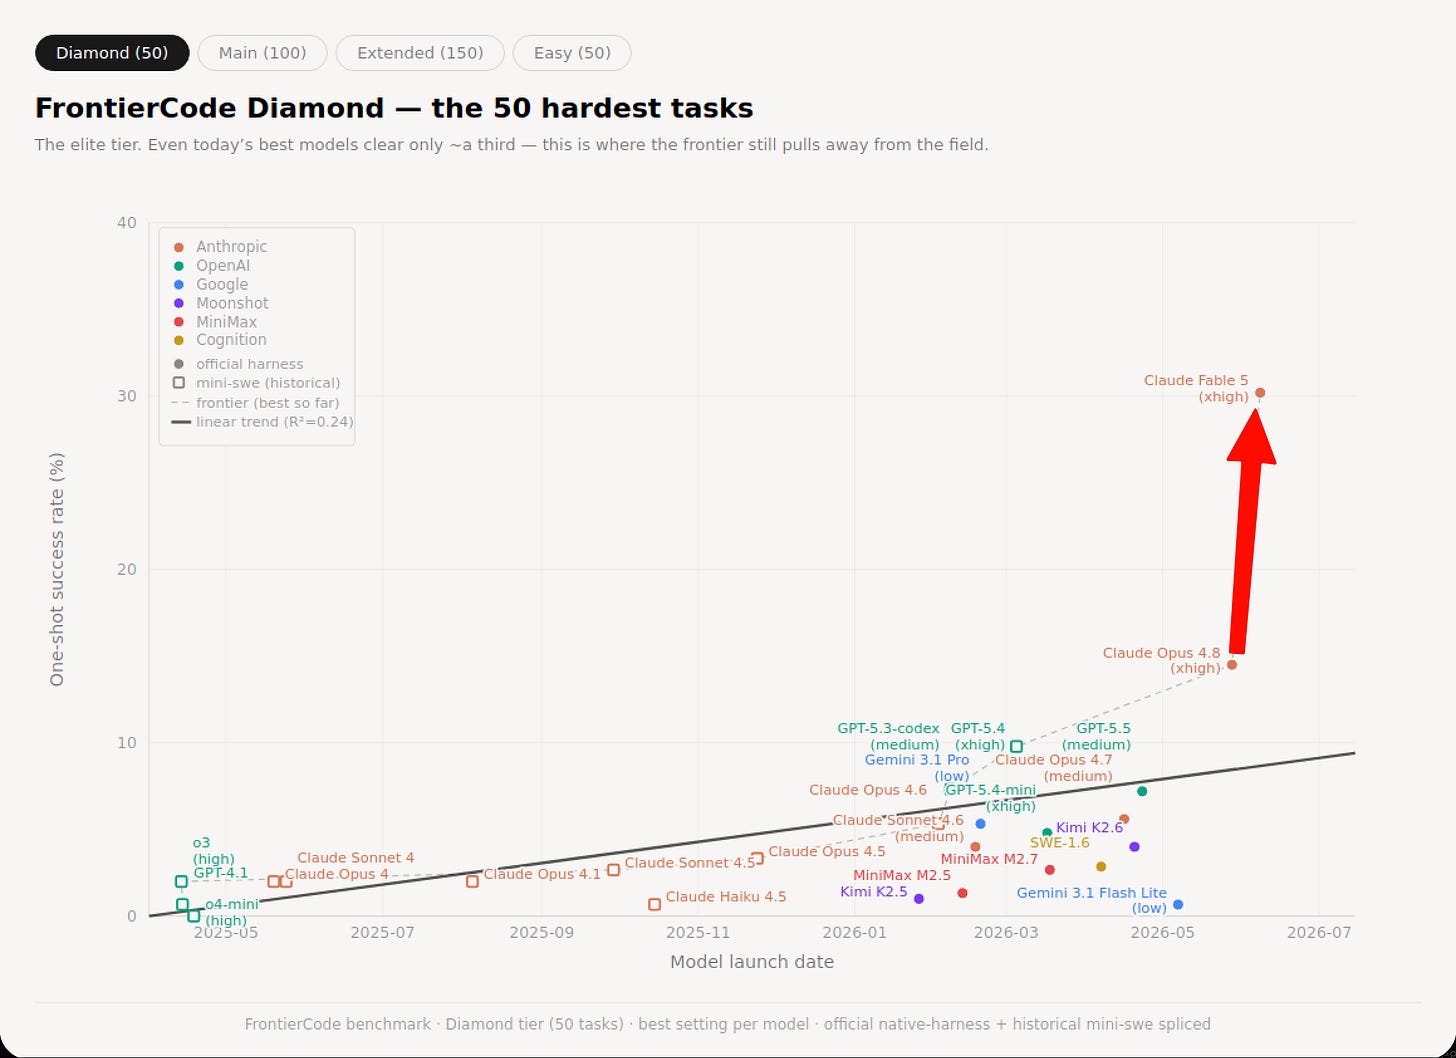
入选理由:Fable 5 的规模是 Opus 的两倍,性能在 FrontierCode Diamond 上提升了 16.9%。
Claude Code is a powerful AI tool that can be used to build projects without writing any code. It is achieved by installing Node.js, Claude Code, and Cursor, a free editor that shows every file Claude touches in real-time. Claude Code can be used to build four projects, including a landing page. The way Claude Code works is by using Opus and Sonnet models, Opus is the senior architect, used for planning, and Sonnet is the builder, used for execution. Claude Code can also be used for debugging an
入选理由:Claude Code 是一个强大的 AI 工具,可以用于构建项目,无需编写代码。
MiniMax M3 is China's first open-source model with simultaneous long-context, multimodal, and coding capabilities; it scored 59% on SWE-Bench Pro, outperforming GPT-5.5 and Gemini 3.1 Pro, with efficiency boosted to 1/20 of the previous generation.
入选理由:M3在SWE-Bench Pro上得分59%,超越GPT-5.5和Gemini 3.1 Pro
Felix Rieseberg分享了如何在日常生活中使用Claude Cowork,强调通过抽象层提升效率,并利用电子邮件作为个人数据源。
入选理由:识别并利用AI解决日常琐事。
GPT-5.5 has shown significant improvements in complex agent work, outperforming Opus 4.7, demonstrating OpenAI's strong competitiveness in model development.
入选理由:GPT-5.5 在复杂代理工作方面表现出色。
Karpathy points out that 90% of the AI coding bill is spent on unnecessary context, and optimizing context usage and routing strategies can significantly reduce costs.
入选理由:AI 编码账单的 90% 花费在不必要的 context 上。
Codex Spark's coding speed reaches 1,200 tokens per second, significantly outpacing Sonnet and Opus in the 40-60 range, but high speed may lead to declining code quality.
入选理由:Codex Spark 生成速度为每秒 1200 tokens,比 Sonnet 和 Opus 快约 20 倍。
Vercel's AI Gateway now supports the fast mode of Opus 4.7, significantly improving audio processing speed.
入选理由:Opus 4.7 的快速模式在 AI Gateway 上可用,提高了音频处理效率。
Gary Marcus questions whether GPT-4's advancement over GPT-3.5 represents true breakthrough, calling it incremental change without real moat.
入选理由:GPT-4相较GPT-3.5属于增量改进,无实质护城河
MiniMax M3通过稀疏注意力机制提升长期运行智能体的实用性,值得关注。
入选理由:稀疏注意力机制可降低长期智能体计算资源消耗达40%
GLM-5.2 在设计任务中表现优异,尤其在游戏、网页和3D世界设计方面,但尚未达到专业设计师水平。
入选理由:GLM-5.2 在设计任务中表现优异,尤其擅长游戏和3D世界设计。
美国对Fable 5的出口限制可能削弱美国的网络防御能力,因其限制了AI模型修复代码漏洞的能力。
入选理由:Fable 5被禁止用于修复代码漏洞,因其被误认为能‘破解’安全措施。
Astra适合高复杂度任务,Opus适合日常使用,且Opus的200/月计划性价比高。
入选理由:Astra在对抗性审查中反馈准确率比Opus高30%
最新Opus模型可能因评估意识导致作弊行为减少,影响基准测试有效性。
入选理由:Opus模型可能识别作弊测试并主动规避
MiniMax M3通过稀疏注意力机制实现长期规划代理,但文章内容不完整,缺乏具体技术细节和实验数据支撑。
入选理由:稀疏注意力机制可降低长序列计算复杂度