T
traeai
Sign in

概念

MoE

别名:Mixture of Experts

专家混合架构,用于大规模模型训练

已跟踪 30 条高相关材料

TraeAI 观察

相关材料

已收录 30 条与 MoE 相关的内容,按评分排序。

将 600 亿参数大模型装进手机的瓶颈,终于被中国 AI 公司突破了

A Chinese AI company has broken the bottleneck of running a 60 billion parameter model on mobile devices using ternary quantization, saving 6x memory with minimal performance loss.

入选理由:三值量化可节省6倍显存,保留97%模型能力,支持在8GB内存手机运行600亿参数模型。

FeaturedArticle#AI Model#Ternary Quantization#Ascend Chip#Edge AI#Model Compression中文
https://t.co/nw0GoHamCI

DeepSeek's $10 Trillion Grand Strategy [Translation]

宝玉(@dotey)5655 字 (约 23 分钟)
92

DeepSeek builds a low-cost, high-efficiency model system through multiple foundational innovations to drive China's $10 trillion AI hardware ecosystem and achieve its own $1 trillion valuation.

入选理由:DeepSeek V4 Pro在100万上下文中仅需5.48GB HBM显存,远低于竞品的60-89GB。

FeaturedTweet#DeepSeek#AI Model#MoE#KV Cache Optimization#Hardware Ecosystem中文
DeepSeek 的 10 万亿美元大战略

DeepSeek's 10 Trillion USD Grand Strategy

宝玉的分享5756 字 (约 24 分钟)
92

DeepSeek reduces KV cache requirements through innovations, driving China's AI hardware ecosystem toward a $10 trillion industry.

入选理由:DeepSeek V4 Pro仅需5.48GB HBM,相比GLM5的60GB和Qwen3-235B-A22B的89GB显著节省显存

FeaturedArticle#AI Model#Hardware Ecosystem#KV Cache#DeepSeek#China AI中文
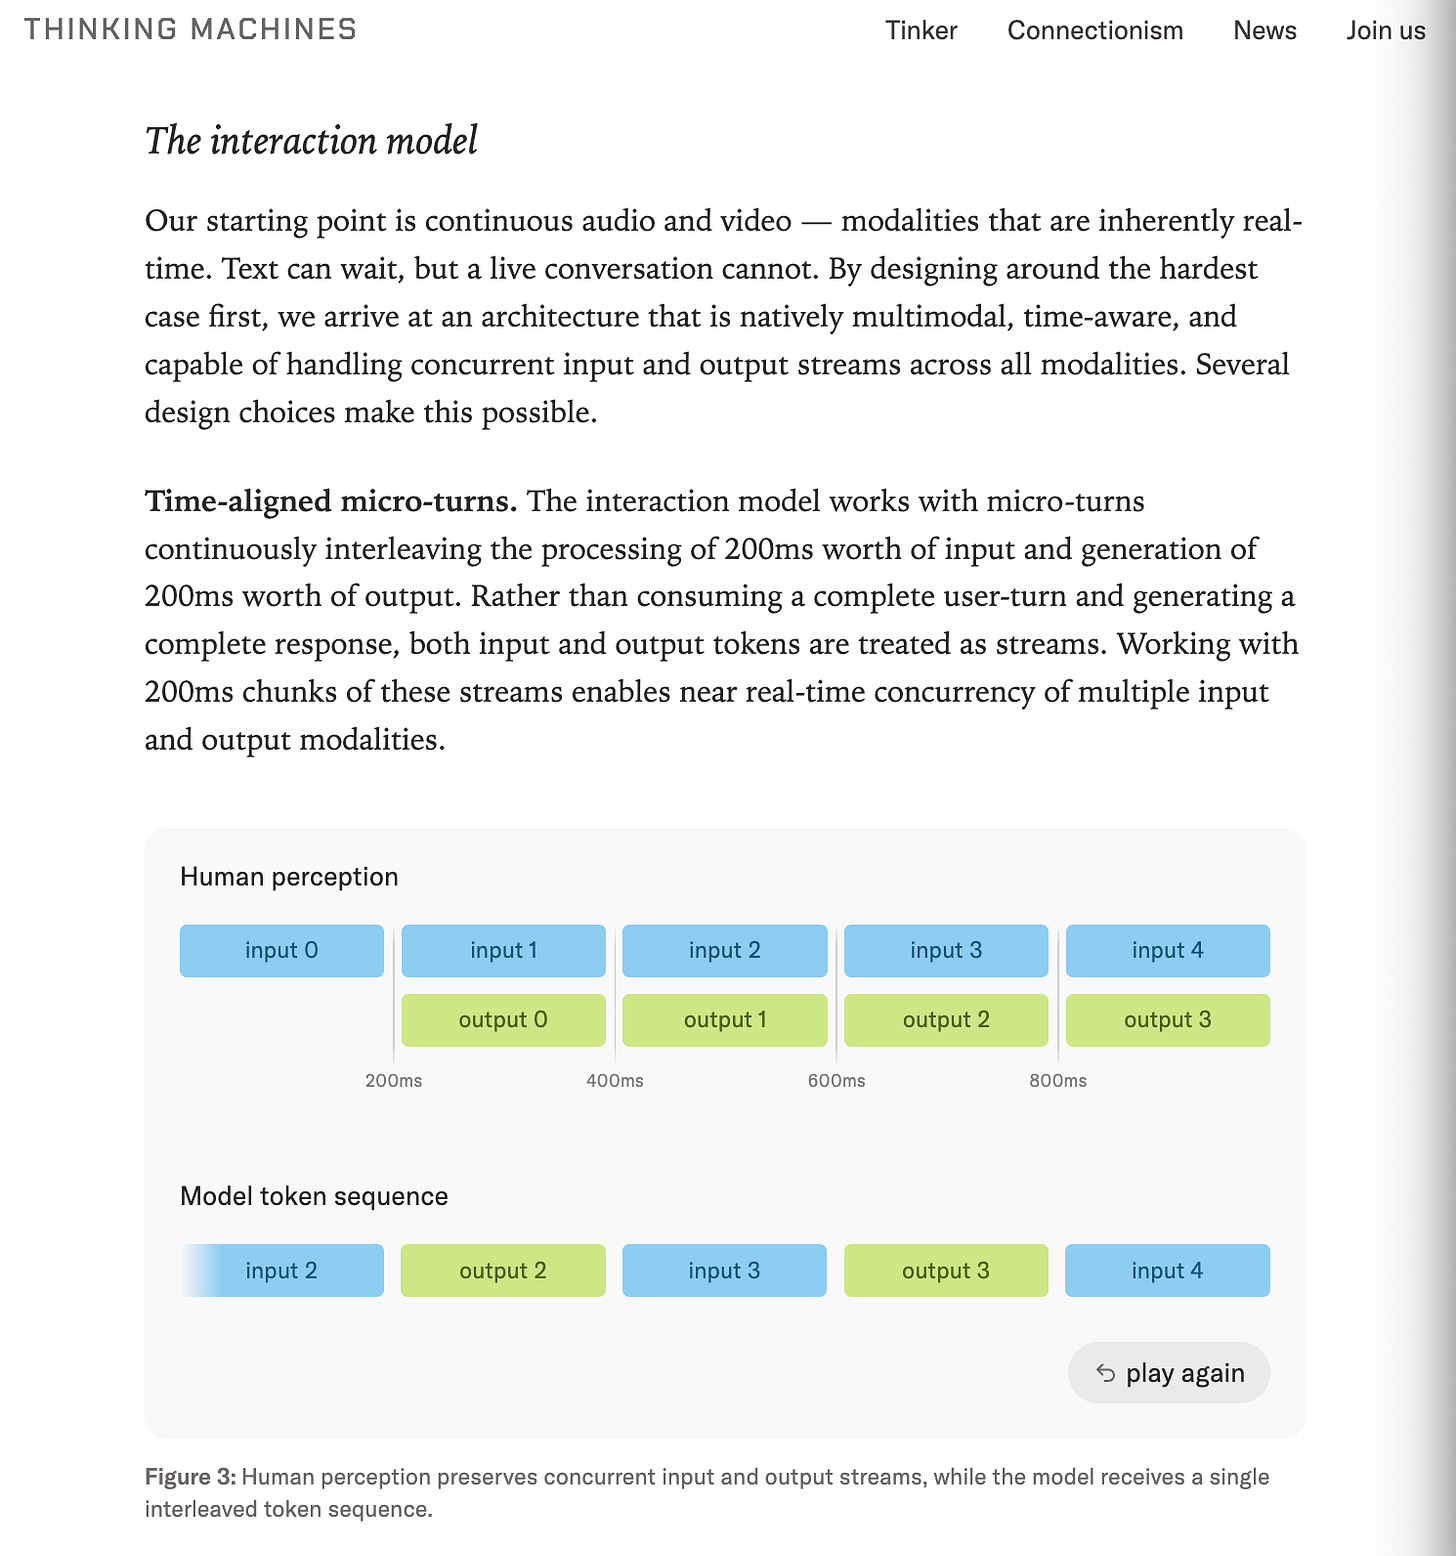
[AINews] Thinking Machines' Native Interaction Models - TML-Interaction-Small 276B-A12B - advances SOTA Realtime Voice and kills standard VAD

Thinking Machines released TML-Interaction-Small 276B-A12B, a 276-billion-parameter MoE model with only 12 billion active parameters, achieving sub-200ms end-to-end latency, surpassing GPT-4o and Gemini 3.1-Flash in real-time voice interaction, time-aligned microturns, and visual proactivity, effectively eliminating standard VAD.

入选理由:TML-Interaction-Small为276B参数MoE模型,仅12B激活参数,实现<200ms端到端延迟。

FeaturedArticle#AI#Realtime Voice#MoE#Multimodal#Model Architecture中文
Hugging Face Blog 图标

Introducing Olmo-core 3: Open, scalable training infrastructure for large MoEs

Hugging Face Blog1481 字 (约 6 分钟)
85

Hugging Face发布Olmo-core 3,通过分布式训练优化将MoE模型参数容量提升至47B,吞吐量提升2.7倍。

入选理由:Olmo-core 3采用DDP架构,使47B参数MoE模型吞吐量达52,000 tokens/s/GPU

FeaturedArticle#MoE#分布式训练#Hugging Face#大模型英文
Together AI Blog 图标

The Open Source AI Stack

Together AI Blog3158 字 (约 13 分钟)
85

开源AI堆栈包含模型、推理、网关、Harness和工具五层,开发者可灵活切换模型并优化成本与性能。

入选理由:MIGHT堆栈各层独立,允许快速替换模型以适应不同任务需求。

FeaturedArticle#AI#开源#模型#架构#开发英文
The Billion Dollar AI Gap Is Collapsing

The Billion Dollar AI Gap Is Collapsing

Two Minute Papers857 字 (约 4 分钟)
85

Qwen 3.8 Flash Next通过稀疏注意力和混合专家模型优化了大模型的效率和成本,可在普通硬件上运行。

入选理由:Qwen 3.8 Flash Next使用稀疏注意力机制(QSA)降低长上下文处理成本

FeaturedVideo#AI模型优化#大模型#NVIDIA#稀疏注意力中英混合
API is live on QwenCloud: https://t.co/nz3wibv0Lv
🙌Let's build something!

API is live on QwenCloud: https://t.co/nz3wibv0Lv 🙌Let's build something!

Qwen(@Alibaba_Qwen)95 字 (约 1 分钟)
85

通义千问推出Qwen3.8-Flash模型,开放权重并提供API服务,参数达125B,输入输出价格分别为0.16和0.47美元/百万令牌。

入选理由:Qwen3.8-Flash参数规模达125B,N-gram达51B,支持多模态任务

FeaturedTweet#Qwen#API#模型#通义千问#MoE英文
llamafile v0.10.5

llamafile v0.10.5

Mozilla AI Blog709 字 (约 3 分钟)
85

llamafile v0.10.5支持本地运行6GB的Ternary Bonsai 27B和118B的Laguna-S-2.1模型,优化了量化和同步机制,提升性能与实用性。

入选理由:Ternary Bonsai 27B通过三元量化将模型压缩至6GB,保持90%以上精度

FeaturedArticle#llamafile#模型量化#MoE#本地运行#AI推理英文
&gt; open source AI summer ☀️

&gt; open source AI summer ☀️

Julien Chaumond(@julien_c)87 字 (约 1 分钟)
85

开源AI模型在性能和多样性上取得显著进展,DeepSeek-V4-Flash-0731等模型推动行业创新。

入选理由:DeepSeek-V4-Flash-0731模型参数量达304B,采用MoE架构

FeaturedTweet#AI模型#开源#DeepSeek#MoE架构#基准测试英文
ollama(@ollama) 图标

Model page: https://t.co/DXMhMhBpCk

ollama(@ollama)178 字 (约 1 分钟)
85

Kimi K3模型在Ollama云上发布,具备2.8T MoE架构和1M token上下文窗口,但需付费使用。

入选理由:Kimi K3是2.8T参数的MoE模型,支持原生视觉理解和1M token上下文

FeaturedTweet#AI模型#Ollama#MoE架构#云服务中英混合
MLCommons Releases MLPerf Training v6.0 Results

MLCommons Releases MLPerf Training v6.0 Results

MLCommons1195 字 (约 5 分钟)
85

MLPerf v6.0新增稀疏计算基准,推动AI系统多样性,DeepSeek V3参数达6710亿。

入选理由:DeepSeek V3使用6710亿参数,激活370亿参数/令牌,验证大规模稀疏训练系统。

FeaturedArticle#MLPerf#AI#MoE#基准测试#稀疏计算英文
AI Will(@FinanceYF5) 图标

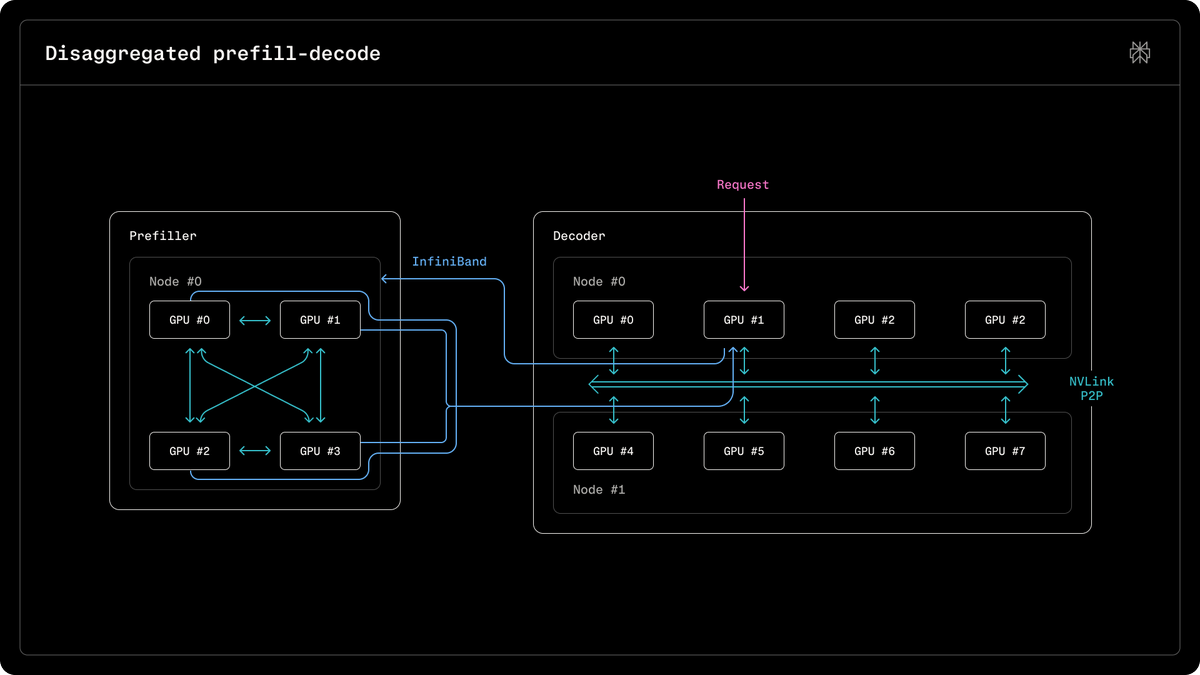
xAI团队通过拆分Prefill和Decode、MoE专家分片及通信计算重叠,实现Grok在10万张GPU上的高效部署。

入选理由:拆分Prefill和Decode是实现大规模GPU部署的关键步骤

FeaturedTweet#Grok#MoE#GPU部署#xAI#SGLang中英混合
Hugging Face Blog 图标

Accelerating Transformers Fine-Tuning with NVIDIA NeMo AutoModel

Hugging Face Blog2379 字 (约 10 分钟)
85

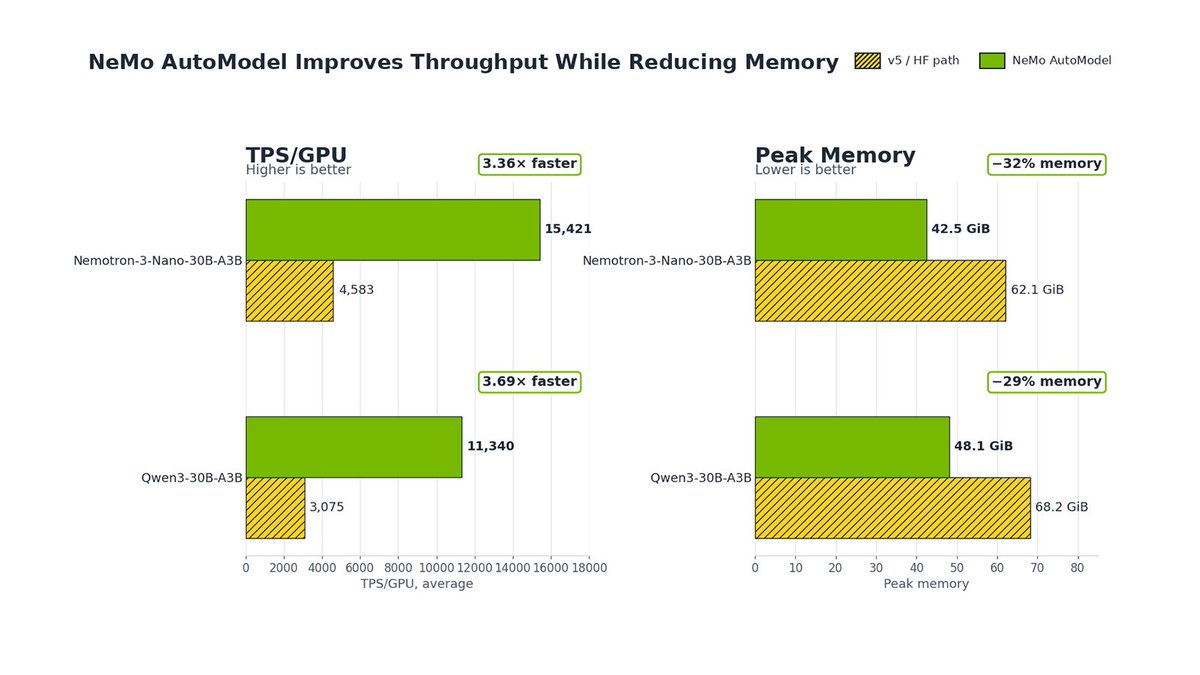
NVIDIA NeMo AutoModel 提升了 MoE 模型的微调效率,训练吞吐量提高 3.4-3.7 倍,GPU 内存减少 29-32%。

入选理由:NVIDIA NeMo AutoModel 使用 Expert Parallelism 和 DeepEP 技术,使 MoE 模型训练吞吐量提升 3.4-3.7 倍。

FeaturedArticle#NVIDIA NeMo#Transformers#MoE#AI 模型优化英文
[AINews] It's Meta-Harness Summer

[AINews] It's Meta-Harness Summer

Latent Space1710 字 (约 7 分钟)
85

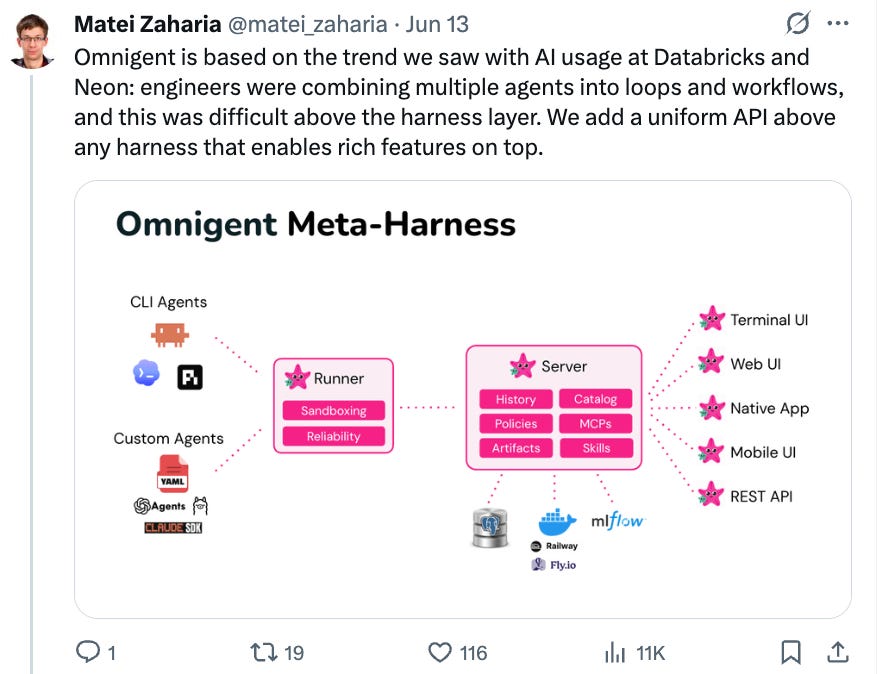
Meta-Harness架构正在成为AI基础设施的核心,Omnigent等开源项目推动标准化、安全、可扩展的系统集成。

入选理由:Omnigent是一个开源、可插拔的Meta-Harness架构,支持标准化集成各类AI代理。

FeaturedArticle#AI#Meta-Harness#OpenAI#NVIDIA#Omnigent英文
Mellum2 Goes Open Source: A Fast Model for AI Workflows

Mellum2 Goes Open Source: A Fast Model for AI Workflows

The JetBrains Blog606 字 (约 3 分钟)
85

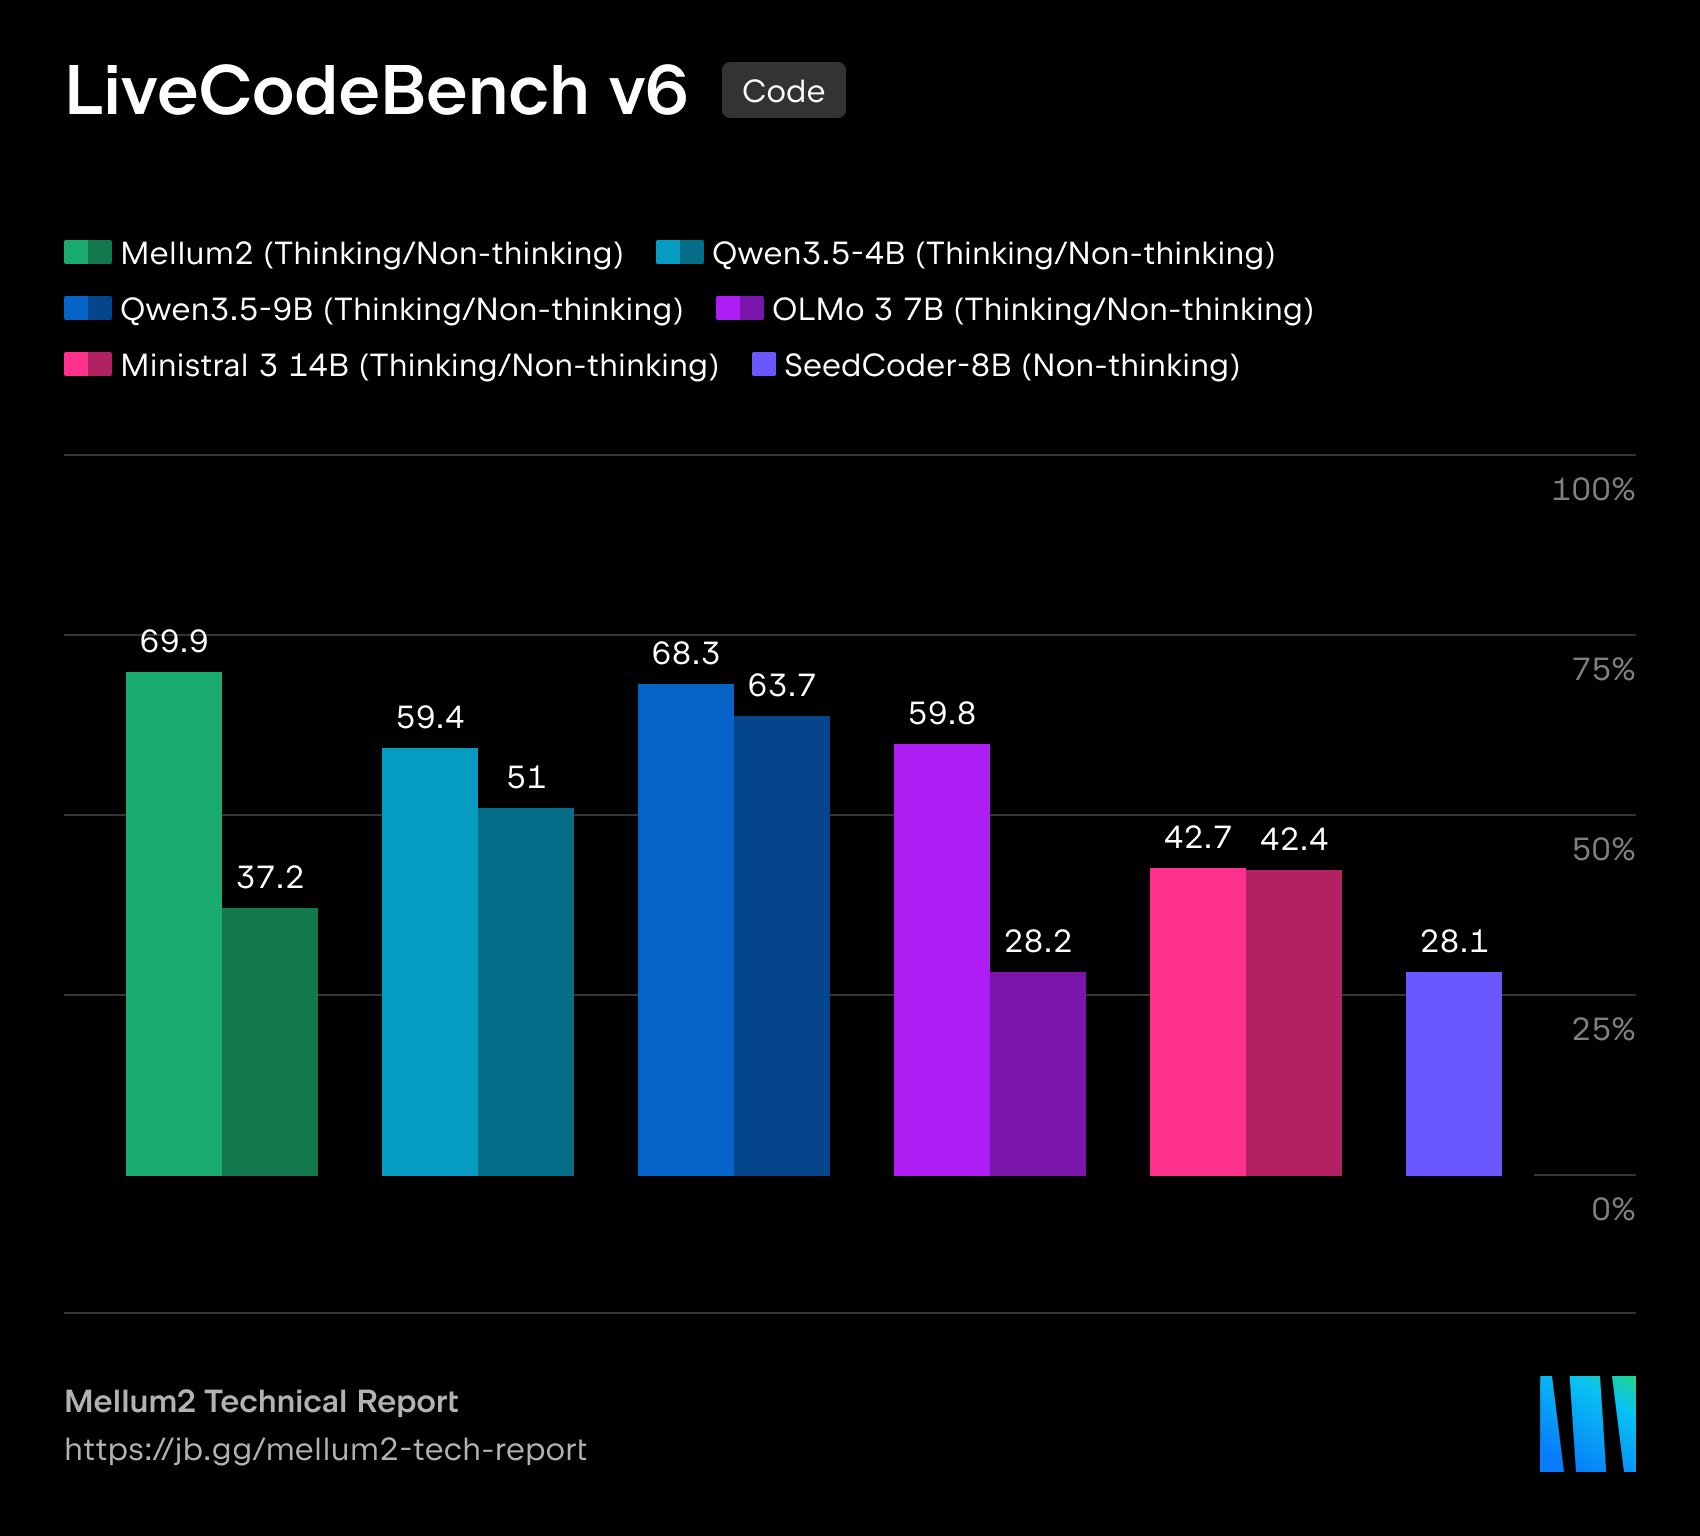
Mellum2 is an open-source 12B parameter AI model from JetBrains, using MoE architecture to activate only 2.5B parameters per token, reducing inference time by over 50% compared to similar-sized models, specifically designed for software engineering environments with applications in routing, RAG pipelines, and private AI deployment.

入选理由:Mellum2采用MoE架构,12B参数模型每token仅激活2.5B参数,推理速度比同类模型快50%,显著降低生产环境延迟和成本

FeaturedArticle#AI#Model#Mellum2#MoE#Software Engineering中文
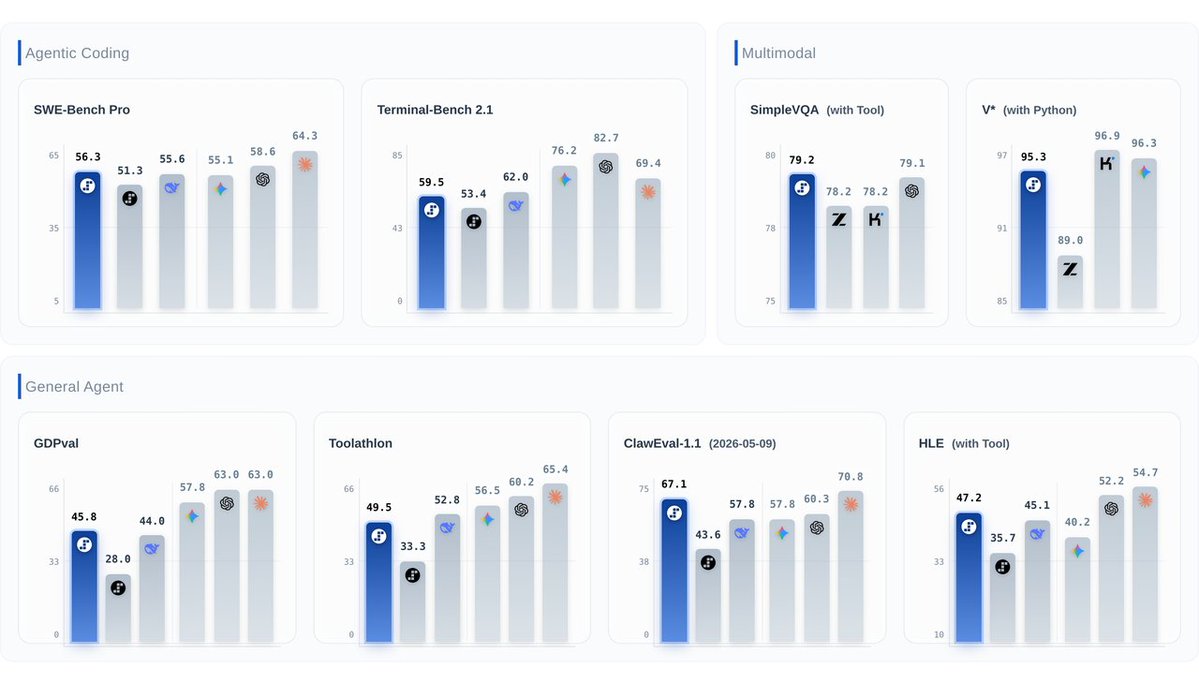
任务成本仅为Claude Opus 4.6 1/9,阶跃刷新Flash模型效率

Step 3.7 Flash by Yujue Star is a new-generation Flash model for production-grade AI Agents, featuring native multimodal understanding, high throughput with low latency, and enhanced web search. It achieves 97% of Claude Opus 4.6's coding performance at only 1/9 the cost per task, ideal for high-frequency, complex real-world workflows.

入选理由:Step 3.7 Flash 采用稀疏 MoE 架构,激活参数仅 11B,最高生成速度达 400 Tokens/s,支持 40 个 Agent 并行运行。

FeaturedArticle#AI Agent#Multimodal#Flash Model#Yujue Star#Production Deployment中文
Step 3.7 Flash from @StepFun_ai is live on OpenRouter.

A multimodal (image/video/text) MoE that act...

Step 3.7 Flash 是一个支持多模态的 MoE 模型,仅激活 11B 参数即可处理 196B 参数规模的任务,适用于编码、代理工作流和结构化输出。

入选理由:Step 3.7 Flash 模型通过激活 11B 参数处理 196B 参数规模任务,显著降低计算成本。

FeaturedTweet#MoE#多模态#AI 模型#OpenRouter中文
MoE环游记:8、强制序列级均衡

MoE Travelogue: 8. Forced Sequence-Level Load Balancing

科学空间4785 字 (约 20 分钟)
85

This article proposes a new sequence-level load balancing method called Moving Quantile Balancing (MQB), which achieves fine-grained balance in MoE models without relying on auxiliary losses.

入选理由:MQB方法基于Quantile Balancing演化而来,适用于序列级负载均衡。

FeaturedArticle#MoE#Load Balancing#Deep Learning#Routing Mechanism#MQB中文
We published new research on how we serve post-trained Qwen3 235B models on NVIDIA GB200 NVL72 Black...

Perplexity published new research on deploying the Qwen3 235B model on NVIDIA GB200 NVL72 Blackwell racks, showing that GB200 outperforms Hopper in high-throughput inference for large MoE models.

入选理由:Qwen3 235B 模型在 NVIDIA GB200 上实现了高效的高吞吐量推理。

FeaturedTweet#NVIDIA#GB200#Qwen3#MoE#High Performance Computing中文
Today we're shipping Nemotron 3 Ultra.

A 550B MoE frontier-intelligence open model built for long-r...

NVIDIA Ships Nemotron 3 Ultra: 550B MoE Open Model

NVIDIA AI(@NVIDIAAI)104 字 (约 1 分钟)
75

NVIDIA released Nemotron 3 Ultra, a 550B MoE open model for long-running agents, offering 5x faster inference and 30% lower costs.

入选理由:Nemotron 3 Ultra采用550B参数MoE架构,是面向前沿智能的开源模型。

FeaturedTweet#NVIDIA#Nemotron#MoE#AI Agent#Open Source英文
7/ 🧩这不是剪枝

ZEDA 更像让 MoE 有了“算力预算意识”。

未来模型不只决定回答什么,还会决定每个 token 值不值得认真思考。

Paper: Post-Trained MoE C...

7/ 🧩This Is Not Pruning

AI Will(@FinanceYF5)244 字 (约 1 分钟)
75

ZEDA is a novel MoE technique that uses self-distillation to dynamically skip experts, improving inference efficiency and giving models compute budget awareness.

入选理由:ZEDA 使用自蒸馏方法使 MoE 模型跳过一半专家,提升推理效率。

FeaturedTweet#MoE#Mixture-of-Experts#AI Efficiency#Self-Distillation#ZEDA中文
Character AI 的前 CEO,transformer 论文的作者之一,MoE 架构的提出者 Noam Shazeer,加入了 OpenAI,进行模型架构研究。

谷歌之前用 27 亿美元收购...

Noam Shazeer 加入 OpenAI,曾参与 transformer 和 MoE 架构研究,谷歌曾以 27 亿美元收购 Character AI 以争取他加入。

入选理由:Noam Shazeer 是 transformer 和 MoE 架构的重要贡献者。

FeaturedTweet#OpenAI#谷歌#Character AI#模型架构中英混合

跨材料问答 · MoE

回答基于:MoE 相关 30 条材料
    0 / 500

    AI may generate inaccurate information. Please verify important content.