DeepSeek's 10 Trillion USD Grand Strategy
DeepSeek reduces KV cache requirements through innovations, driving China's AI hardware ecosystem toward a $10 trillion industry.
入选理由:DeepSeek V4 Pro仅需5.48GB HBM,相比GLM5的60GB和Qwen3-235B-A22B的89GB显著节省显存
模型
别名:General Language Model
中国开源语言模型
已跟踪 19 条高相关材料
最近变化
2026-10-06 · Mistral Large 4拥有1T参数和多模态能力,是欧美最佳开源模型
为什么值得关注
GLM 被反复提及时,通常意味着它正在影响产品路线、开发者工作流或 AI 产业判断。这个页面把分散材料合并成一个可持续更新的观察入口。
DeepSeek 的 10 万亿美元大战略
宝玉的分享 · 9.2 分
DeepSeek通过多项技术创新大幅降低大模型推理中的KV缓存需求,推动中国AI硬件生态发展,目标打造价值10万亿美元的产业巨兽。
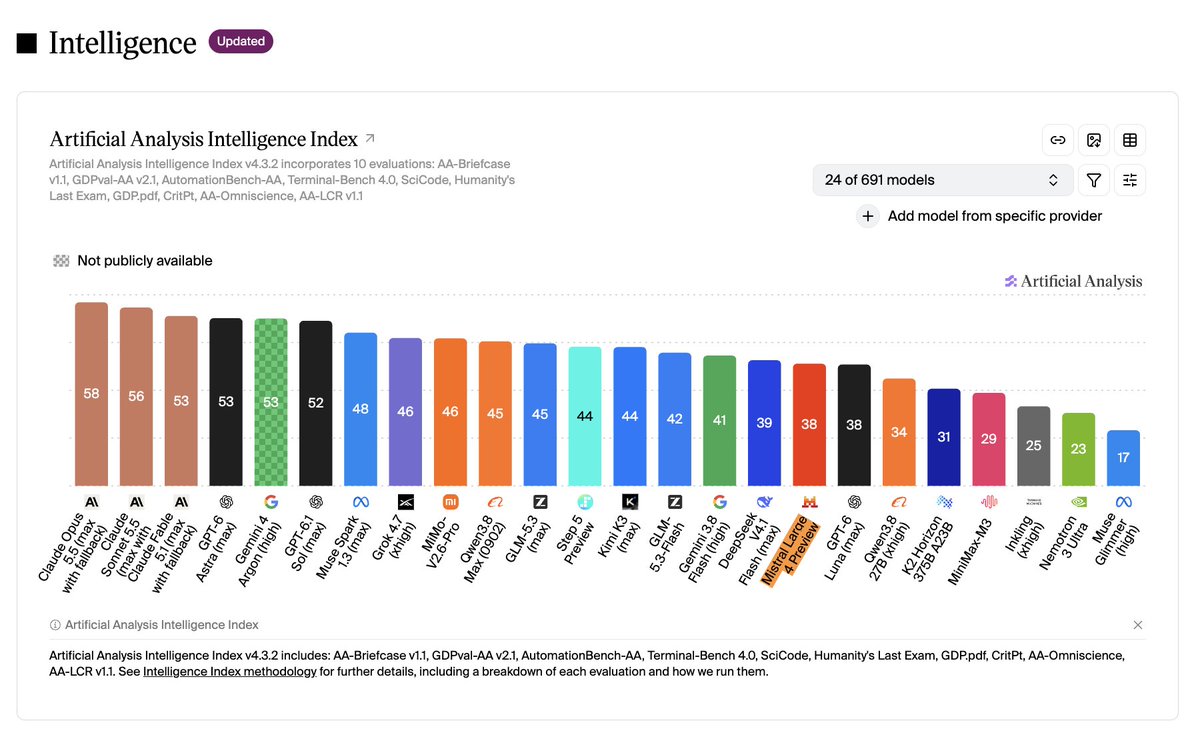
🇪🇺 Respect for @MistralAI for actually getting close now 38th in intelligence and only just behind the Chinese open weight models like DeepSeek, GLM and Kimi and ahead of any US open weight model! It shows Europe can still do stuff if they just all get on the same page 👏
Pieter Levels(@levelsio) · 8.5 分
Mistral AI的Mistral Large 4模型在综合基准测试中排名38,接近中国顶尖开源模型,且在关键领域表现优于美国模型。
Prime Agent + V4 Flash,Claude,Codex: This is OPEN & TECHNICALLY the BEST AGENT HARNESS YET!
AICodeKing · 8.5 分
Prime Agent 是一个开源的递归语言模型编码代理,其在 ARC-AGI 3 基准测试中超越人类专家,支持与 Claude/ChatGPT 集成。
已收录 19 条与 GLM 相关的内容,按评分排序。
DeepSeek reduces KV cache requirements through innovations, driving China's AI hardware ecosystem toward a $10 trillion industry.
入选理由:DeepSeek V4 Pro仅需5.48GB HBM,相比GLM5的60GB和Qwen3-235B-A22B的89GB显著节省显存
Mistral AI的Mistral Large 4模型在综合基准测试中排名38,接近中国顶尖开源模型,且在关键领域表现优于美国模型。
入选理由:Mistral Large 4拥有1T参数和多模态能力,是欧美最佳开源模型
Prime Agent 是一个开源的递归语言模型编码代理,其在 ARC-AGI 3 基准测试中超越人类专家,支持与 Claude/ChatGPT 集成。
入选理由:Prime Agent 使用 RLM 架构,通过 IPython 内核减少 token 消耗,提升效率。
Gemma 4 在不同硬件类别中表现最佳,专注于本地设备智能而非服务器端前沿智能。
入选理由:Gemma 4 在不同硬件类别中表现最佳。
Claude Code is Anthropic's terminal-based AI programming assistant that supports CLI operations, multi-model configuration (e.g., Zhipu GLM), Hooks, and engineering workflows. This article provides a comprehensive command reference, top recommended commands, pitfall logs, and best practices to help developers go from beginner to expert and significantly boost productivity.
入选理由:使用 `claude -r` 可恢复上次会话,支持按名称或 ID 恢复,适合连续任务处理。
Wuwen Xinqiong, a neutral AI infrastructure provider, supports the token explosion of domestic large models, with daily token calls up 20x in two years and nearly $2.2B in funding, becoming a core hub in the AGI era.
入选理由:Agent时代推动单次任务Token消耗飙升至十万甚至百万级,倒逼AI底层架构升级。
通过集成AI模型和中文优化,Obsidian可升级为强大的Epub阅读器,支持本地模型调用和多模型配置。
入选理由:支持Codex、Claude、Grok CLI及DeepSeek等7个主流AI模型
中国AI追赶美国将引发七个深远影响,包括开源AI企业信任度提升、美国AI出口管制效果减弱等。
入选理由:中国开源模型如Kimi K3可能提升企业对开源AI的信任度
Kaku V0.11.0 introduces hidden reasoning support for DeepSeek/GLM/Kimi/Fireworks, smarter session restore, and enhanced terminal setup experience with improved interface and performance stability.
入选理由:新增对DeepSeek、GLM、Kimi、Fireworks等AI模型的隐藏推理支持,增强AI编码能力
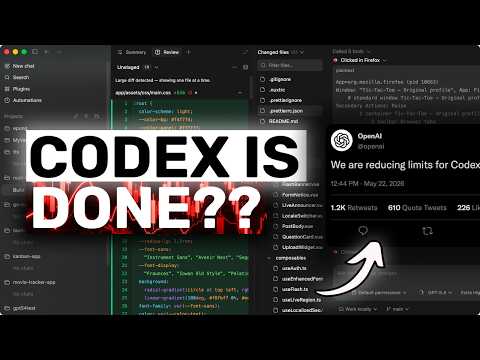
OpenAI has halved Codex usage limits, signaling unsustainable business practices; enterprise users remain largely unaffected while individual developers must seek alternatives.
入选理由:Codex API调用频率限制已减少一半,用户反馈证实该变化已在持续12小时以上。
欧洲新推出的主权模型Kolibri基于GLM和Qwen生成的数据进行微调,参数量达78B。
入选理由:Kolibri模型拥有78B参数和1M上下文长度,采用Apache 2.0许可证
欧洲主权模型依赖GLM和Qwen数据,Aleph Alpha发布78B参数开源模型Kolibri,支持Apache 2.0授权。
入选理由:欧洲主权模型使用GLM和Qwen生成的数据进行微调
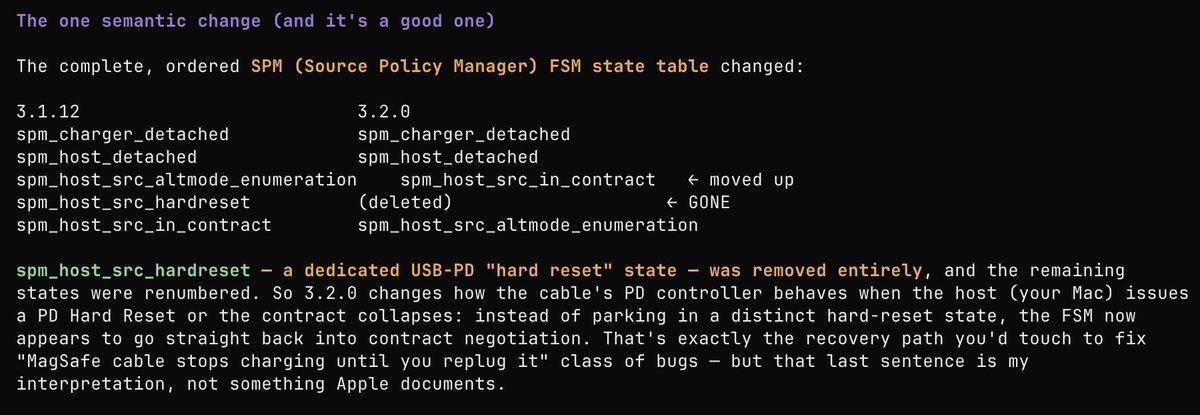
文章简要提及GLM模型用于固件差异分析及Apple电缆固件更新,但缺乏技术深度与实用价值。
入选理由:GLM模型被用于分析固件变更差异,但未说明具体实现方式
Bolt平台重置Forge令牌,新增GLM、DeepSeek和Kimi模型支持。
入选理由:Bolt用户需重新获取Forge tokens以使用新模型
Gemini 3.5 Flash is now available on OpenCode with claims of high speed and 1M context, priced similarly to GLM, Kimi, and DeepSeek Pro—but lacks benchmarks, API specs, or latency data, making it a low-information product announcement.
入选理由:Gemini 3.5 Flash 在 OpenCode 平台上线,支持 1M 上下文长度。
Bolt Forge现已开放,提供GLM、DeepSeek、Kimi等模型访问,Pro计划用户可立即使用,Lite计划需付费9美元/月。
入选理由:Bolt Forge Pro用户可立即访问GLM/DeepSeek/Kimi模型
该推文讨论社交媒体上的模型竞争话题,但缺乏技术深度和实用价值,不构成有效技术内容。
入选理由:该推文讨论社交媒体上的模型竞争话题,但缺乏技术深度和实用价值,不构成有效技术内容
文章预测大型语言模型将在年底或明年年初取得重大突破,但内容缺乏具体技术细节和论证。
入选理由:预测年底或明年年初出现重大突破
文章内容为社交媒体帖子,未提供技术深度或实用信息。
入选理由:文章未提供技术细节或实用信息。