T
traeai
Sign in

公司

Artificial Analysis

别名:ArtificialAnlys

提供AI模型性能指数的分析机构

已跟踪 30 条高相关材料

TraeAI 观察

相关材料

已收录 30 条与 Artificial Analysis 相关的内容,按评分排序。

I remember when people were saying "It's useless to open-source big models because nobody will be ab...

Cerebras is now running the trillion-parameter Kimi K2.6 model in enterprise trials at ~1,000 tokens/s, shattering the old belief that open-source large models are impractical due to hardware limitations.

入选理由:Cerebras 在企业测试中以约1000 tokens/s的速度运行Kimi K2.6(千亿参数模型),创当前最快推理记录。

FeaturedTweet#Cerebras#Kimi K2.6#Open-Source LLM#Inference Performance#AI Hardware英文
Gemini 3.5 Flash: more expensive, but Google plan to use it for everything

Gemini 3.5 Flash: more expensive, but Google plan to use it for everything

Simon Willison's Weblog615 字 (约 3 分钟)
87

Google released Gemini 3.5 Flash at six times the price of its predecessor, yet deployed it across Search, AI Assistant, and enterprise tools—revealing a strategic shift toward internal model saturation over API monetization.

入选理由:Gemini 3.5 Flash输入价格为$1.50/百万token,输出为$9/百万token,是3.1 Flash-Lite的6倍。

FeaturedArticle#Gemini#Google#AI Model#API Pricing#Large Model Deployment英文
Hugging Face Blog 图标

Hugging Face 推出 Open TTS Leaderboard,通过客观指标解决 TTS 模型评估碎片化问题,评估时间从数周缩短至数小时。

入选理由:Open TTS Leaderboard 使用 WER/CER、RTFx、TTFA、SIM 等指标,评估时间从数周缩短至数小时

FeaturedArticle#TTS#评估#Hugging Face#开源英文
AI HOT 精选 图标

GPT-6.1 Sol 每任务成本较 GPT-6 Sol 降低 30%,主要通过价格调整和 token 使用优化实现。

入选理由:GPT-6.1 Sol 每任务成本 $0.72,较 GPT-6 Sol 降低 30%

FeaturedArticle#AI模型#成本分析#OpenAI#技术选型中英混合
Get Started with Kimi K3 on CoreWeave Dedicated Inference

Get Started with Kimi K3 on CoreWeave Dedicated Inference

CoreWeave1076 字 (约 5 分钟)
85

CoreWeave支持部署2.8万亿参数的Kimi K3模型,提供租户隔离网关和GPU优化服务,适合需要大规模推理的用户。

入选理由:Kimi K3是2.8万亿参数的开源模型,支持百万级上下文窗口和视觉理解。

FeaturedArticle#Kimi K3#CoreWeave#模型部署#Dedicated Inference#AI推理英文
Qwen-Audio-3.0系列语音模型正式上线千问AI平台

Qwen-Audio-3.0系列语音模型正式上线千问AI平台

阿里云开发者535 字 (约 3 分钟)
85

阿里云推出Qwen-Audio-3.0语音模型系列,获全球三大赛道冠军,支持多语种与实时交互,开发者可订阅Token Plan使用。

入选理由:Qwen-Audio-3.0-ASR在Artificial Analysis评测中获语音识别全球第一

FeaturedArticle#语音模型#阿里云#AI平台#ASR#TTS中文
Introducing our Artifacts Hub and Adoption Dashboard

Introducing our Artifacts Hub and Adoption Dashboard

Interconnects AI612 字 (约 3 分钟)
85

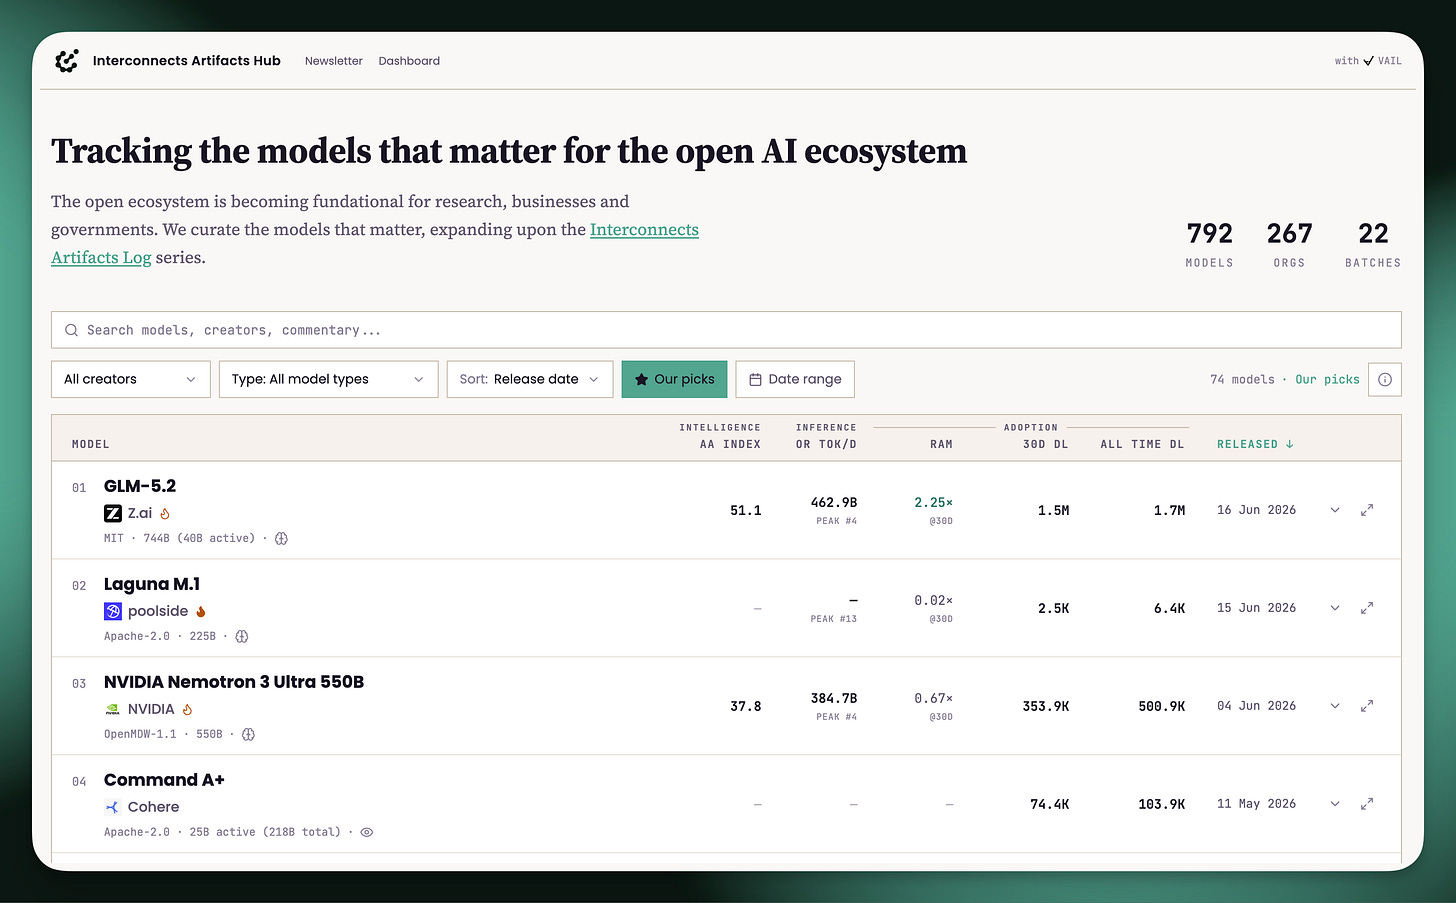
Interconnects AI 推出 Artifacts Hub 和 Adoption Dashboard,提供开源模型生态的深度分析与实时数据追踪。

入选理由:Artifacts Hub 覆盖 792 个近两年发布的模型,整合 Hugging Face 与 Open Router 数据。

FeaturedArticle#Artifacts Hub#Adoption Dashboard#开源模型#数据可视化英文
[AINews] Claude Opus 5: Fable-level performance at Opus price (half Fable)

[AINews] Claude Opus 5: Fable-level performance at Opus price (half Fable)

Latent Space2436 字 (约 10 分钟)
85

Claude Opus 5在性能接近Fable 5的同时将成本降低20%,独立测试显示其在知识工作基准测试中领先150 Elo。

入选理由:Claude Opus 5在AA-Briefcase基准测试中比Fable 5高出150 Elo

FeaturedArticle#AI模型#Anthropic#基准测试#成本效益英文
GLM-5.2 is probably the most powerful text-only open weights LLM

GLM-5.2 is probably the most powerful text-only open weights LLM

Simon Willison's Weblog730 字 (约 3 分钟)
85

GLM-5.2 是目前参数量最大的开源文本模型,拥有 753B 参数和 100 万 token 上下文窗口,性能在多个基准测试中领先。

入选理由:GLM-5.2 拥有 753B 参数和 100 万 token 上下文窗口,是目前最大的开源文本模型。

FeaturedArticle#GLM-5.2#开源模型#AI#自然语言处理英文
Hugging Face Blog 图标

Introducing North Mini Code: Cohere’s First Model For Developers

Hugging Face Blog2871 字 (约 12 分钟)
85

Cohere 发布 North Mini Code,一个 30B 参数的 Mixture-of-Experts 模型,专为开发者设计,在多个代码生成基准测试中表现优异。

入选理由:North Mini Code 是 Cohere 首个专为开发者设计的模型,参数量为 30B,其中 3B 为活跃参数。

FeaturedArticle#Cohere#模型#代码生成#Mixture-of-Experts#AI英文
Artificial Analysis放榜:千问3.7问鼎国产模型冠军,全球前五

Alibaba Cloud's Qwen3.7-Max scores 56.6 to rank 5th globally and 1st domestically in Artificial Analysis benchmark, soon available via Alibaba Cloud's BaiLian API.

入选理由:Qwen3.7-Max得分56.6分,超越国产所有模型,逼近GPT-5.4、Gemini3.1 Pro等国际顶尖模型

FeaturedArticle#Qwen3.7-Max#Artificial Analysis#Model Benchmarking#Alibaba Cloud中文
StepAudio 2.5 TTS 在语音竞技场盲测中跻身全球前三

StepAudio 2.5 TTS Ranks Top 3 Globally in Blind Test on Speech Arena

AI HOT 精选121 字 (约 1 分钟)
85

StepAudio 2.5 TTS ranked #3 globally on the Artificial Analysis Speech Arena leaderboard in a blind test, behind only Inworld’s Realtime TTS 1.5 Max and Google’s Gemini 3.1 Flash TTS.

入选理由:StepAudio 2.5 TTS 在盲测中排名全球第3,仅落后于 Inworld 和 Google 的模型。

FeaturedArticle#TTS#Speech Synthesis#AI Model#StepFun中文
WAIT… Astra crushes Fable 5.1 on every benchmark but makes 0 progress on the AA Intelligence score?

> same 61 as Sol and Grok 4.6
> 51 on Agentic Index vs 59 for Grok
> and then it saturates ARC-AGI-3?

this is the biggest discrepancy I’ve seen a model’s evals.

Astra模型在多数基准测试中表现优异,但AA Intelligence得分未提升,且成本较高。

入选理由:Astra在Fable 5.1基准中得分与Grok 4.6相同,但AA Intelligence得分未提升。

FeaturedTweet#AI模型#基准测试#成本分析#模型对比中英混合
AI Engineer Melbourne 2026 Keynote Livestream | Day 1

AI Engineer Melbourne 2026 Keynote Livestream | Day 1

AI Engineer20378 字 (约 82 分钟)
75

AI is evolving from mere models to a combination of services, data, and products, with a surge in code generation and cost considerations impacting product strategies.

入选理由:AI不仅限于模型,还包括服务、数据和品牌,这对AI工程师有利。

FeaturedVideo#AI#Tech Trends#Code Generation英文
Meta just released Muse Spark Open, calling it "the most capable US open-weight model to date."

Met...

Meta发布Muse Spark Open称其为最强美国开源模型,但中国GLM 5.3和Kimi K3仍领先,Nvidia同步推出更小更快的Nemotron 3.5 Super VL。

入选理由:Meta Muse Spark Open在Artificial Analysis指数中排名第39,落后于中国GLM 5.3(45)和Kimi K3(44)。

FeaturedTweet#Meta#Nvidia#开源模型#AI竞争#中美技术对比英文
See the full leaderboard: https://t.co/yPCC4KAOZl

See the full leaderboard: https://t.co/yPCC4KAOZl

HeyGen(@HeyGen_Official)173 字 (约 1 分钟)
60

HeyGen语音模型在Artificial Analysis TTS排行榜登顶,但缺乏技术细节和原理说明。

入选理由:HeyGen Voice模型在盲测中击败所有主流TTS模型

FeaturedTweet#AI语音#TTS模型#HeyGen#排行榜中英混合
Interesting pattern.

Interesting pattern.

elvis(@omarsar0)59 字 (约 1 分钟)
60

文章展示了一个关于开源模型与闭源模型性能差距的时间线分析,但信息密度较低。

入选理由:开源模型在性能上存在滞后现象。

FeaturedTweet#AI#模型#开源英文

跨材料问答 · Artificial Analysis

回答基于:Artificial Analysis 相关 30 条材料
    0 / 500

    AI may generate inaccurate information. Please verify important content.