T
traeai
Sign in

traeai topic radar

向量数据库、Embedding 与语义搜索实践

追踪 Qdrant、Milvus、pgvector、Embedding、稀疏检索、重排与语义搜索系统设计。

What searchers are trying to solve

想理解向量数据库怎么选型、怎么做语义搜索,以及 RAG 检索链路如何优化。

Why this is worth tracking

很多 AI 应用的效果瓶颈不在模型,而在检索和上下文组织。

向量数据库vector databaseEmbedding语义搜索QdrantMilvuspgvectorrerank

长尾组合

这个专题可以沿着工具、实践、对比等搜索意图持续扩展,不靠空壳换词,而是用真实材料更新。

向量数据库 工具向量数据库 实践向量数据库 对比vector database 工具vector database 实践vector database 对比Embedding 工具Embedding 实践

可自动化内容模块

精选材料

持续抓取与 向量检索 相关的高分文章、播客、视频和推文。

趋势判断

把最近变化、反复出现的观点和争议点整理成稳定摘要。

实体关联

自动连接相关公司、模型、产品、人物和概念,形成可继续深挖的入口。

Featured content

Filtered by relevance, score, and recency.

Search more
Multi-Vector Retrieval Strategy: Separability Determines nDCG@10 Success

Multi-Vector Retrieval Strategy: Separability Determines nDCG@10 Success

Milvus(@milvusio)340 字 (约 2 分钟)
92

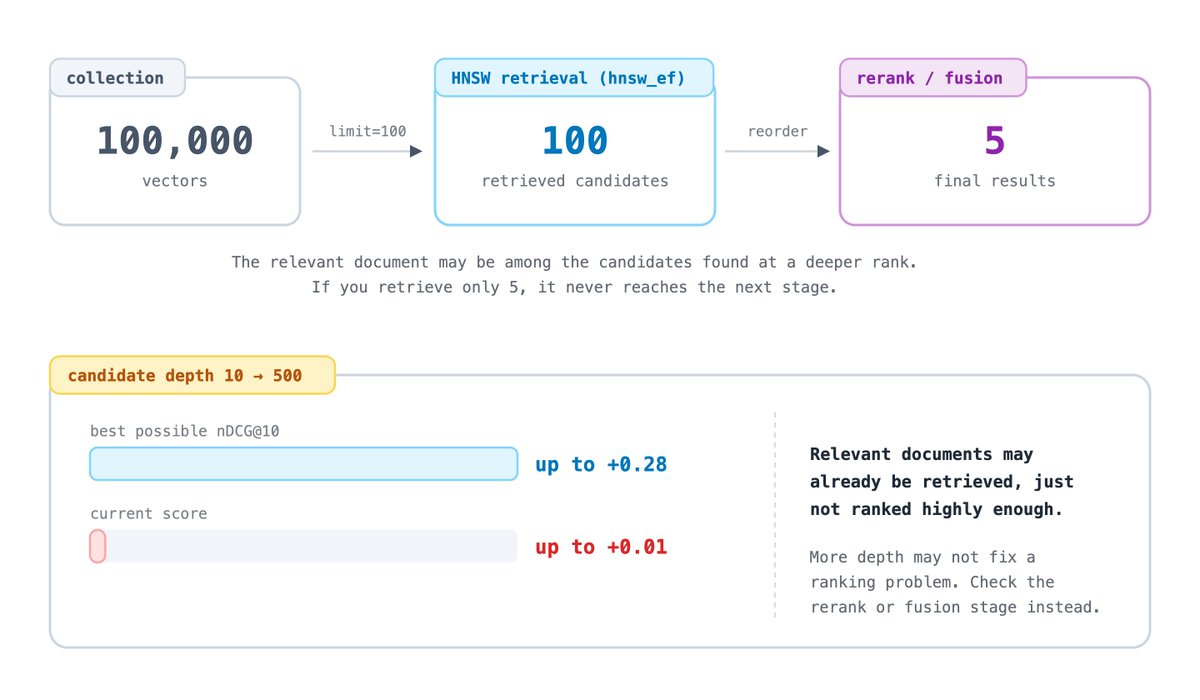
Choosing the wrong approximate strategy in multi-vector retrieval causes a 6x drop in nDCG@10, exceeding model upgrade gains. Measure embedding space separability via MaxSim std dev: use TokenANN/MUVERA for high spread, LEMUR for low spread.

入选理由:Wrong approximate strategy drops nDCG@10 from 0.701 to 0.109 on the same model/d

FeaturedTweet#Multi-vector Retrieval#ColBERT#Milvus#Approximate Search#RAG英文
Meta's Smart Glasses Companion App Ships Complete but Dormant Face Recognition Pipeline

Meta’s Stella app v273 contains a fully functional but inactive on-device face recognition pipeline with three models, local vector DB, and notification components—technically ready but not enabled for regular users.

入选理由:Stella v273 bundles SCRFD, KPSAligner, and SFace models (~100MB total), generati

FeaturedArticle#Face Recognition#On-Device AI#Meta#Privacy Security#ExecuTorch英文
Most people use vector databases for chatbots and RAG pipelines. 𝗦𝗲𝗻𝗾𝗶 𝗔𝗜 𝘂𝘀𝗲𝘀 ...

Senqi AI 使用 Milvus 向物理机器人注入长期语义记忆能力,解决真实世界任务中环境动态、任务无界、指令模糊和错误高成本等核心挑战。

入选理由:物理机器人Agent需实时重规划,因环境持续变化且任务无明确终点

FeaturedTweet#Milvus#RAG#机器人#向量数据库#AI Agent中文
Context Defocus is Silently Killing Your Claude Code Agent — and These 7 Tools Fix It

Context defocus significantly impacts the Claude Code agent, with seven open-source tools effectively addressing this issue, reducing token consumption by 60-90%.

入选理由:Using RTK to compress terminal output can reduce token consumption by 60-90%.

FeaturedTweet#AI#Claude Code#Context Defocus英文
Most in-car media systems still expect you to search with keywords. But when you’re driving, you don’t think in keywords — you think in moods, vibes, and intent.

Current in-car media systems still rely on keyword-based search, but drivers naturally express needs through emotions, vibes, and intent—not terms. Sarvesh Talele’s project, built with Qdrant Edge, delivers a fully local, AI-powered media discovery system supporting voice, text, and mood-based semantic queries—no cloud needed, ensuring privacy-first, real-time experience.

入选理由:The system uses Whisper for local voice transcription, vector embeddings for sem

FeaturedTweet#Qdrant#Vector Search#Edge AI#In-Car System#Privacy英文
Embeddings Aren’t Magic: The Predictable Failure Modes of RAG Retrieval

Embeddings Aren’t Magic: The Predictable Failure Modes of RAG Retrieval

Towards Data Science9526 字 (约 39 分钟)
87

RAG systems rely on embeddings that fail predictably: when queries use different terms than docs (e.g., ‘overtime’ vs ‘non-employee labor’), contain negations, or depend on exact IDs/codes, retrieval fails. The article argues enterprise reliability comes from upstream filtering (expert keywords, doc structure), not rerankers atop weak retrieval.

入选理由:Embeddings excel at paraphrase/synonym handling (e.g., ‘cancel’ → ‘termination p

FeaturedArticle#RAG#Embedding#Retrieval#Enterprise AI#Document Intelligence英文
Rerankers Aren’t Magic Either: When the Cross-Encoder Layer Is Worth the Cost

Rerankers Aren’t Magic Either: When the Cross-Encoder Layer Is Worth the Cost

Towards Data Science4625 字 (约 19 分钟)
87

The article argues that rerankers—often treated as a ‘magic layer’ in RAG systems—still fail on core semantic challenges like negation, logical complementation, and domain-specific terms, while adding significant latency; experiments show that in some cases, pure embedding retrieval (e.g., text-embedding-3-large) outperforms or matches the ‘embedding + reranker’ combo.

入选理由:bge-reranker-base and similar cross-encoders cannot resolve negation, logical co

FeaturedArticle#RAG#Cross-Encoder#Embedding#Retrieval#Enterprise AI英文
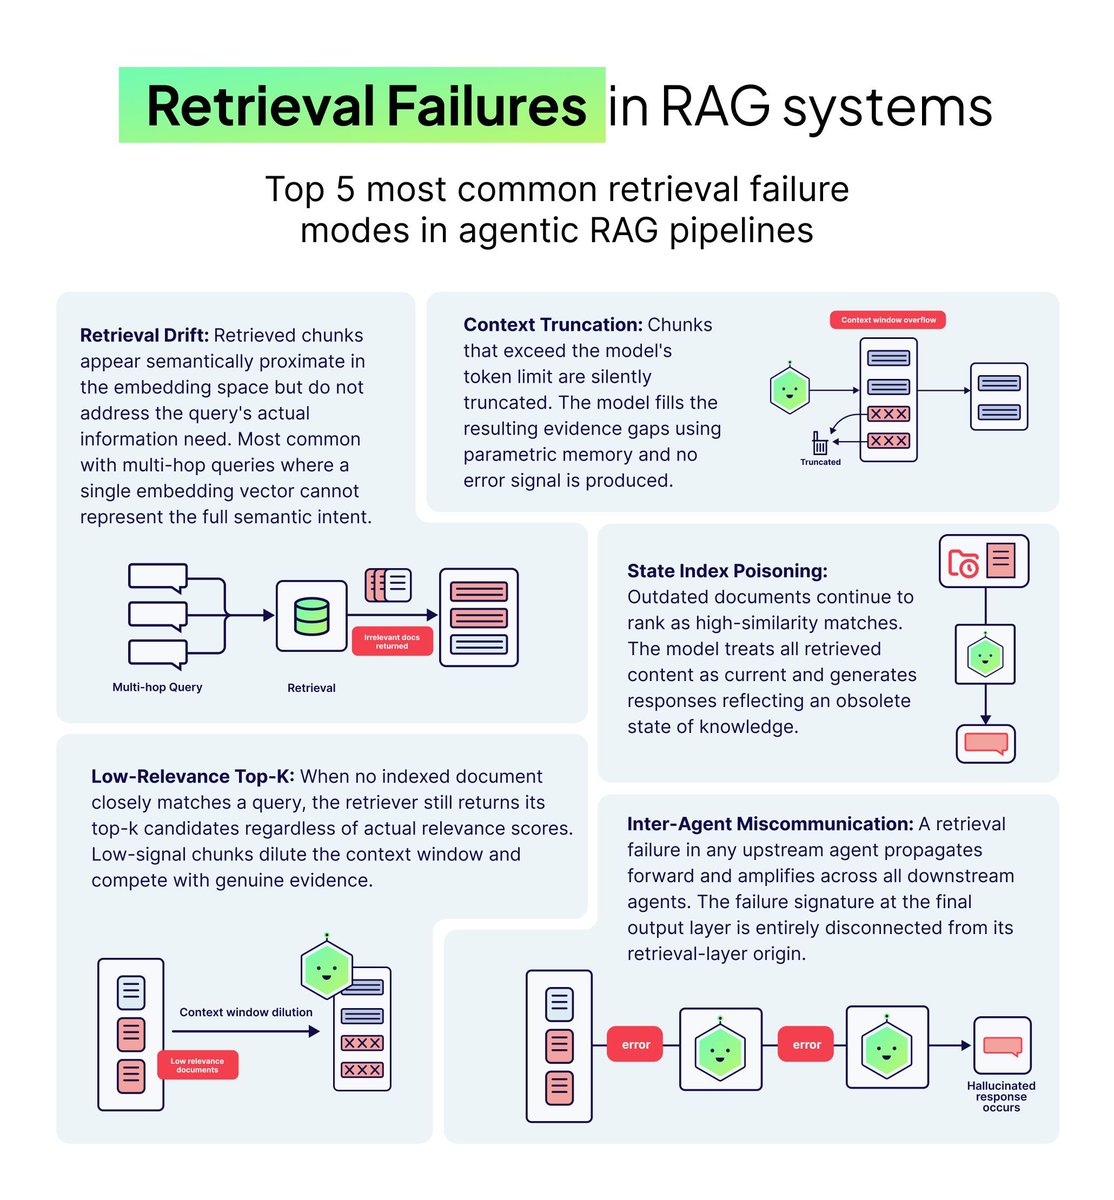
Your RAG System Produces 'Higher-Fluency Hallucinations'

Your RAG System Produces 'Higher-Fluency Hallucinations'

Weaviate • vector database(@weaviate_io)245 字 (约 1 分钟)
87

Research reveals poor retrieval quality is the primary cause of high-fluency hallucinations in RAG systems—more convincing, confident, and wrong—while scaling models fails to fix the root issue.

入选理由:Poor retrieval quality is the strongest predictor of degraded RAG output; larger

FeaturedTweet#RAG#Vector Database#Weaviate#LLM#Hallucination Detection中英混合
𝗛𝗲𝗿𝗲'𝘀 𝗮 𝗰𝗼𝘀𝘁 𝘁𝗿𝗶𝗰𝗸 𝗺𝗼𝘀𝘁 𝘁𝗲𝗮𝗺𝘀 𝗺𝗶𝘀𝘀 𝘄𝗶𝘁𝗵 𝘁𝗵𝗲𝗶𝗿 𝘃𝗲𝗰𝘁𝗼𝗿 ...

Milvus 提出通过 compaction(段合并与物理删除)和 TTL(自动过期)两项内置机制,可显著降低向量数据库存储成本,尤其适用于会话数据、时效性 RAG 等有生命周期的数据场景。

入选理由:向量数据库中逻辑删除不释放磁盘空间,导致存储膨胀达2–5倍

FeaturedTweet#Milvus#向量数据库#存储优化#TTL#compaction中文
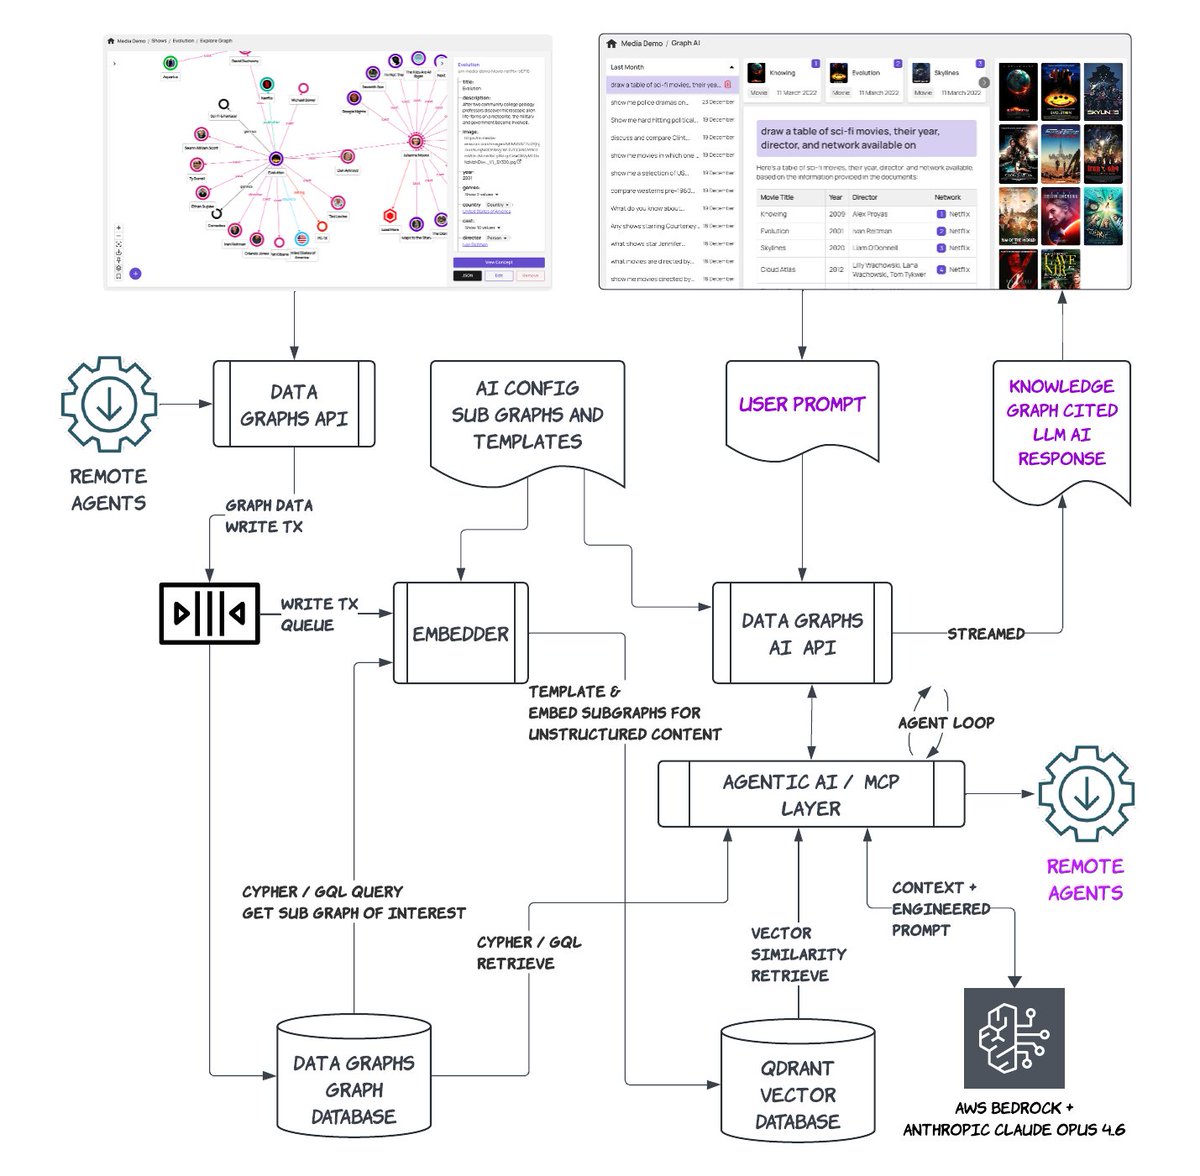
Most "Graph RAG" implementations are vector retrieval with extra steps.

@datagraphs built something...

Qdrant 指出多数“图RAG”实为套壳向量检索,而 @datagraphs 构建了真正融合图数据库与向量搜索的协同架构:通过 schema-first agent 调度并行图查与语义检索,实现可验证、低延迟、全栈可控的知识问答。

入选理由:图与向量非互斥,而是互补:图擅精确逻辑查询(否定/时间/计算),向量擅语义相似匹配

FeaturedTweet#RAG#Graph Database#Vector Search#Qdrant#Knowledge Graph中文
Power video semantic search with Amazon Nova Multimodal Embeddings

Power video semantic search with Amazon Nova Multimodal Embeddings

AWS Machine Learning Blog3566 字 (约 15 分钟)
87

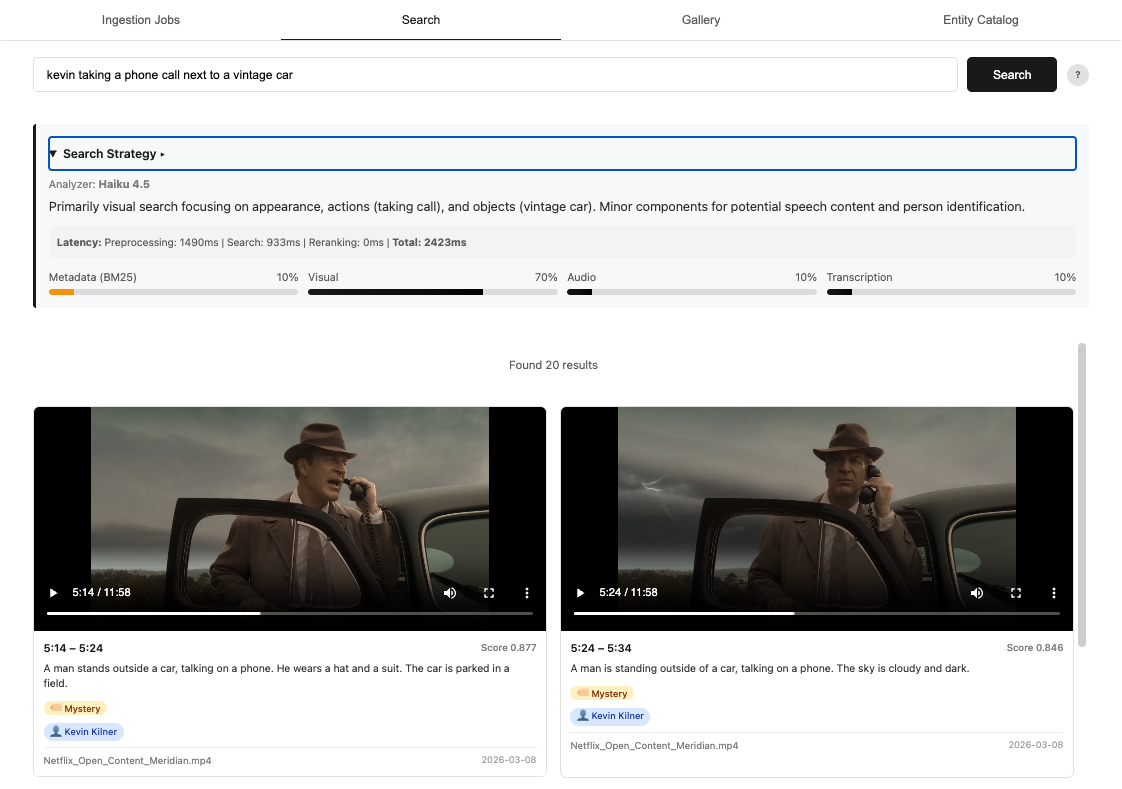
AWS 推出基于 Amazon Nova 多模态嵌入的视频语义搜索方案,可联合处理音视频、文本等多源信号,提升检索准确性与效率。

入选理由:传统视频搜索依赖文本转录,易丢失时空和音频信息

FeaturedArticle#Amazon Nova#多模态嵌入#视频语义搜索#Amazon Bedrock#AWS英文
Modern Sparse Neural Retrieval: From Theory to Practice

Modern Sparse Neural Retrieval: From Theory to Practice

Qdrant5415 字 (约 22 分钟)
87

文章系统解析现代稀疏神经检索模型(如SPLADE++),对比关键词与稠密检索优劣,并展示其在Qdrant中的实践应用。

入选理由:稀疏神经检索结合BM25的可解释性与语义理解能力,优于传统关键词匹配

FeaturedArticle#稀疏神经检索#SPLADE#Qdrant#信息检索#向量搜索英文
Training and Finetuning Multimodal Embedding & Reranker Models with Sentence Transformers

文章详解如何使用 Sentence Transformers 微调多模态嵌入与重排序模型,并以视觉文档检索任务为例展示显著性能提升。

入选理由:微调多模态嵌入模型可显著提升特定任务(如视觉文档检索)的检索效果

FeaturedArticle#Sentence Transformers#多模态学习#模型微调#嵌入模型#Hugging Face英文
𝟭𝟬𝟬𝗠+ 𝘁𝗿𝗮𝗰𝗸𝘀. 𝗕𝗶𝗹𝗹𝗶𝗼𝗻𝘀 𝗼𝗳 𝘃𝗲𝗰𝘁𝗼𝗿𝘀. ~𝟭𝟬 𝗺𝘀 𝗣𝟵𝟵 𝗱𝗮𝘁𝗮𝗯𝗮𝘀𝗲 ...

Milvus向量数据库支撑全球最大音乐平台实现百亿级音轨检索,10ms级P99延迟,覆盖歌曲识别、版权匹配等场景。

入选理由:Milvus处理超百亿向量数据,支持每秒数百次搜索请求

FeaturedTweet#向量数据库#Milvus#音乐推荐#大规模检索英文
Weaviate • vector database(@weaviate_io) 图标

AI memory gets worse when you treat it as an ever-growing pile of chat history. Every turn adds mor...

Weaviate • vector database(@weaviate_io)276 字 (约 2 分钟)
85

将AI记忆视为不断增长的聊天历史会导致性能下降,Weaviate的Engram通过异步处理优化记忆管理。

入选理由:Engram通过异步处理提取、对比、解决矛盾的四步流程优化记忆管理

FeaturedTweet#Weaviate#AI记忆管理#Engram#异步处理#数据管理英文
Machine Learning Mastery 图标

Multilingual Text Classification with Scikit-LLM and Multilingual Embeddings

Machine Learning Mastery1842 字 (约 8 分钟)
85

使用Scikit-LLM和多语言嵌入可构建无需单独训练每种语言模型的多语言文本分类流水线。

入选理由:BGE-M3模型支持多语言嵌入生成,可替代付费API实现本地化部署

FeaturedArticle#Scikit-LLM#多语言分类#BGE-M3#嵌入模型英文
Machine Learning Mastery 图标

Build And Understand a Vector Database From Scratch in 10 Easy Steps

Machine Learning Mastery3609 字 (约 15 分钟)
85

本文通过10个步骤用Python和NumPy从零构建向量数据库,详解向量编码、相似性搜索和近似索引原理。

入选理由:使用sentence-transformers库将文档编码为固定长度向量

FeaturedArticle#向量数据库#Python#NumPy#机器学习英文
Qdrant 图标

Hyperbolic Embeddings in Qdrant

Qdrant2035 字 (约 9 分钟)
85

双曲嵌入在处理层次结构数据时比传统欧几里得嵌入更高效,且在WordNet案例中表现优异。

入选理由:双曲嵌入在WordNet案例中,5维精度0.823远超200维欧几里得嵌入的0.168

FeaturedArticle#双曲嵌入#Qdrant#欧几里得空间#层次结构数据英文
Building an Internal Developer Platform with Artificial Intelligence

AI代理通过语义搜索整合Git/Slack/Jira等数据源,结合OpenTelemetry监控实现安全可控的内部开发者平台。

入选理由:AI代理整合Git、Slack、Jira等12类数据源实现上下文感知

FeaturedArticle#Internal Developer Platform#AI Agents#OpenTelemetry#Semantic Search英文
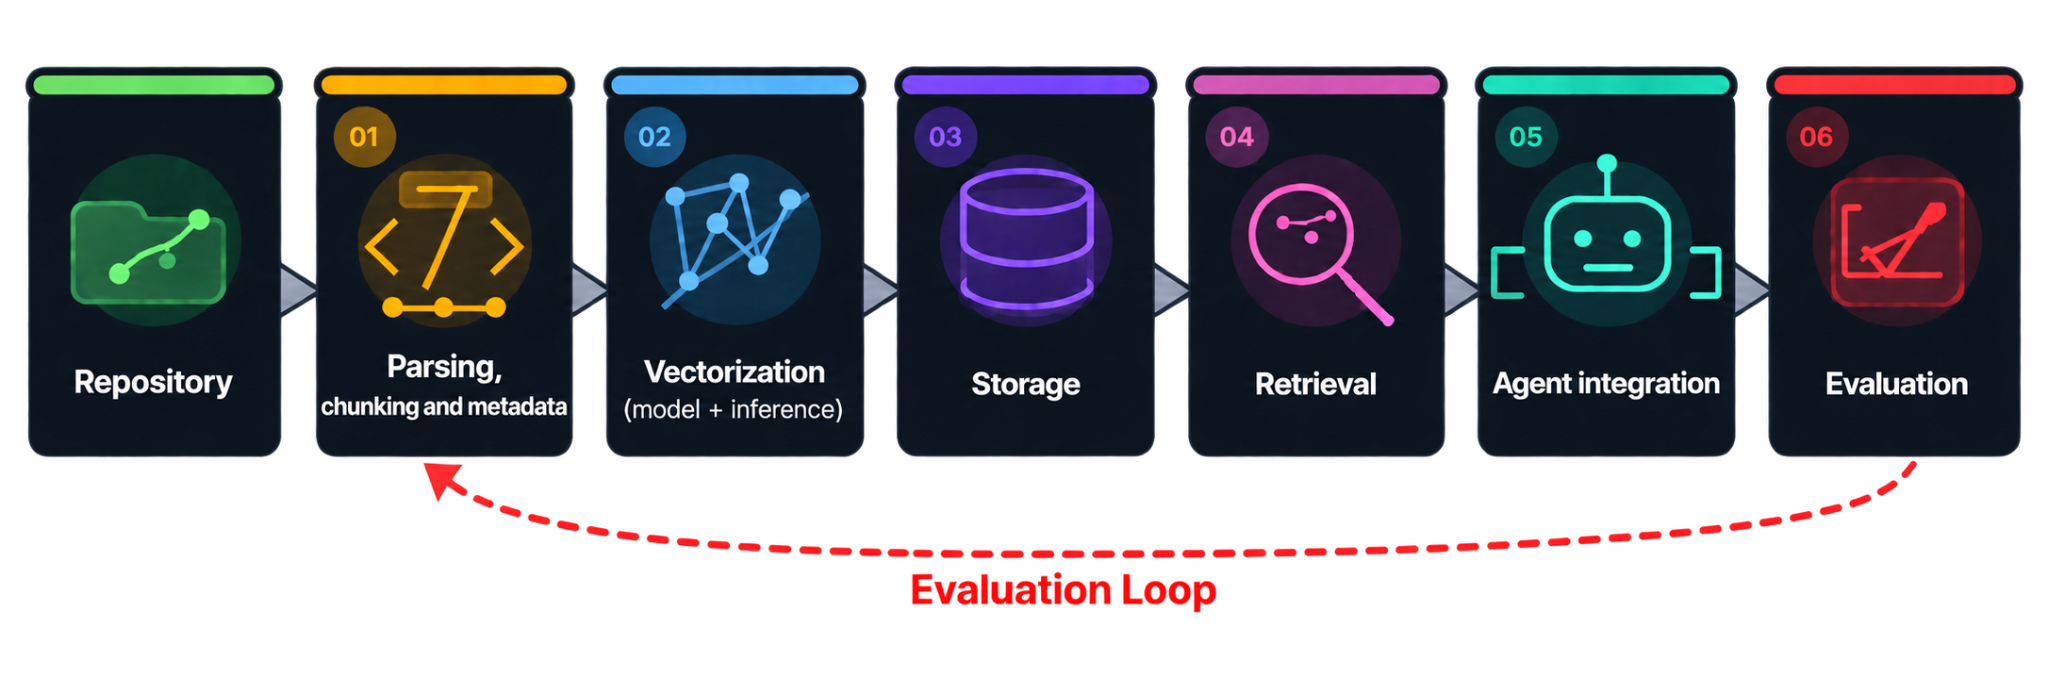
Building a RAG Pipeline for Semantic Code Search: A Developer Diary and Field Notes

Building a RAG Pipeline for Semantic Code Search: A Developer Diary and Field Notes

The JetBrains Blog3917 字 (约 16 分钟)
85

JetBrains分享了构建RAG管道进行语义代码搜索的实践经验,涵盖解析、分块、向量化等关键步骤,揭示生产环境中的技术挑战与优化策略。

入选理由:代码解析与分块是RAG管道的基础,需处理多语言语法差异

FeaturedArticle#RAG#语义搜索#代码库#JetBrains#AI英文

Related topics

跨材料问答 · 向量数据库、Embedding 与语义搜索实践

回答基于:向量数据库、Embedding 与语义搜索实践 专题下 27 条材料
    0 / 500

    AI may generate inaccurate information. Please verify important content.