T
traeai
Sign in

公司

什么是 Together AI?

也叫:togetherai

提供模型部署平台的AI公司

为什么现在值得关注?

最近变化

2026-10-19 · 支持LoRA训练和全权重实验,提升模型灵活性

Together AI 被反复提及时,通常意味着它正在影响产品路线、开发者工作流或 AI 产业判断。这个页面把分散材料合并成一个可持续更新的观察入口。

📰 Together AI 最新动态

已收录 30 篇与「Together AI」相关的 AI 资讯和分析。

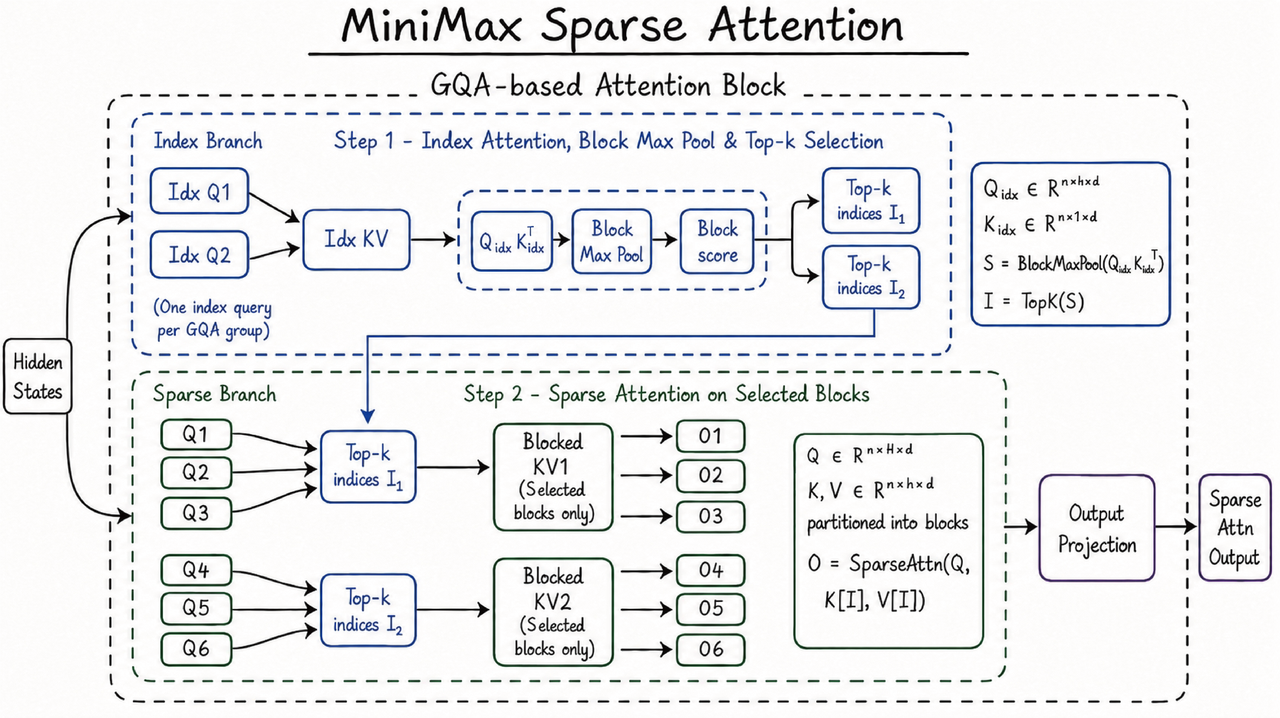
Serving MiniMax-M3 for efficient inference: Unlocking 1M-Token Context and Multimodality Without Regrets

Together AI optimized the deployment of MiniMax M3, achieving 81–125% throughput improvements through architectural and engineering innovations.

入选理由:MiniMax M3 supports 1M-token context and native multimodality, making it suitable for complex real-world tasks.

FeaturedArticle#MiniMax#M3#Sparse Attention#Multimodality#Inference Optimization英文
Together AI Blog 图标

Together Post-Training: frontier-grade model shaping, the way that fits you

Together AI Blog1964 字 (约 8 分钟)
85

Together AI推出Post-Training服务,提供灵活高效的自定义模型训练,无需重基础设施负担。

入选理由:支持LoRA训练和全权重实验,提升模型灵活性

FeaturedArticle#AI模型训练#自定义模型#Together AI#RL#SFT英文
Together AI Blog 图标

Meta Muse Spark Open is live on Together AI

Together AI Blog533 字 (约 3 分钟)
85

Meta Muse Spark Open模型在Together AI上线,支持1M-token上下文和多模态输入,适用于复杂代码重构场景。

入选理由:Muse Spark Open具备1M-token上下文窗口,可处理完整项目代码库

FeaturedArticle#Meta#Muse Spark Open#Together AI#模型#AI英文
Together AI Blog 图标

Expanding our enterprise inference capacity with IBM Cloud and NVIDIA

Together AI Blog341 字 (约 2 分钟)
85

Together AI联合IBM和NVIDIA构建全球最大规模NVIDIA B300 GPU推理集群,实现企业级AI推理能力突破。

入选理由:NVIDIA B300 GPU集群首次部署于IBM Cloud,支持万亿级token月处理量

FeaturedArticle#AI推理#IBM Cloud#NVIDIA B300#企业级AI英文
Together AI Blog 图标

The Open Source AI Stack

Together AI Blog3158 字 (约 13 分钟)
85

开源AI堆栈包含模型、推理、网关、Harness和工具五层,开发者可灵活切换模型并优化成本与性能。

入选理由:MIGHT堆栈各层独立,允许快速替换模型以适应不同任务需求。

FeaturedArticle#AI#开源#模型#架构#开发英文
Together AI Blog 图标

Introducing preemptible compute: the same compute, half the price

Together AI Blog905 字 (约 4 分钟)
85

Together AI推出预占式计算,以一半价格提供相同GPU资源,适用于中断容忍型任务。

入选理由:预占式节点按50%按需价格计费且支持亚小时计费

FeaturedArticle#Kubernetes#GPU计算#成本优化#云服务英文
Together AI Blog 图标

GLM-5.3 vs. Claude Fable 5 on DeepSWE: Cost, Coding, and Routing

Together AI Blog2243 字 (约 9 分钟)
85

GLM-5.3在DeepSWE基准测试中成本仅为Claude Fable 5的1/5,且在多尝试指标上表现更优。

入选理由:GLM-5.3每任务成本为$3.99,Claude Fable 5为$21.63,成本差距达5.4倍。

FeaturedArticle#GLM-5.3#Claude Fable 5#DeepSWE#模型比较英文
Together AI Blog 图标

GLM-5.3 vs. GPT-5.6 Sol on DeepSWE: Cost, Coding, and Routing

Together AI Blog2192 字 (约 9 分钟)
85

GLM-5.3在多次尝试下表现优于GPT-5.6 Sol,且成本更低,但单次尝试中GPT-5.6 Sol稍胜一筹。组合使用可覆盖106/113任务,性价比达85.9%。

入选理由:GLM-5.3单次尝试成本3.99美元,解决率69.0%,GPT-5.6 Sol成本8.37美元,解决率72.7%

FeaturedArticle#GLM-5.3#GPT-5.6#DeepSWE#模型对比英文
Together AI Blog 图标

GLM-5.3 vs. GLM-5.3 Flash on DeepSWE: Cost, Coding, and Routing

Together AI Blog2838 字 (约 12 分钟)
85

GLM-5.3 Flash以1/17成本解决15倍任务,首次尝试性能落后5.6%但多次重试后差距缩小至2.6%。

入选理由:GLM-5.3 Flash成本为GLM-5.3的1/17,但每100美元解决任务数是其15倍。

FeaturedArticle#模型对比#GLM-5.3#DeepSWE#蒸馏模型英文
Together AI Blog 图标

DeepSeek-V4 Flash 0731 vs GPT-5.6 Luna on DeepSWE: Cost and Coding

Together AI Blog2024 字 (约 9 分钟)
85

DeepSeek-V4 Flash 0731成本仅为GPT-5.6 Luna的1/6,但组合使用时在准确率和成本上均优于单独使用Luna。

入选理由:GPT-5.6 Luna单次任务准确率67.2%,DeepSeek-V4 Flash为53.3%,但后者成本仅0.10美元/任务。

FeaturedArticle#模型比较#成本分析#AI#DeepSWE英文
Together AI Blog 图标

A/B test models in production

Together AI Blog1936 字 (约 8 分钟)
85

Together AI平台提供端点级A/B测试方案,通过动态流量分配验证LLM模型效果,避免传统方法的基础设施耦合问题。

入选理由:Together AI平台在端点层实现A/B测试,无需修改客户端代码

FeaturedArticle#A/B测试#LLM#生产环境#Together AI#技术实践英文
Together AI Blog 图标

DeepSeek V4 Pro 0813 vs Claude Fable 5 on DeepSWE: Cost, Coding, and Routing

Together AI Blog1837 字 (约 8 分钟)
85

组合使用DeepSeek V4 Pro 0813和Claude Fable 5可解决82.7%的DeepSWE任务,成本仅8.28美元,比单独使用Claude节省62%费用。

入选理由:DeepSeek V4 Pro 0813首次尝试解决62.8%任务,成本仅0.24美元/次

FeaturedArticle#DeepSeek V4 Pro 0813#Claude Fable 5#DeepSWE#模型比较#成本分析英文
Together AI Blog 图标

DeepSeek V4 Pro 0813 vs GPT-5.6 Sol on DeepSWE: Cost, Coding, and Routing

Together AI Blog1888 字 (约 8 分钟)
85

DeepSeek V4 Pro 0813成本仅为GPT-5.6 Sol的1/35,但多次尝试后表现更优,适合预算有限且允许重试的任务。

入选理由:DeepSeek V4 Pro 0813每轮成本0.24美元,GPT-5.6 Sol为8.37美元,价格差距达35倍。

FeaturedArticle#DeepSeek V4 Pro#GPT-5.6 Sol#DeepSWE#成本分析#模型对比英文
Together AI Blog 图标

ThunderAgent通过优化KV缓存管理,实现单节点吞吐量提升2倍,集群加速2.4倍,解决代理推理中的缓存抖动问题。

入选理由:单节点吞吐量提升2.5倍,P50延迟降低10倍

FeaturedArticle#ThunderAgent#合成数据生成#LLM推理优化#KV缓存管理英文
Together AI Blog 图标

Configuring Dedicated Model Inference

Together AI Blog1796 字 (约 8 分钟)
85

Together AI平台通过端点/部署/配置三元组与容量感知路由实现模型推理配置,支持零停机变更和流量实验。

入选理由:配置由端点(固定身份)、部署(模型+硬件组合)、配置(运行配方)三部分构成

FeaturedArticle#模型推理#部署配置#流量管理#AI平台英文
Together AI Blog 图标

Together AI与Moonshot AI合作推出2.8T参数开源模型Kimi K3,支持长上下文和视觉任务,开发者可直接通过其平台部署和微调。

入选理由:Kimi K3是当前参数规模最大的开源模型(2.8T),支持1M token上下文窗口。

FeaturedArticle#AI模型#开源#Moonshot AI#Together AI英文
Together AI Blog 图标

Autoscaling endpoints for LLM inference

Together AI Blog2237 字 (约 9 分钟)
85

Together AI平台通过自适应扩展端点,结合LLM推理特有的指标(如TTFT、GPU利用率),实现更高效的资源管理,减少过量和不足配置的成本。

入选理由:选择TTFT和GPU利用率作为指标可有效平衡资源成本

FeaturedArticle#LLM推理#自适应扩展#Together AI#GPU优化英文
Together AI Blog 图标

Kimi K3: The Complete Developer Guide

Together AI Blog3077 字 (约 13 分钟)
85

Kimi K3是首个2.8万亿参数开源模型,支持1M上下文和高效推理,适用于复杂编程与知识工作。

入选理由:Kimi K3参数量达2.8万亿,是首个3万亿参数级开源模型

FeaturedArticle#Kimi K3#开源模型#AI架构#Together AI英文
Together AI Blog 图标

Kimi K3 vs Claude Fable 5 on DeepSWE: Cost and Coding

Together AI Blog1176 字 (约 5 分钟)
85

Kimi K3在DeepSWE基准测试中以1/3成本超越Claude Fable 5,多次尝试后性能反超,但后者可靠性更高。

入选理由:Kimi K3单次任务成本仅4.65美元,为Claude Fable 5的1/3

FeaturedArticle#Kimi K3#Claude Fable 5#DeepSWE#模型比较英文
Together AI Blog 图标

What does 99.9% uptime mean for inference?

Together AI Blog1508 字 (约 7 分钟)
85

不同可靠性级别(99%、99.9%、99.99%)对应不同的故障域和架构要求,如99%需处理节点级故障,99.9%需跨数据中心部署,99.99%需多区域冗余。

入选理由:99%可靠性需处理GPU硬件故障,依赖自动化健康检查和快速替换

FeaturedArticle#AI推理#可靠性#架构设计#故障域#Together AI英文
Together AI Blog 图标

The production platform for open-weight AI inference

Together AI Blog1714 字 (约 7 分钟)
85

Together AI推出的新推理平台使用户能高效部署和管理开放权重模型,兼顾控制、成本与性能。

入选理由:开放权重模型成本仅为封闭模型的几分之一,但质量相当。

FeaturedArticle#AI推理平台#开放权重模型#模型部署#Together AI英文
Strong results

Strong results

Aravind Srinivas(@AravSrinivas)83 字 (约 1 分钟)
85

Kimi K3在软件工程任务中性能与Claude Fable 5相当,但价格仅为后者35%。

入选理由:Kimi K3价格仅为Claude Fable 5的35%但性能相同

FeaturedTweet#模型对比#软件工程#AI性能#成本效益英文
Together AI Blog 图标

Together AI brings Thinking Machines Lab’s new model Inkling on day 0

Together AI Blog1068 字 (约 5 分钟)
85

Inkling是Thinking Machines Lab推出的多模态模型,支持高效推理和跨任务能力,Together AI提供生产级部署服务。

入选理由:Inkling通过query-conditioned attention和MoE架构实现多模态高效推理

FeaturedArticle#Inkling#多模态模型#推理平台#Together AI英文
Together AI Blog 图标

Building trust in enterprise AI: Together AI earns ISO 27001:2022 certification

Together AI Blog427 字 (约 2 分钟)
85

Together AI 获得 ISO 27001:2022 认证,证明其信息安全管理符合国际标准,增强客户对其平台安全性的信任。

入选理由:Together AI 获得 ISO 27001:2022 认证,由 A-LIGN Compliance 和 Security 颁发。

FeaturedArticle#AI#信息安全#ISO 27001#Together AI英文
Engineering voice agents: Latency, quality, and scale — Rishabh Bhargava, Together AI

Building high-quality, low-latency, scalable voice agents is now an engineering challenge requiring real-time response (<500ms), complex instruction handling, and tool calling — supported by Together AI’s infrastructure.

入选理由:语音代理必须在500毫秒内响应,否则用户会挂断电话,实时性是核心指标。

FeaturedVideo#Voice AI#Latency Optimization#Together AI#Agent Engineering英文
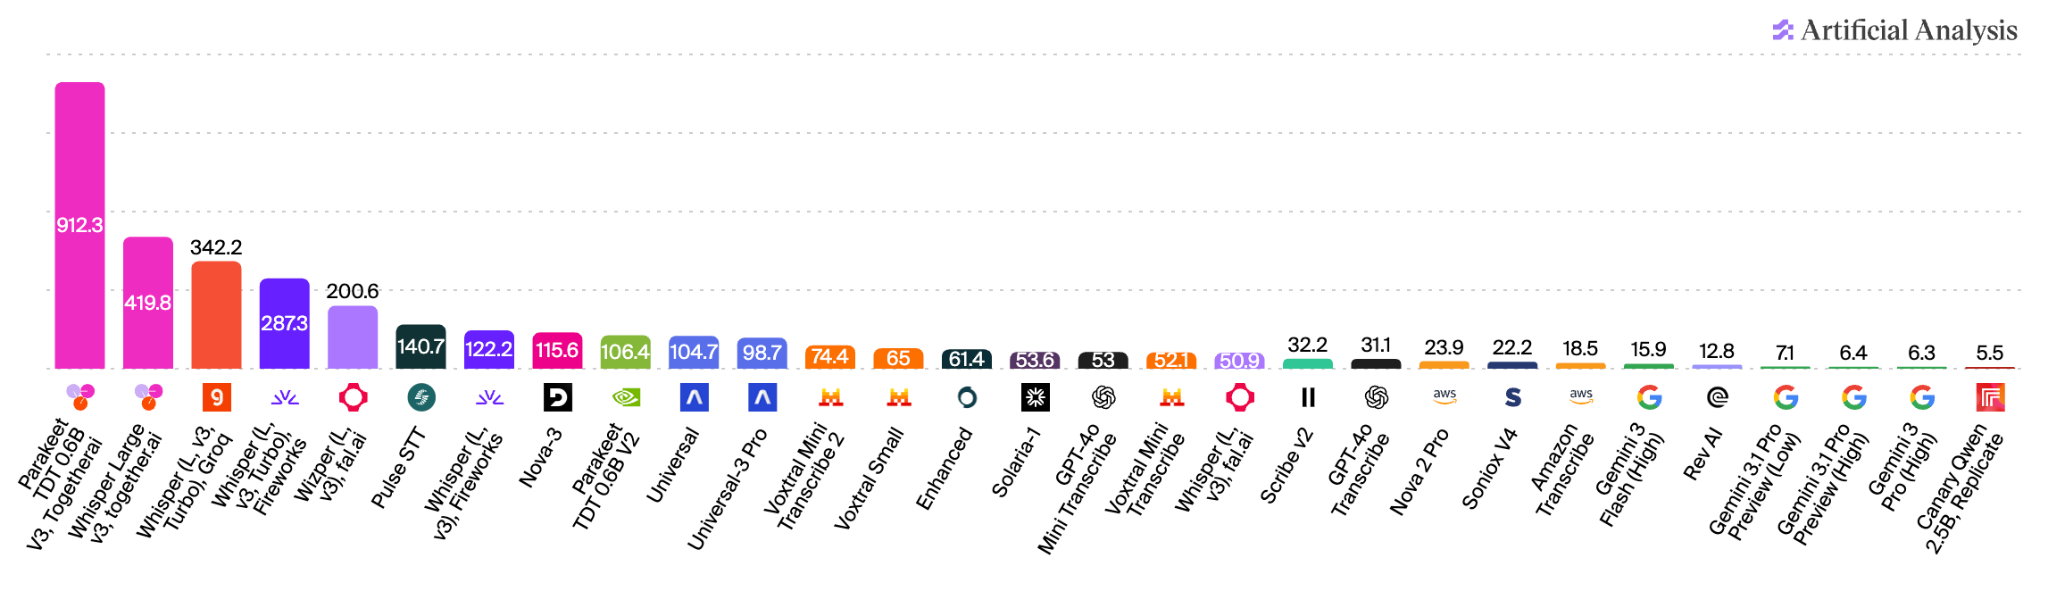
How Together AI built the world’s fastest speech-to-text stack

How Together AI built the world’s fastest speech-to-text stack

Together AI Blog1720 字 (约 7 分钟)
85

Together AI optimized their speech-to-text stack, achieving faster transcription speeds by using profile-aware TensorRT, optimizing the decoder loop, and improving CPU paths. They serve the two lowest-latency models, with the fastest model transcribing 20 hours of speech in under 10 seconds.

入选理由:Together AI built the world's fastest speech-to-text stack.

FeaturedArticle#Together AI#speech-to-text英文
Benchmarking inference at scale: coding agents

Benchmarking inference at scale: coding agents

Together AI Blog1358 字 (约 6 分钟)
85

Together Inference Engine delivers 31% more TPS than next fastest OSS engine on same hardware, maintains 2× better TTFT at saturation. Performance gains come from full-stack optimization.

入选理由:ThunderMLA、自定义内核重写和端到端优化使Together引擎比其他OSS引擎多31%的TPS

FeaturedArticle#Together AI#Inference Engine#Coding Agent#Performance Optimization#TTFT英文
Together AI and Pearl Research Labs Team Up to Reduce the Cost of AI Inference

Together AI and Pearl Research Labs Team Up to Reduce the Cost of AI Inference

Together AI Blog979 字 (约 4 分钟)
85

Together AI and Pearl Research Labs have partnered to reduce AI inference costs through technologies like FlashAttention-4 and ATLAS.

入选理由:FlashAttention-4 提升推理速度达 1.3 倍。

FeaturedArticle#AI#Inference Optimization英文

与「Together AI」经常一起出现的 AI 术语。

💡 想追踪「Together AI」的长期趋势?去 实体雷达 · Together AI 查看详细分析和跨材料问答。

AI may generate inaccurate information. Please verify important content.