T
traeai
Sign in

概念

什么是 GPU?

也叫:图形处理器

图形处理单元,用于加速AI训练中的计算任务

为什么现在值得关注?

最近变化

2026-10-20 · 操作能力差异使相同GPU产出差异达50%

GPU 被反复提及时,通常意味着它正在影响产品路线、开发者工作流或 AI 产业判断。这个页面把分散材料合并成一个可持续更新的观察入口。

📰 GPU 最新动态

已收录 30 篇与「GPU」相关的 AI 资讯和分析。

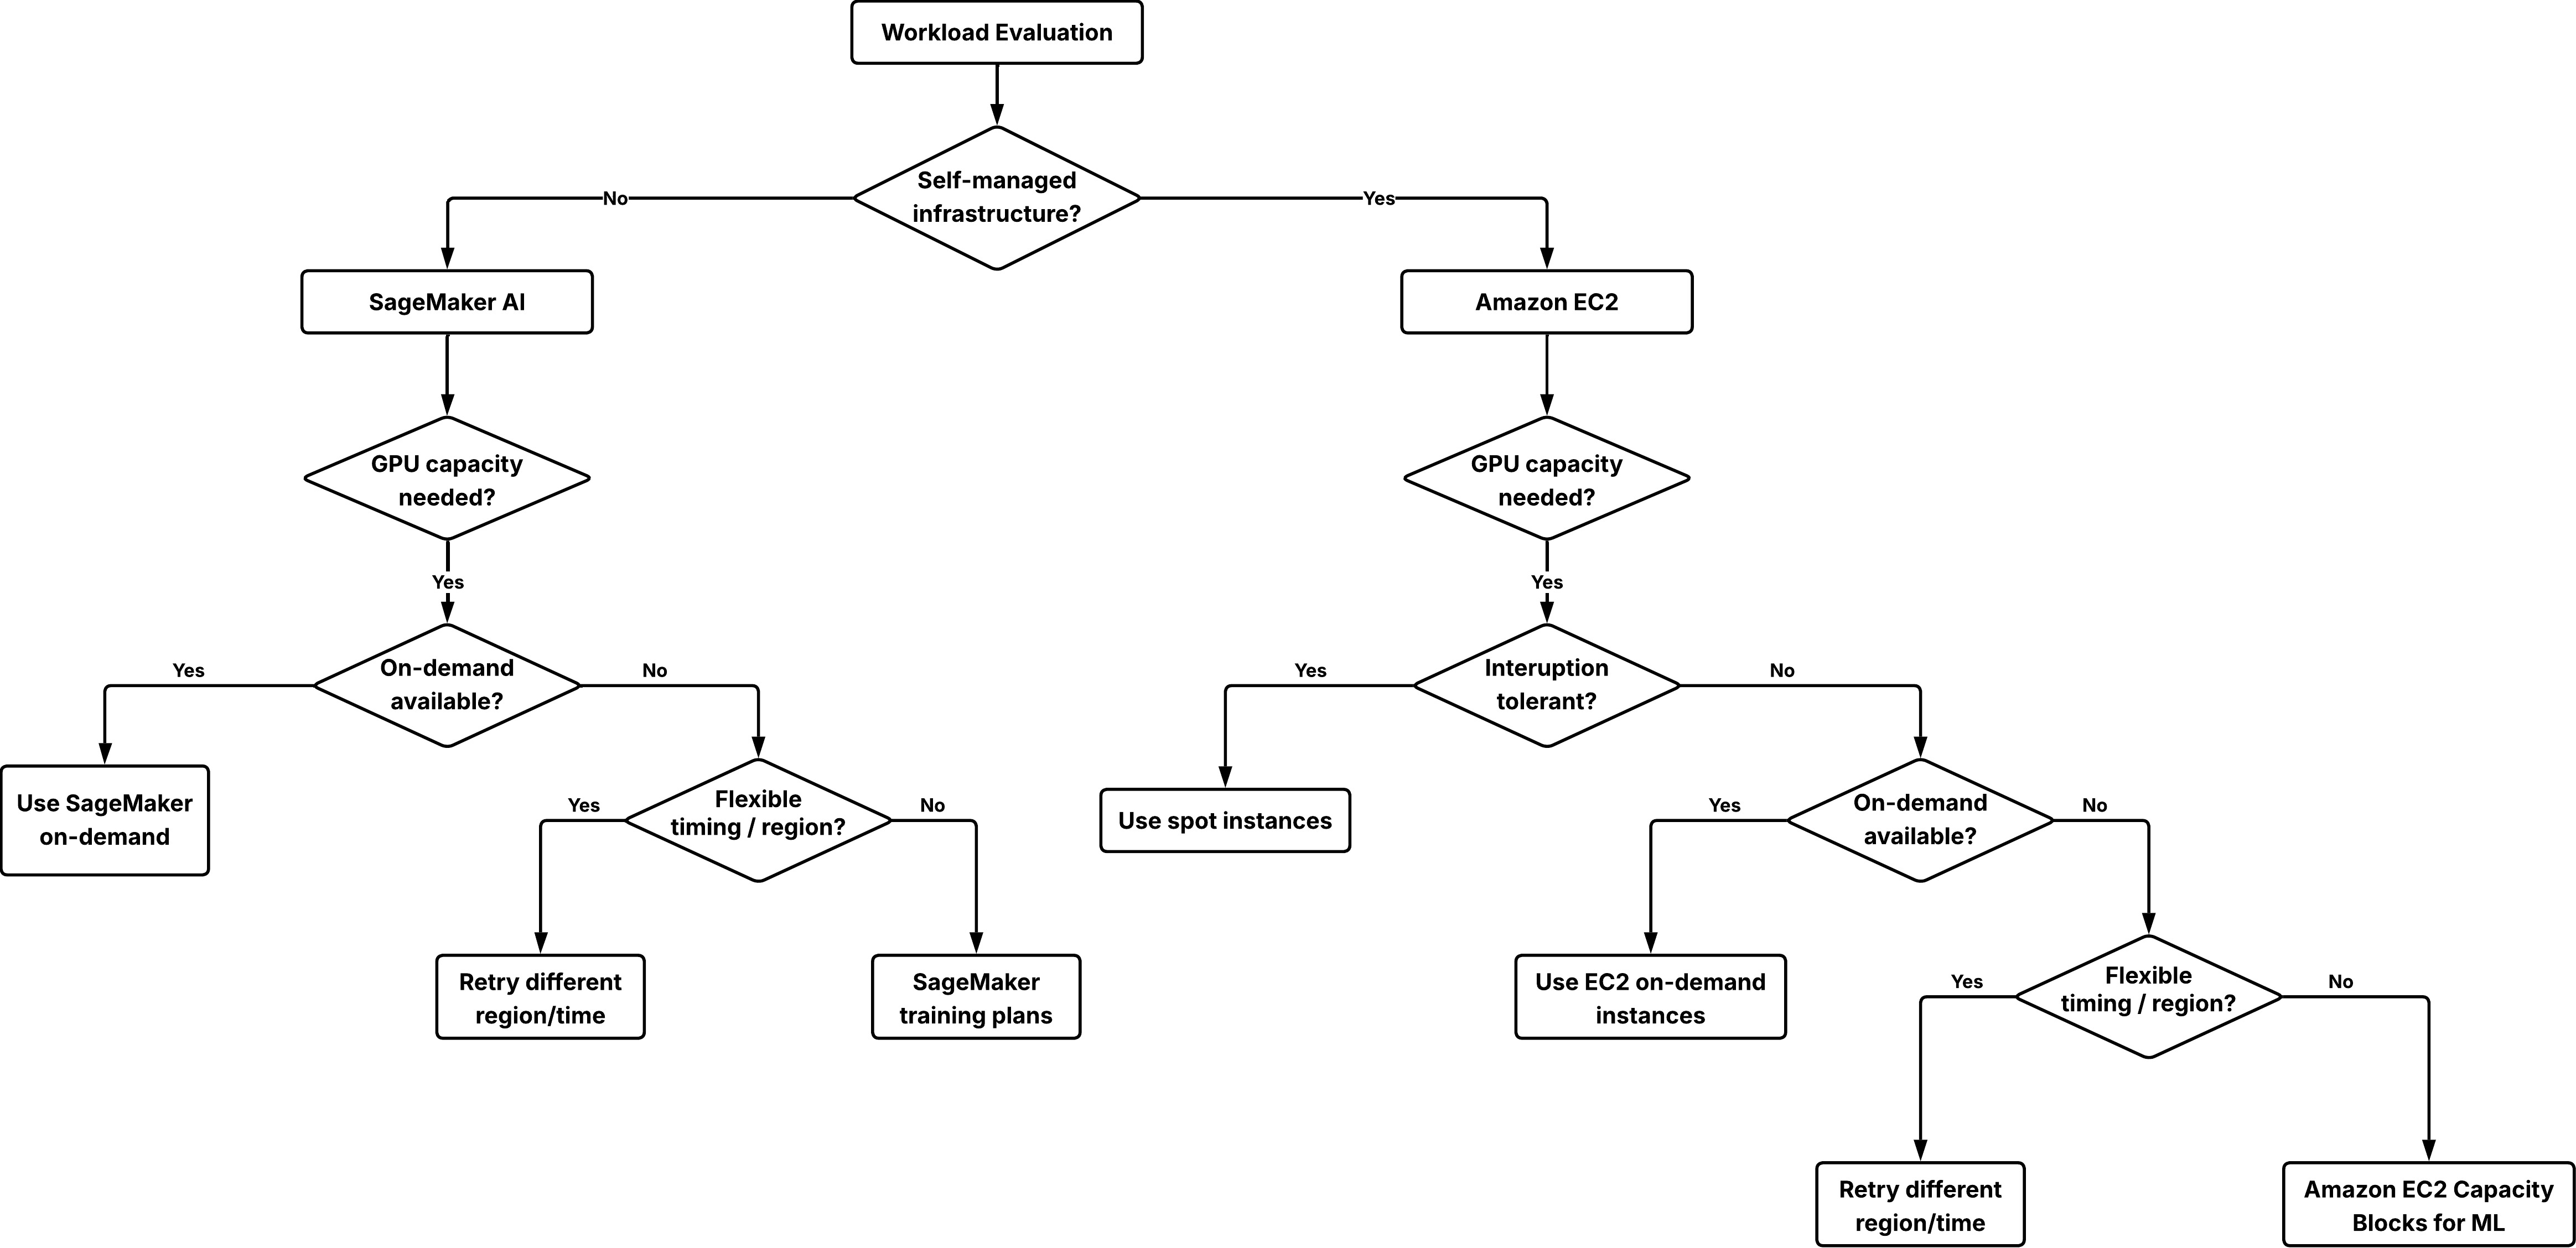
Secure short-term GPU capacity for ML workloads with EC2 Capacity Blocks for ML and SageMaker training plans

Secure Short-Term GPU Capacity with EC2 Capacity Blocks for ML and SageMaker Training Plans

AWS Machine Learning Blog2352 字 (约 10 分钟)
87

AWS introduces EC2 Capacity Blocks for ML and SageMaker Training Plans to help users reserve short-term GPU resources at discounted prices, suitable for load testing, model validation, and temporary tasks.

入选理由:EC2 Capacity Blocks 提供 40-50% 折扣并保障短期 GPU 资源可用。

FeaturedArticle#AWS#GPU#Machine Learning#Cloud Computing#Capacity Management中文
Announcing llm-d 1.0: Open distributed inference for agents on Google Cloud TPUs and GPUs

Google Cloud 发布 llm-d 1.0,通过缓存感知路由和分层 KV 缓存优化多步骤代理推理,支持 TPU/GPU 混合部署。

入选理由:llm-d 1.0 支持 1000 个代理实例并发处理,通过分层 KV 缓存降低 40% 内存占用

FeaturedArticle#Kubernetes#LLM#分布式推理#Google Cloud#TPU英文
Liquid Cooling for AI Data Centers: Run Cold, Act Bold

Liquid Cooling for AI Data Centers: Run Cold, Act Bold

CoreWeave1178 字 (约 5 分钟)
85

液冷技术显著提升AI数据中心GPU性能并减少环境影响,CoreWeave通过直接到芯片的液冷方案成为行业领导者。

入选理由:直接到芯片液冷使周围空气温度上升减少50%

FeaturedArticle#液冷技术#AI数据中心#CoreWeave#GPU性能优化英文
From 15% to 90% GPU Utilization: Fix the Data Pipeline, Not the Model

From 15% to 90% GPU Utilization: Fix the Data Pipeline, Not the Model

AI Engineer3470 字 (约 14 分钟)
85

优化数据管道而非模型可使GPU利用率从15%提升至90%,关键在并发处理、预取和减少数据复制。

入选理由:GPU利用率瓶颈常出现在数据预处理阶段而非模型计算

FeaturedVideo#GPU优化#数据管道#多模态训练#AI工程英文
Red Hat AI 图标

How AI inference works, clearly explained

Red Hat AI2212 字 (约 9 分钟)
85

AI推理依赖模型权重、推理服务器和GPU协同工作,KV缓存优化可降低延迟和成本。

入选理由:推理服务器(如vLLM)是实现生产级GPU利用率的关键组件

FeaturedArticle#AI推理#LLM#KV缓存#优化#Red Hat英文
Hugging Face Blog 图标

GPU Management: Why Idle GPUs Are the New Grounded Aircraft

Hugging Face Blog3392 字 (约 14 分钟)
85

GPU利用率决定AI企业经济性,类似航空业飞机利用率,闲置GPU成为新瓶颈。

入选理由:GPU成本按日历小时计算,收益仅来自计算小时

FeaturedArticle#GPU管理#AI基础设施#资源优化英文
Red Hat AI 图标

Make every GPU-hour count: Progress tracking in Red Hat OpenShift AI

Red Hat AI2014 字 (约 9 分钟)
85

Red Hat OpenShift AI通过实时训练进度跟踪和自动化中断机制,帮助用户节省高达70%的GPU资源浪费。

入选理由:实时指标收集可减少70%的GPU资源浪费

FeaturedArticle#GPU优化#Red Hat OpenShift AI#机器学习#资源管理英文
Machine Learning Mastery 图标

Static vs. Dynamic vs. Continuous Batching in LLM Inference

Machine Learning Mastery1530 字 (约 7 分钟)
85

静态批处理在LLM推理中存在显著延迟问题,动态批处理通过超时窗口优化,连续批处理则需在token层级调度以提升吞吐。

入选理由:静态批处理导致请求延迟与批次填充速度强相关,最长请求决定整体处理时间。

FeaturedArticle#LLM#批处理#AI推理#GPU优化英文
Hugging Face Journal Club: AsyncOPD and How Stale Can On-Policy Distillation Be?

异步策略蒸馏(AsyncOPD)在强化学习中可能导致学生策略与教师策略的log概率差异,引发不稳定性,Verl库通过k-step off-policy方法缓解此问题。

入选理由:异步方法允许生成与训练并行,但可能因策略过时导致log概率差异扩大

FeaturedVideo#强化学习#策略蒸馏#异步方法#Verl英文
Google Cloud Blog 图标

Autopilot Clusters with GKE managed DRANET: GPUs and TPUs

Google Cloud Blog951 字 (约 4 分钟)
85

Google Cloud Blog详解GKE Autopilot集群配置DRANET支持GPU/TPU的完整流程,包含代码示例和参数说明。

入选理由:GKE Autopilot集群部署需指定VPC网络和预留资源URL

FeaturedArticle#GKE#Autopilot#DRANET#GPU#TPU英文
DeepSeek Just Solved AI's Billion Dollar Problem

DeepSeek Just Solved AI's Billion Dollar Problem

Two Minute Papers1202 字 (约 5 分钟)
85

DeepSeek通过优化AI芯片的利用效率,解决了AI系统计算资源浪费的问题,使AI运行更高效。

入选理由:AI系统中存在计算资源浪费问题,GPU利用率仅40%。

FeaturedVideo#AI#DeepSeek#计算效率#芯片优化英文
Towards Data Science 图标

The Hardware That Makes AI Possible

Towards Data Science1293 字 (约 6 分钟)
85

现代AI依赖于专用硬件如GPU、TPU和NPU,它们在并行计算和大规模数据处理上表现优异。

入选理由:AI训练需要执行万亿次数学运算,传统CPU无法高效完成。

FeaturedArticle#AI#硬件#GPU#TPU#NPU英文
The Story Behind Cerebras’ $63 Billion IPO with Founder and CEO Andrew Feldman

Cerebras' AI computers achieve 15-20x faster inference than GPUs, secured a $20B deal with OpenAI, and expanded through AWS cloud deployment, driving AI infrastructure innovation.

入选理由:Cerebras的AI推理速度比GPU快15-20倍,覆盖所有规模模型

FeaturedVideo#Cerebras#AI Chips#OpenAI#AWS#IPO英文
Cloud Storage Rapid: Turbocharged object storage for AI and analytics

Cloud Storage Rapid: Turbocharged Object Storage for AI and Analytics

Google Cloud Blog1594 字 (约 7 分钟)
85

Cloud Storage Rapid offers high-performance object storage solutions, significantly enhancing the efficiency of AI and analytics workloads.

入选理由:Rapid Bucket 提供高达 2000 万次查询每秒和亚毫秒级延迟。

FeaturedArticle#Google Cloud#AI#Object Storage#Performance Optimization英文
GPU Forecasters

Language Models as Selective Surrogates for Kernel Runtime Optimization

This article explores a new approach to GPU kernel runtime optimization using language models as selective surrogates, achieving significant performance improvements by predicting and selecting optimal kernel configurations.

入选理由:语言模型被用作选择性代理,预测 GPU 内核的最佳配置。

FeaturedTweet#GPU#Language Models#Kernel Optimization#Runtime Performance#AI Acceleration英文
We’re brining local models that can run on your personal hardware inside Perplexity Computer. This w...

Perplexity Computer Launches Hybrid Local and Cloud Model Inference

Aravind Srinivas(@AravSrinivas)161 字 (约 1 分钟)
75

Perplexity Computer is introducing hybrid local and cloud model inference, enhancing privacy, energy efficiency, and task optimization, with a soon-to-be release.

入选理由:本地模型运行于用户硬件,确保数据隐私。

FeaturedTweet#AI#Local Models#Hybrid Inference#Privacy#Perplexity英文
CPU vs GPU vs TPU

CPU vs GPU vs TPU

ByteByteGo1129 字 (约 5 分钟)
75

CPU, GPU, and TPU are optimized for different computation types: CPU handles general-purpose tasks with branching logic, GPU excels at parallel math operations like matrix multiplication, and TPU is specialized for machine learning tensor operations, guiding hardware selection for AI workloads.

入选理由:CPU has few powerful cores optimized for general-purpose tasks like web servers and databases with branching logic.

FeaturedVideo#CPU#GPU#TPU#Machine Learning#Hardware Acceleration英文
a16z(@a16z) 图标

AI新云公司面临与LoudCloud相反的供需失衡风险,当前GPU短缺和数据中心成本上涨形成有利条件,但债务市场独立风险仍需警惕。

入选理由:1999年带宽价格从$1500/Mbps降至2001年$50/Mbps,长期合约风险凸显

FeaturedTweet#云计算#AI基础设施#CoreWeave#供需关系中英混合
how do you like them convolutions

how do you like them convolutions

Thomas Wolf(@Thom_Wolf)87 字 (约 1 分钟)
60

文章内容为名人对AI技术的浅层兴趣陈述,缺乏技术深度和实用价值,不适合作为工程师学习材料。

入选理由:Ben Affleck自称了解卷积神经网络但未提供技术细节

FeaturedTweet#卷积神经网络#Python#GPU#OpenAI#Google中英混合
Ben Affleck?

the AI engineer?

Ben Affleck? the AI engineer?

Hesam(@Hesamation)81 字 (约 1 分钟)
60

Ben Affleck分享了他对AI和计算机的兴趣及部分技术背景,但文章缺乏深度技术内容。

入选理由:Ben Affleck懂Python并了解卷积神经网络技术

FeaturedTweet#AI#名人#技术背景英文
Can’t put the genie back in the GPU.

Can’t put the genie back in the GPU.

Naval(@naval)66 字 (约 1 分钟)
60

文章讨论了AI技术的不可逆发展,强调其带来的深远影响。

入选理由:AI技术发展不可逆,需提前规划应对。

FeaturedTweet#AI#技术趋势#GPU英文
刚刚,马斯克官宣xAI解散,22万张GPU算力租给Anthropic

The article reports Elon Musk's announcement of dissolving the xAI team and leasing 220,000 GPUs to Anthropic but lacks technical depth.

入选理由:马斯克宣布解散xAI团队,原因未详细说明。

FeaturedArticle#AI#GPU#Elon Musk中文

与「GPU」经常一起出现的 AI 术语。

💡 想追踪「GPU」的长期趋势?去 实体雷达 · GPU 查看详细分析和跨材料问答。

AI may generate inaccurate information. Please verify important content.