T
traeai
Sign in

公司

什么是 Fireworks AI?

也叫:Fireworks

提供AI模型服务的公司,发生2026年10月安全事件

为什么现在值得关注?

最近变化

2026-10-10 · 2026年10月6日发现凭证泄露,10月9日完成API密钥轮换

Fireworks AI 被反复提及时,通常意味着它正在影响产品路线、开发者工作流或 AI 产业判断。这个页面把分散材料合并成一个可持续更新的观察入口。

📰 Fireworks AI 最新动态

已收录 30 篇与「Fireworks AI」相关的 AI 资讯和分析。

Frontier models are powerful advisors.

On @harvey's Legal Agent Benchmark, a GLM 5.1 worker using C...

Frontier models are powerful advisors.

Fireworks AI(@FireworksAI_HQ)188 字 (约 1 分钟)
87

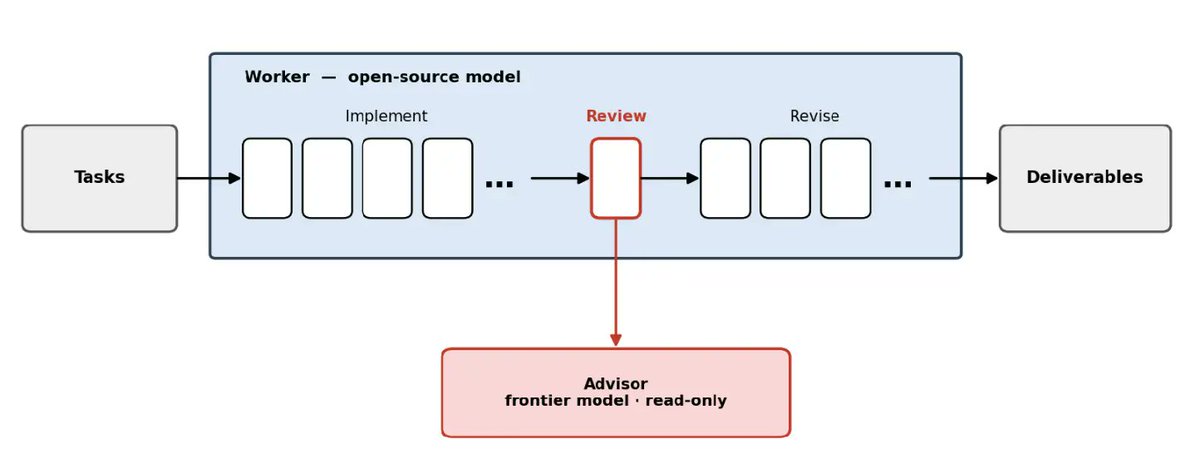
Fireworks AI demonstrates that GLM 5.1, when using Claude Opus 4.7 as a sparse advisor in the Legal Agent Benchmark, achieves 18/100 all-pass versus 14/100 for Opus alone at 39% of the cost.

入选理由:在 Harvey 法务代理基准上,GLM 5.1 + Claude Opus 4.7 稀疏顾问方案全对数达 18/100。

FeaturedTweet#Frontier Models#Legal Agent Benchmark#harness design#advisor pattern#Claude Opus 4.7英文
Fireworks AI(@FireworksAI_HQ) 图标

https://t.co/oUF0pfafrU

Fireworks AI(@FireworksAI_HQ)548 字 (约 3 分钟)
85

Fireworks AI 2026 年 10 月安全事件影响部分客户账户,未涉及数据泄露,已采取措施并通知客户。

入选理由:2026年10月6日发现凭证泄露,10月9日完成API密钥轮换

FeaturedTweet#安全#AI#企业安全#API管理英文
Fireworks AI(@FireworksAI_HQ) 图标

DeepSeek V4.1-Flash在DeepSWE基准测试中以1/15的成本实现与GPT-6 Astra相当的性能,输入token占比达174:1且缓存命中率高达99.6%。

入选理由:输入token数量是输出的174倍,占成本计算的60%。

FeaturedTweet#DeepSeek V4.1-Flash#模型成本分析#Fireworks AI#DeepSWE#AI架构中英混合
Fireworks AI(@FireworksAI_HQ) 图标

Fireworks AI 现已支持 DeepSeek V4 Flash 0731 模型的微调训练,提供 SFT/DPO/RL 三种训练方式,适用于编码代理和高并发场景,成本较传统方案降低 70%。

入选理由:DeepSeek V4 Flash 0731 可通过 Fireworks API 进行 SFT/DPO/RL 训练

FeaturedTweet#Fireworks AI#DeepSeek#模型微调#SFT#DPO英文
There’s only one way to find out: https://t.co/Y9fxZCNrbD

There’s only one way to find out: https://t.co/Y9fxZCNrbD

Fireworks AI(@FireworksAI_HQ)112 字 (约 1 分钟)
85

GLM 5.2 在性能和效率上表现优异,接近甚至超越 GPT 5.5 和 Opus 4.8。

入选理由:GLM 5.2 在处理长上下文和复杂任务时表现出色。

FeaturedTweet#GLM 5.2#Fireworks AI#AI模型#自然语言处理中英混合
Many research labs only consider inference efficiency after the fact. Step 3.7 Flash is a 196B MoE m...

Step 3.7 Flash: A 196B MoE Model Built for Inference Efficiency

Fireworks AI(@FireworksAI_HQ)183 字 (约 1 分钟)
85

Step 3.7 Flash is a 196B MoE model designed from the ground up for inference efficiency, using MFA and AFD techniques to reduce KV-cache usage to ~22% of DeepSeek, supporting agent, coding, and multimodal workflows, open-sourced under Apache 2.0 and available on Fireworks.

入选理由:Step 3.7 Flash 是 196B MoE 模型,从设计之初就聚焦推理效率,而非事后优化。

FeaturedTweet#Step 3.7 Flash#MoE#Inference Optimization#Fireworks AI#Apache 2.0英文
10/ The bigger point: your product is the best RL environment you'll ever have.

Frontier labs ship ...

10/ The bigger point: your product is the best RL environment you'll ever have.

Fireworks AI(@FireworksAI_HQ)201 字 (约 1 分钟)
85

Fireworks AI provides a view that the success of a product lies in its uniqueness and adaptability as an RL environment.

入选理由:产品的独特性是其最大的护城河。

FeaturedTweet#Reinforcement Learning#Product Design#Moat中文
We ran 720 browser agent tasks with @nottecore across frontier models. 

One baseline model produced...

Fireworks AI on X: We ran 720 browser agent tasks with @nottecore across frontier models

Fireworks AI(@FireworksAI_HQ)236 字 (约 1 分钟)
85

Fireworks AI tests show baseline models had 20% retry rates in browser agent tasks, while Kimi K2.5/GLM-5/MiniMax M2.5 achieved near-zero retries with stable latency, directly impacting production system costs/delays/reliability.

入选理由:基线模型在5次调用中约1次输出畸形,导致多步骤工作流重试

FeaturedTweet#Fireworks AI#Browser Agents#Model Execution#Retry Rates#Cost Optimization英文
Fine-tuning used to mean a team, a GPU cluster, and weeks of iteration.

Now it's just a CLI command...

Fine-tuning used to mean a team, a GPU cluster, and weeks of iteration.

Fireworks AI(@FireworksAI_HQ)167 字 (约 1 分钟)
85

Fireworks AI states that model fine-tuning now requires only a CLI command, 10 minutes of GPU time, and a few cents of compute cost, with full ownership of the weights. While 2026's off-the-shelf open models are sufficient for deployment, they remain just a starting point.

入选理由:模型微调时间从数周团队协作缩短到10分钟GPU计算,成本仅需几美分

FeaturedTweet#Fireworks AI#Model Fine-tuning#LLM#CLI#GPU Optimization英文
https://t.co/4jMbhaYQe3

The Fine-Tuning Bottleneck Isn't the Algorithm

Fireworks AI(@FireworksAI_HQ)1708 字 (约 7 分钟)
85

Fine-tuning bottlenecks aren’t about algorithms—they’re about integration complexity, slow iteration cycles, and unclear SFT vs RFT vs DPO choices. Fireworks AI enables secure, fast, and scalable tuning.

入选理由:团队瓶颈不在训练算法,而在数据隔离、迭代速度和模型选择(SFT/RFT/DPO)

FeaturedTweet#Fine-Tuning#AI Infrastructure#Agent Development#Data Sovereignty#Fireworks AI英文
Many research labs only consider inference efficiency after the fact. Step 3.7 Flash is a 198B spars...

Fireworks AI introduces Step 3.7 Flash: a 198B sparse MoE VLM designed for inference from the start, with a 196B language backbone and 1.8B vision encoder, achieving up to 400 token/s on real-world agent workloads.

入选理由:从设计阶段即优化推理效率,非事后补强。

FeaturedTweet#Step3.7 Flash#sparse MoE#VLM#198B#400 token/s英文
Routing and post-training open-source models won't only give you more accurate systems but also mean...

Routing and post-training open-source models significantly improve AI system accuracy, speed, and cost-efficiency. Harvey and Fireworks AI demonstrated that a hybrid architecture using GLM 5.1 as the primary worker with selective frontier model routing achieves superior quality and lower costs in legal tasks, proving this approach is a viable alternative to pure frontier models.

入选理由:Harvey实测显示混合法律Agent在质量和成本上均优于单一前沿模型。

FeaturedTweet#Model Routing#Post-training#Open Source LLM#Hybrid Agent#Legal AI英文
Fireworks AI(@FireworksAI_HQ) 图标

Fine-tuning on proprietary data is the most strategic AI advantage; prompts are easily copied, while models trained on private data are hard to replicate. OpenAI is restricting this path—companies must act now to retain SFT control.

入选理由:使用专有数据进行SFT微调可建立竞争壁垒,防止提示工程被快速复制。

FeaturedTweet#SFT#Fine-tuning#Fireworks AI#OpenAI英文

与「Fireworks AI」经常一起出现的 AI 术语。

💡 想追踪「Fireworks AI」的长期趋势?去 实体雷达 · Fireworks AI 查看详细分析和跨材料问答。

AI may generate inaccurate information. Please verify important content.