T
traeai
Sign in

模型

什么是 Claude Sonnet 4.5?

也叫:Claude

基准测试提升的模型版本

为什么现在值得关注?

最近变化

2026-09-24 · 长上下文会导致AI代理遗忘早期错误,影响决策质量

Claude Sonnet 4.5 被反复提及时,通常意味着它正在影响产品路线、开发者工作流或 AI 产业判断。这个页面把分散材料合并成一个可持续更新的观察入口。

📰 Claude Sonnet 4.5 最新动态

已收录 4 篇与「Claude Sonnet 4.5」相关的 AI 资讯和分析。

Databricks 图标

Databricks' Instructed-Retriever-1 cuts search latency by 3x and TTFT to ~2s via parallel test-time scaling without quality loss. The unified model handles query generation and reranking in parallel using multi-pivot groupwise reranking, achieving Pareto-optimal recall-precision tradeoffs for enterprise RAG systems.

入选理由:Instructed-Retriever-1使搜索延迟降低3倍以上,TTFT降至约2秒,无需重新配置。

FeaturedArticle#RAG#Test-Time Scaling#Instructed-Retriever-1#Databricks#Retrieval英文
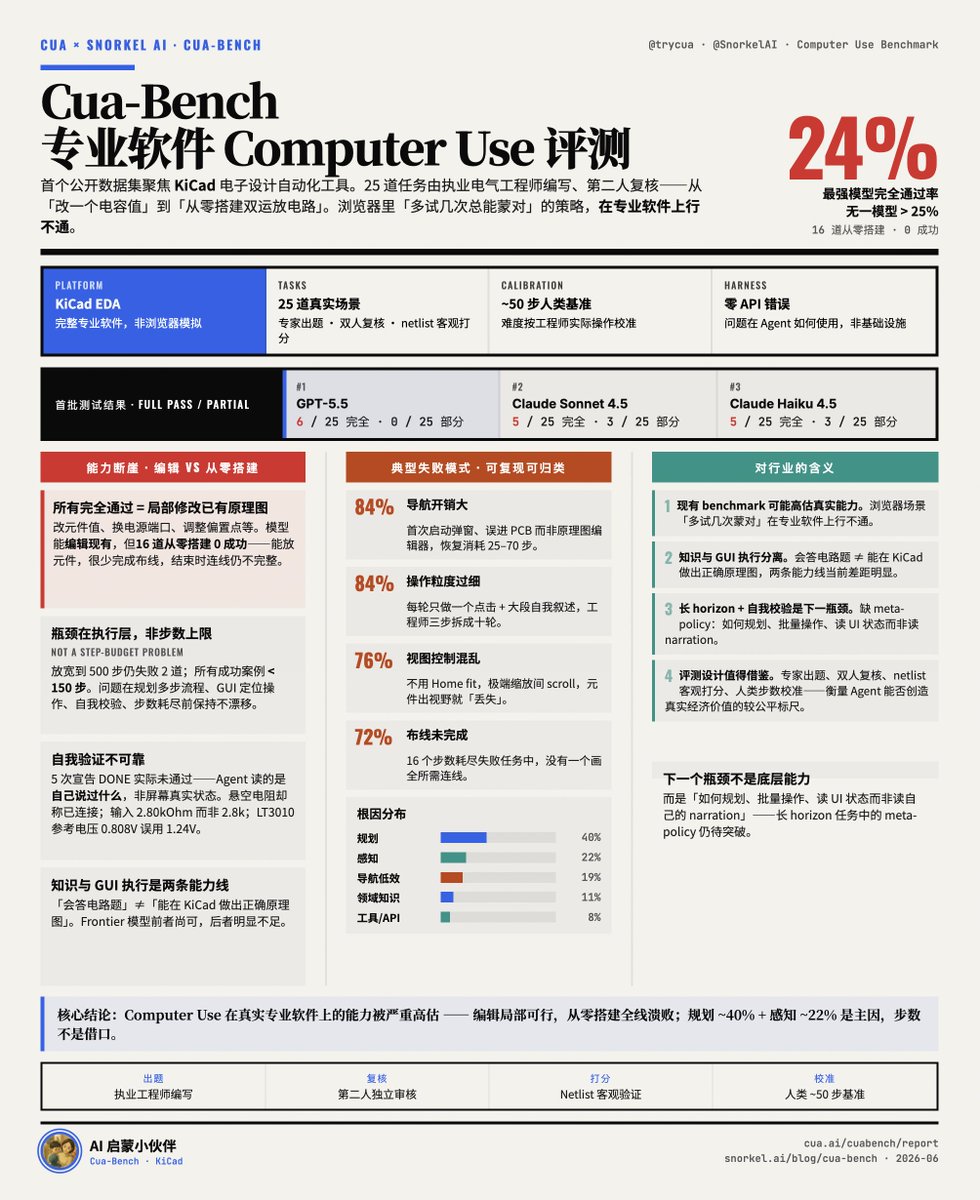
Cua 和 Snorkel AI 联合发布「Cua-Bench」:评测 Agent 在专业软件上的 Computer Use 能力 
@trycua @SnorkelAI 

Cua-Bench 首个...

Cua-Bench 是首个评测 Agent 在专业软件上执行任务能力的基准,测试显示当前模型在复杂 GUI 操作和任务规划上存在明显短板。

入选理由:当前最强模型 GPT-5.5 在 Cua-Bench 上仅完成 6/25 任务,完全通过率仅 24%。

FeaturedTweet#Cua-Bench#Agent#KiCad#评测基准#AI中英混合
The last six months in LLMs in five minutes

The last six months in LLMs in five minutes

Simon Willison's Weblog1128 字 (约 5 分钟)
85

November 2025 was a critical inflection point for LLM development, with model performance changing hands five times among three major vendors in six months, coding agents achieving qualitative leaps to daily usability, and emerging tools like Warelay beginning to appear.

入选理由:2025年11月三大厂商模型性能排名变化5次,Claude Opus 4.5最终胜出

FeaturedArticle#LLM#AI Programming#Model Evaluation#Anthropic#OpenAI英文

与「Claude Sonnet 4.5」经常一起出现的 AI 术语。

💡 想追踪「Claude Sonnet 4.5」的长期趋势?去 实体雷达 · Claude Sonnet 4.5 查看详细分析和跨材料问答。

AI may generate inaccurate information. Please verify important content.