T
traeai
Sign in

产品

什么是 Blackwell?

也叫:Blackwell architecture

NVIDIA最新一代GPU,用于Atlas模型训练

为什么现在值得关注?

最近变化

2026-09-17 · Atlas模型可从32张静态图像生成实时可交互的3D空间场景

Blackwell 被反复提及时,通常意味着它正在影响产品路线、开发者工作流或 AI 产业判断。这个页面把分散材料合并成一个可持续更新的观察入口。

📰 Blackwell 最新动态

已收录 10 篇与「Blackwell」相关的 AI 资讯和分析。

英伟达重新思考AI TCO:为何每Token成本才是唯一重要的指标

NVIDIA advocates for cost per token as the core economic metric for AI infrastructure, replacing traditional measures like compute cost or FLOPS per dollar, emphasizing full-stack optimization to reduce inference costs and enhance business value.

入选理由:每Token成本是衡量AI基础设施经济效益的核心指标,直接反映实际产出效率。

FeaturedArticle#NVIDIA#AI TCO#Inference Optimization#Cost Per Token中文
Together AI Blog 图标

To Infinity and Beyond: ThunderKittens Now on NVIDIA Vera Rubin NVL72!

Together AI Blog2254 字 (约 10 分钟)
85

Together AI在NVIDIA Vera Rubin NVL72上优化ThunderKittens,实现22 PFLOPS性能,接近cuBLAS。

入选理由:Vera Rubin NVL72的FP8算力达17.5 PFLOPS/GPU,是Blackwell的3.89倍

FeaturedArticle#NVIDIA Vera Rubin#GEMM优化#ThunderKittens#FP8#NVFP4英文
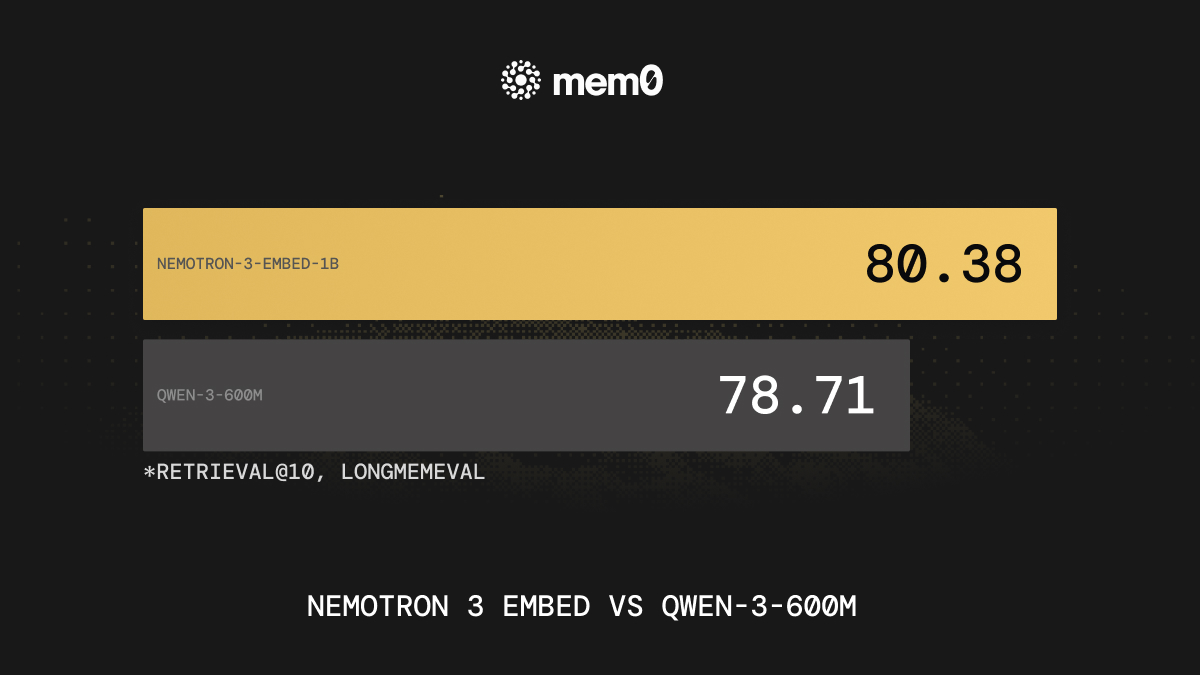
We evaluated Nemotron-3-Embed from @NVIDIAAI for our @mem0ai memory retrieval pipeline

Tested on lo...

mem0团队采用Nemotron-3-Embed模型后,长文本检索准确率提升1.67个百分点,其开放权重和NVFP4加速特性成为关键选择因素。

入选理由:Nemotron-3-Embed在longmemeval测试中实现80.38的检索准确率,超越qwen-3-600m模型

FeaturedTweet#NVIDIA#Nemotron-3-Embed#mem0ai#机器学习#嵌入模型中英混合
英伟达版「MacBook Pro」曝光:老黄自研了CPU!

NVIDIA’s ‘MacBook Pro’ Revealed: Huang Built Its Own CPU!

量子位1426 字 (约 6 分钟)
85

NVIDIA is set to launch the N1X chip-based AI-native laptop, targeting MacBook Pro users with ARM architecture + Blackwell GPU (6144 CUDA cores) and 128GB LPDDR5X shared memory — ideal for local AI inference and agent automation, but unsuitable for gaming due to bandwidth limits.

入选理由:N1X芯片含20核ARM CPU + Blackwell GPU(6144 CUDA单元),共享128GB LPDDR5X内存

FeaturedArticle#NVIDIA#N1X#ARM Architecture#AI PC#DGX Spark中文
This NVIDIA remains the strongest platform for large-model inference at scale. Prefill/decode disagg...

NVIDIA platform, through various optimization techniques, becomes the best platform for large-scale model inference, significantly reducing service costs and improving performance.

入选理由:NVIDIA 平台通过预填充/解码分离、Blackwell 原生量化、自定义内核和机架级 NVLink 提高了大规模模型推理的性能。

FeaturedTweet#NVIDIA#Large-scale Model Inference#Optimization Techniques中文
Open source 🤝 NVIDIA

Open source 🤝 NVIDIA

cohere(@cohere)56 字 (约 1 分钟)
75

Cohere与NVIDIA合作,推出优化的Command A+模型,专为NVIDIA Blackwell设计,利用NVIDIA CUDA-X库进行训练。这一合作展示了开源与专有技术的结合,为AI基础设施带来了新的可能性。

入选理由:Cohere与NVIDIA的合作展示了开源与专有技术的结合。

FeaturedTweet#Cohere#NVIDIA#AI#Command A+#Blackwell#CUDA-X中文
TokenSpeed is a brand new inference engine purpose built for speed-of-light agentic workloads.  

Re...

TokenSpeed is a new open-source LLM inference engine optimized for agentic workloads, featuring advanced KV caching, an efficient scheduler, and a modular kernel architecture with multi-silicon support.

入选理由:TokenSpeed 实现了媲美 TensorRT-LLM 的性能与接近 vLLM 的易用性。

FeaturedTweet#LLM Inference#NVIDIA#Open Source#KV Cache#Attention Mechanism中英混合
who's working on an NVFP4 version of Kimi-K3?

who's working on an NVFP4 version of Kimi-K3?

Julien Chaumond(@julien_c)177 字 (约 1 分钟)
60

关于Kimi-K3的NVFP4版本开发存在争议,部分开发者认为其意义有限,但Red Hat已推出相关优化方案。

入选理由:Eric认为NVFP4版本对数据中心外用户无实质价值

FeaturedTweet#Kimi-K3#NVFP4#Blackwell GPU#Red Hat AI中英混合

与「Blackwell」经常一起出现的 AI 术语。

💡 想追踪「Blackwell」的长期趋势?去 实体雷达 · Blackwell 查看详细分析和跨材料问答。

AI may generate inaccurate information. Please verify important content.