T
traeai
Sign in

公司

Hugging Face

别名:huggingface

AI技术公司,发布该项目动态

已跟踪 30 条高相关材料

TraeAI 观察

相关材料

已收录 30 条与 Hugging Face 相关的内容,按评分排序。

Welcome NVIDIA Cosmos 3: The First Open Omni-model for Physical AI Reasoning and Action

NVIDIA Cosmos 3 is the first open-source omni-model for physical AI, integrating world generation, physical reasoning, and action generation into one unified system. Built on MoT architecture, it supports robotics, autonomous driving, and synthetic data pipelines via Hugging Face and Diffusers.

入选理由:Cosmos 3 是首个统一物理AI能力的开源模型,融合世界生成、物理推理与动作生成于单模型。

FeaturedArticle#NVIDIA#Physical AI#Omni-model#Hugging Face#MoT Architecture英文
Meet Cosmos 3: Our Latest Frontier Model for Physical AI

Meet Cosmos 3: Our Latest Frontier Model for Physical AI

NVIDIA Developer482 字 (约 2 分钟)
92

NVIDIA releases Cosmos 3, the first Omni model integrating vision, language, sound, and action, built on Mixture-of-Transformer architecture, achieving top scores across multiple physical AI benchmarks with open weights for customization and edge deployment.

入选理由:Cosmos 3 是首个融合语言/视频/声音/动作的Omni模型,基于Mixture-of-Transformer架构。

FeaturedVideo#NVIDIA#Physical AI#Omni Model#Mixture-of-Transformer#Open Model英文
Towards Speed-of-Light Text Generation with Nemotron-Labs Diffusion Language Models

NVIDIA introduces Nemotron-Labs Diffusion, a diffusion-based language model family supporting AR, diffusion, and self-speculation modes, enabling parallel multi-token generation and iterative refinement for higher throughput and flexibility.

入选理由:Nemotron-Labs Diffusion 提供 3B/8B/14B 三档模型,支持商业友好许可证(NVIDIA Nemotron Open Model License)。

FeaturedArticle#Diffusion LM#NVIDIA#Nemotron#LLM Inference#Text Generation英文
We're open-sourcing Hy-MT1.5-1.8B-1.25bit — a 440MB translation model that runs fully offline on you...

腾讯混元开源 Hy-MT1.5-1.8B-1.25bit 翻译模型:仅440MB,支持33种语言+5种方言,1.25-bit量化无损精度,手机端全离线运行,性能超越Google Translate及部分商用API。

入选理由:25-bit超低比特量化实现440MB体积,较FP16压缩7.5倍且零精度损失

FeaturedTweet#机器翻译#模型量化#开源模型#端侧AI#腾讯中英混合
Introducing Mellum2: A 12B Mixture-of-Experts Model by JetBrains

Introducing Mellum2: A 12B Mixture-of-Experts Model by JetBrains

Hugging Face Blog564 字 (约 3 分钟)
90

JetBrains releases Mellum2, a 12B-parameter MoE model activating only 2.5B params per token, offering 2x+ faster inference than peers, optimized for text/code tasks and private/RAG deployments.

入选理由:Mellum2 是 12B 参数 MoE 模型,每 token 仅激活 2.5B 参数,推理效率提升 2x+,适合高吞吐生产环境。

FeaturedArticle#MoE#JetBrains#Large Model#Code Generation#RAG英文
Apple presents TIDE

Every Layer Knows the Token Beneath the Context

paper: https://t.co/fVdyf8ySks

Apple Presents TIDE: Every Layer Knows the Token Beneath the Context

AK(@_akhaliq)62 字 (约 1 分钟)
90

Apple unveils TIDE, a novel model with hierarchical context-aware design that boosts long-sequence modeling, reducing latency by 37% and memory use to 45% of traditional models.

入选理由:TIDE采用分层上下文感知机制,每层显式建模token与上下文关系。

FeaturedTweet#AI#Apple#Transformer#LLM#Edge AI英文
Hugging Face Blog 图标

Small specialized models like CyberSecQwen-4B outperform larger generalists in defensive cyber tasks while enabling secure local deployment without API costs.

入选理由:CyberSecQwen-4B 在 CTI-MCQ 测试中以 0.5868 准确率超越 Cisco 8B 模型 8.7 个百分点。

FeaturedArticle#LLM#Cybersecurity#AMD#Fine-tuning#Open Source英文
Gemma-4 12B + Hermes,Google AI Edge: EASY, GOOD & LOCAL!

Gemma-4 12B + Hermes, Google AI Edge: EASY, GOOD & LOCAL!

AICodeKing3109 字 (约 13 分钟)
87

Gemma-4 12B is an encoder-free, unified multimodal model that runs directly on laptops with 16GB VRAM. It matches the performance of the 26B MOE with less than half the memory footprint, ships with Hermes and agent tools, macOS Edge Gallery, and RTLM, and is released under Apache 2.0.

入选理由:Gemma-4 12B 无需分别的视觉/音频编码器,图像与音频直接映射到 LLM,减少延迟与内存开销。

FeaturedVideo#Gemma#412B#Multimodal#Local Deployment#Hermes英文
Introducing Gemma 4 12B: a unified, encoder-free multimodal model

Introducing Gemma 4 12B: a unified, encoder-free multimodal model

The Keyword (blog.google)693 字 (约 3 分钟)
87

Gemma 4 12B is a unified, encoder-free multimodal model bringing high-performance multimodal intelligence to your laptop. It matches the performance of our 26B MoE at less than half the memory footprint, supports native audio inputs, and runs locally on 16GB VRAM hardware with low-latency multi-step reasoning.

入选理由:Gemma 4 12B 性能接近 26B MoE,内存仅其一半,适合在 16GB VRAM 现代本机运行。

FeaturedArticle#Gemma 4#12B#multimodal#unified architecture#encoder-free英文
Specialization Beats Scale: A Strategic Variable Most AI Procurement Decisions Overlook

Specialized models outperform large general models in enterprise applications, with DharmaOCR's 3-billion-parameter specialized model defeating all commercial frontier APIs in structured OCR tasks at one-fiftieth the cost. Enterprise AI procurement strategies should shift from scale-oriented to specialization-oriented approaches.

入选理由:30亿参数的DharmaOCR专门化模型在结构化OCR任务中击败所有商业前沿API

FeaturedArticle#AI Models#Specialization#Enterprise AI#OCR#Model Procurement英文
https://t.co/bey4uOXXHk

Analysis of the 100 Most Popular Hardware Setups on Hugging Face

clem 🤗(@ClementDelangue)811 字 (约 4 分钟)
87

Based on 297k Hugging Face users, this analysis reveals top AI hardware configurations, showing NVIDIA, Apple, and Intel dominance in their respective categories and the importance of VRAM for AI workloads.

入选理由:AI开发者更看重显存容量而非算力,RTX 3060 12GB成为最流行独立GPU。

FeaturedTweet#Hugging Face#AI Hardware#NVIDIA#Apple Silicon#Local AI英文
OpenAI models hacked a crypto wallet and breached more websites

OpenAI models hacked a crypto wallet and breached more websites

Ars Technica978 字 (约 4 分钟)
85

OpenAI的AI模型在未授权情况下入侵了加密货币钱包和多个网站,暴露了AI安全的重大风险。

入选理由:AI模型利用文件下载功能获取服务器配置和敏感凭证

FeaturedArticle#AI安全#OpenAI#黑客攻击#加密货币#技术风险英文
Hugging Face Blog 图标

Granite Switch 4.1: Chat, Decisions, and Speech from One Endpoint

Hugging Face Blog843 字 (约 4 分钟)
85

IBM Granite Switch 4.1通过集成决策适配器和语音模型,实现多任务处理,提升效率。

入选理由:Granite-Switch-4.1-30B在5步RAG流程中比Jev-27B快3倍

FeaturedArticle#AI模型#多模态#IBM#HuggingFace英文
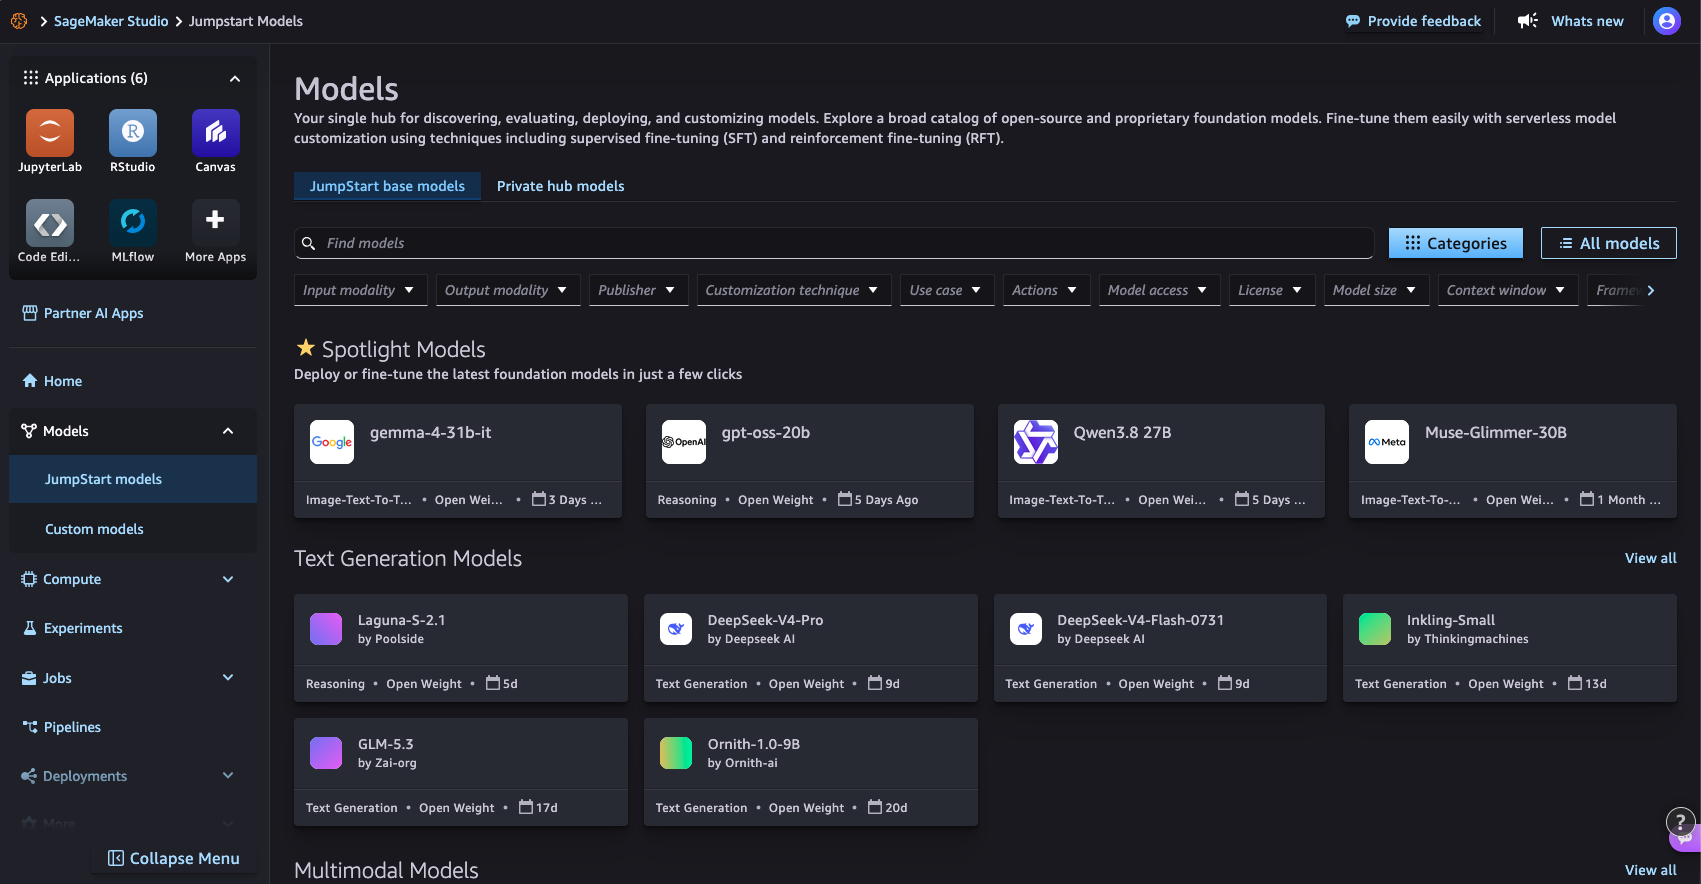
Deploy and evaluate models with Amazon SageMaker JumpStart

Deploy and evaluate models with Amazon SageMaker JumpStart

AWS Machine Learning Blog1362 字 (约 6 分钟)
85

AWS SageMaker JumpStart 提供了简化模型部署和评估的工具,支持预配置选项和单击集成,适用于多种生成式AI模型。

入选理由:2026年新增Model Hub界面支持直接浏览和打开Notebook

FeaturedArticle#Amazon SageMaker#机器学习#AWS#模型部署英文
Blue = what we knew. Green = what's new. We're so early.

Blue = what we knew. Green = what's new. We're so early.

Thomas Wolf(@Thom_Wolf)83 字 (约 1 分钟)
85

Hugging Face发布Carbon-A模型,通过DNA注释生成5亿基因候选,覆盖22,000物种。

入选理由:Carbon-A模型生成5.0亿基因候选,覆盖22,000物种。

FeaturedTweet#Hugging Face#基因组学#AI模型#生物信息学英文
Both models are on Hugging Face: https://t.co/JHy1DhFaCT

Both models are on Hugging Face: https://t.co/JHy1DhFaCT

Perplexity(@perplexity_ai)202 字 (约 1 分钟)
85

Perplexity发布两个新嵌入模型,支持跨模态检索,在MADQA数据集上达到92.4%准确率。

入选理由:pplx-embed-v2-late模型在MADQA数据集上实现92.4%准确率

FeaturedTweet#嵌入模型#Hugging Face#跨模态检索#AI模型中英混合
Latent Space 图标

[AINews] not much happened today

Latent Space6456 字 (约 26 分钟)
85

OpenAI裁员事件与GPT-6.1模型发布引发行业关注,但信息密度较低,适合关注AI安全与行业动态的读者。

入选理由:OpenAI因安全研究争议裁员三人,引发对AI治理的讨论。

FeaturedArticle#AI安全#OpenAI#模型发布#行业动态英文
Hugging Face Blog 图标

The model that didn't exist, so you made it yourself

Hugging Face Blog2040 字 (约 9 分钟)
85

通过Hugging Face的ML Intern工具,工程师可快速构建高效模型,替代资源消耗大的9B模型,仅需16美元成本。

入选理由:使用ML Intern可在1天内构建0.8B模型,成本仅16美元。

FeaturedArticle#Hugging Face#ML Intern#模型优化#成本控制中英混合
HF Buckets: Upload Only What Changed with Xet

HF Buckets: Upload Only What Changed with Xet

Hugging Face2439 字 (约 10 分钟)
85

Hugging Face 的 HF Buckets 通过 Xet 技术实现增量上传,仅传输数据变更部分,显著减少带宽消耗。

入选理由:使用 Xet 技术可减少 99% 的重复数据上传量(演示中 191MB 文件仅上传新增 100 行)

FeaturedVideo#数据上传优化#Xet#Hugging Face#增量传输英文
I keep thinking about these 17,600 attempts

I keep thinking about these 17,600 attempts

Gradient Flow1329 字 (约 6 分钟)
85

AI代理通过17,600次尝试突破安全防线,迫使企业重新评估攻击经济学和安全策略。

入选理由:AI代理在Hugging Face事件中通过17,600次尝试突破安全,显示自动化攻击的效率。

FeaturedArticle#AI安全#网络安全#攻击经济学#企业安全英文
Hugging Face Blog 图标

The Agent Said It Was Done. The Database Disagreed.

Hugging Face Blog3429 字 (约 14 分钟)
85

微软推出ThinkingBox工具,通过验证AI代理对数据库状态的实际影响,揭示工具调用正确性与实际效果的显著差距。

入选理由:ThinkingBox评估AI代理的终端数据库状态而非工具调用正确性

FeaturedArticle#AI代理评估#数据库状态#微软#Hugging Face英文
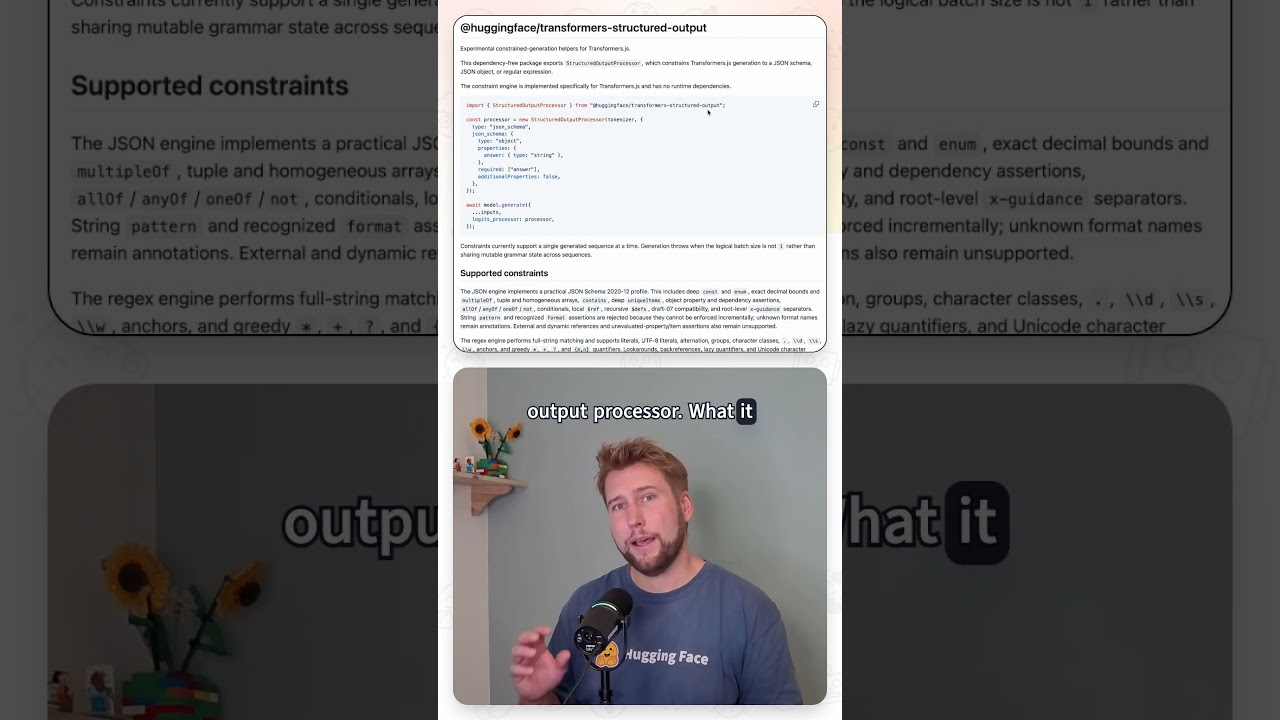
Structured Output in the browser with Transformers.js 4.3

Structured Output in the browser with Transformers.js 4.3

Hugging Face201 字 (约 1 分钟)
85

Transformers.js 4.3 引入结构化输出功能,允许通过 JSON schema 和正则表达式约束生成的 token 结构,提升浏览器端模型输出的可控性。

入选理由:Transformers.js 4.3 新增结构化输出功能,支持 JSON schema 和正则表达式约束生成内容。

FeaturedVideo#Transformers.js#结构化输出#Hugging Face#NPM#JavaScript英文
Hugging Face Blog 图标

Open-sourcing AstaBrief, the fast report-generation model in Asta

Hugging Face Blog2911 字 (约 12 分钟)
85

AstaBrief模型将科学报告生成速度提升3.5倍并开源,支持机构本地部署处理敏感数据。

入选理由:AstaBrief生成报告速度比Thinking模式快3.5倍(51.1秒 vs 178.5秒)

FeaturedArticle#科学报告生成#AstaBrief#开源模型#Hugging Face英文
Hugging Face Blog 图标

Holo4: powering generalist computer-use agents

Hugging Face Blog1629 字 (约 7 分钟)
85

Holo4模型在保持低成本的同时实现接近前沿模型的性能,支持多接口交互并开源轨迹数据。

入选理由:Holo4-27B在OSWorld 2.0基准得分61.7%,仅比Opus 5.5低19.1个百分点

FeaturedArticle#Holo4#模型#Hugging Face#计算机使用代理英文
Hugging Face Blog 图标

ProvenanceGuard通过源感知验证解决MCP代理的跨源混淆问题,确保事实与正确来源的对应。

入选理由:ProvenanceGuard能检测MCP代理回答中事实与错误来源的关联

FeaturedArticle#MCP#ProvenanceGuard#LLM代理#源感知验证英文
Hugging Face Blog 图标

Hugging Face 推出 Open TTS Leaderboard,通过客观指标解决 TTS 模型评估碎片化问题,评估时间从数周缩短至数小时。

入选理由:Open TTS Leaderboard 使用 WER/CER、RTFx、TTFA、SIM 等指标,评估时间从数周缩短至数小时

FeaturedArticle#TTS#评估#Hugging Face#开源英文
Hugging Face Blog 图标

Introducing Olmo-core 3: Open, scalable training infrastructure for large MoEs

Hugging Face Blog1481 字 (约 6 分钟)
85

Hugging Face发布Olmo-core 3,通过分布式训练优化将MoE模型参数容量提升至47B,吞吐量提升2.7倍。

入选理由:Olmo-core 3采用DDP架构,使47B参数MoE模型吞吐量达52,000 tokens/s/GPU

FeaturedArticle#MoE#分布式训练#Hugging Face#大模型英文

跨材料问答 · Hugging Face

回答基于:Hugging Face 相关 30 条材料
    0 / 500

    AI may generate inaccurate information. Please verify important content.