T
traeai
Sign in

公司

AnthropicAI

别名:Anthropic

开发Opus 5.5模型的公司

已跟踪 30 条高相关材料

TraeAI 观察

相关材料

已收录 30 条与 AnthropicAI 相关的内容,按评分排序。

🆕 @AnthropicAI's Claude Opus 4.8 is now generally available and rolling out in GitHub Copilot.

Ear...

AnthropicAI's Claude Opus 4.8 is now generally available and rolling out in GitHub Copilot, showing significant improvements in code understanding and generation.

入选理由:Claude Opus 4.8 demonstrates a clear step forward in code understanding and generation across a range of real-world coding tasks.

FeaturedTweet#AI#GitHub# Coding#AnthropicAIEnglish
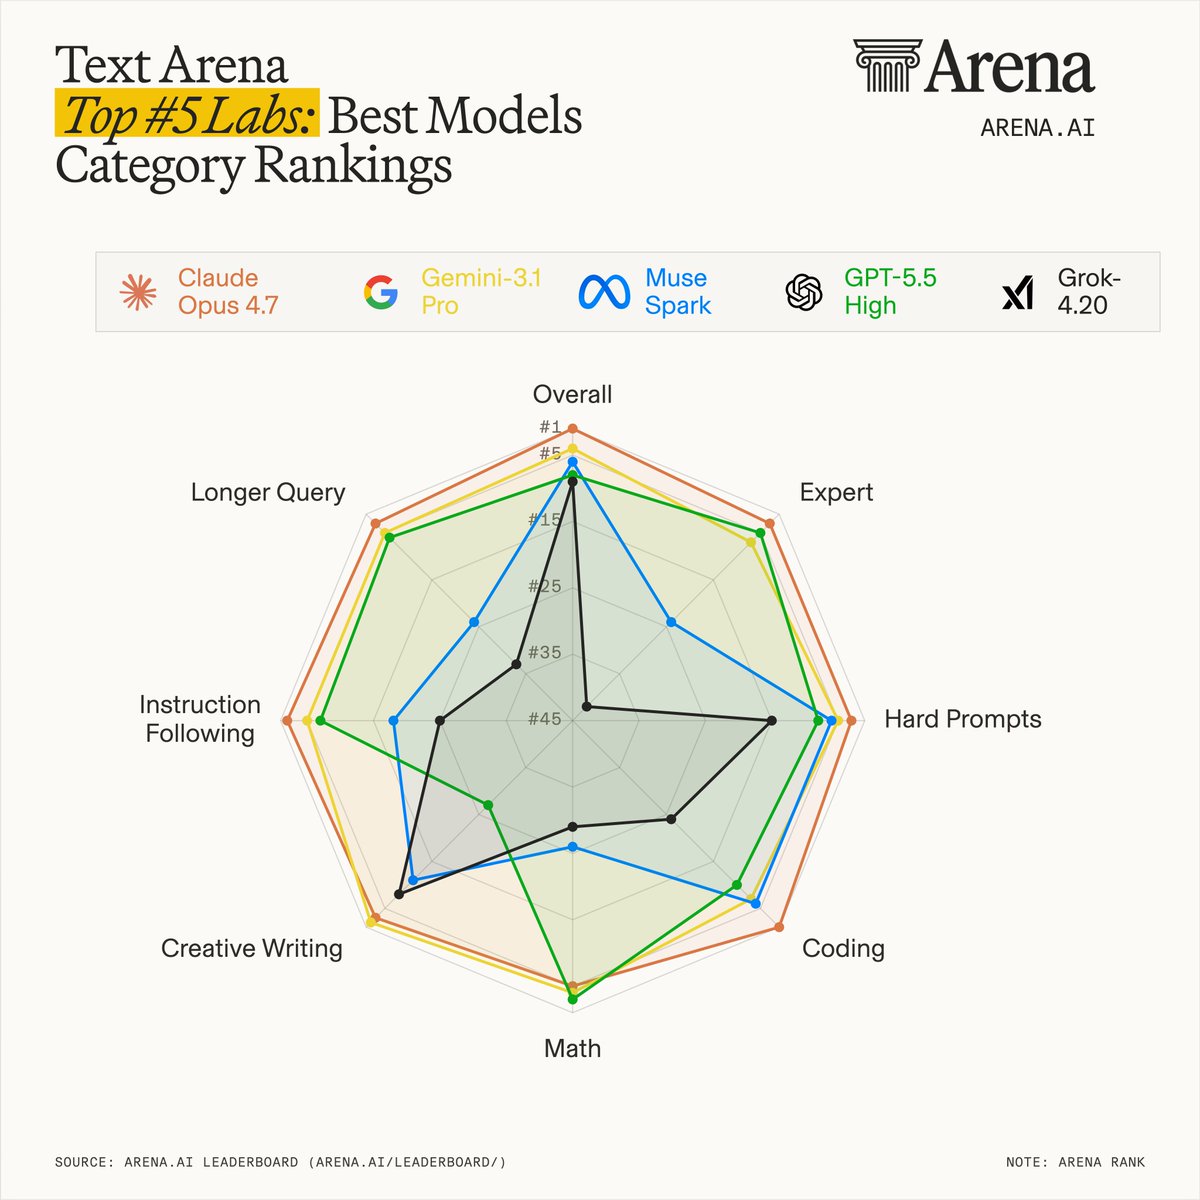
The top 5 labs in Text Arena rankings by category show that frontier models have distinct strengths ...

The article analyzes the top five labs in Text Arena rankings and their models, showcasing the distinct strengths and tradeoffs of frontier models in different fields. AnthropicAI's Claude Opus 4.7 is the most comprehensive, while Google DeepMind's Gemini 3.1 Pro excels in creative writing.

入选理由:AnthropicAI的Claude Opus 4.7在几乎所有主要类别中都表现出色,是最具统治力的模型。

FeaturedTweet#machine learning#natural language processing#model evaluation#text generation英文
I'm very excited about this extension to the celebrated Terminal-Bench to science.

If you're a scie...

Thomas Wolf is excited about the extension of Terminal-Bench to scientific fields, known as Terminal-Bench Science. This benchmark evaluates AI models' ability to control tools via the command line to achieve scientific goals. It's open for contributions of real scientific workflows until August 2026, aiming to improve AI models' assistance in research work.

入选理由:Terminal-Bench Science evaluates AI models' performance in handling scientific workflows through command-line tools.

FeaturedTweet#AI#Science#Terminal-Bench#Benchmarking#Command Line英文
@AnthropicAI @trq212 great notes! https://t.co/JcB1PBmjN3

@AnthropicAI @trq212 great notes! https://t.co/JcB1PBmjN3

Latent.Space(@latentspacepod)86 字 (约 1 分钟)
65

提示工程成功依赖心智模型匹配与领域词汇掌握,需准确判断模型的一次性处理能力。

入选理由:心智模型匹配是提示工程成功的关键因素之一

FeaturedTweet#提示工程#AI#AnthropicAI中英混合
Kimi K3 在「Frontend Web App」竞技中来到榜首了!

感觉这次 Kimi K3 在前端设计方面确实上来了,和 Fable 5 之间到底谁更好,我还没有答案,不过看 @Design...

Kimi K3 在前端设计竞技中超越 Fable 5 和 Claude 全系模型,成为榜首。GPT-5.6 Sol 前端能力仍不足,跌出前十。

入选理由:Kimi K3 在 Design Arena 前端设计榜单中以 Elo 1326 排名第一

FeaturedTweet#Kimi K3#前端设计#AI模型#Design Arena中英混合
See the full Pareto frontier at: https://t.co/c6ofRzGq7E

See the full Pareto frontier at: https://t.co/c6ofRzGq7E

lmarena.ai(@lmarena_ai)115 字 (约 1 分钟)
60

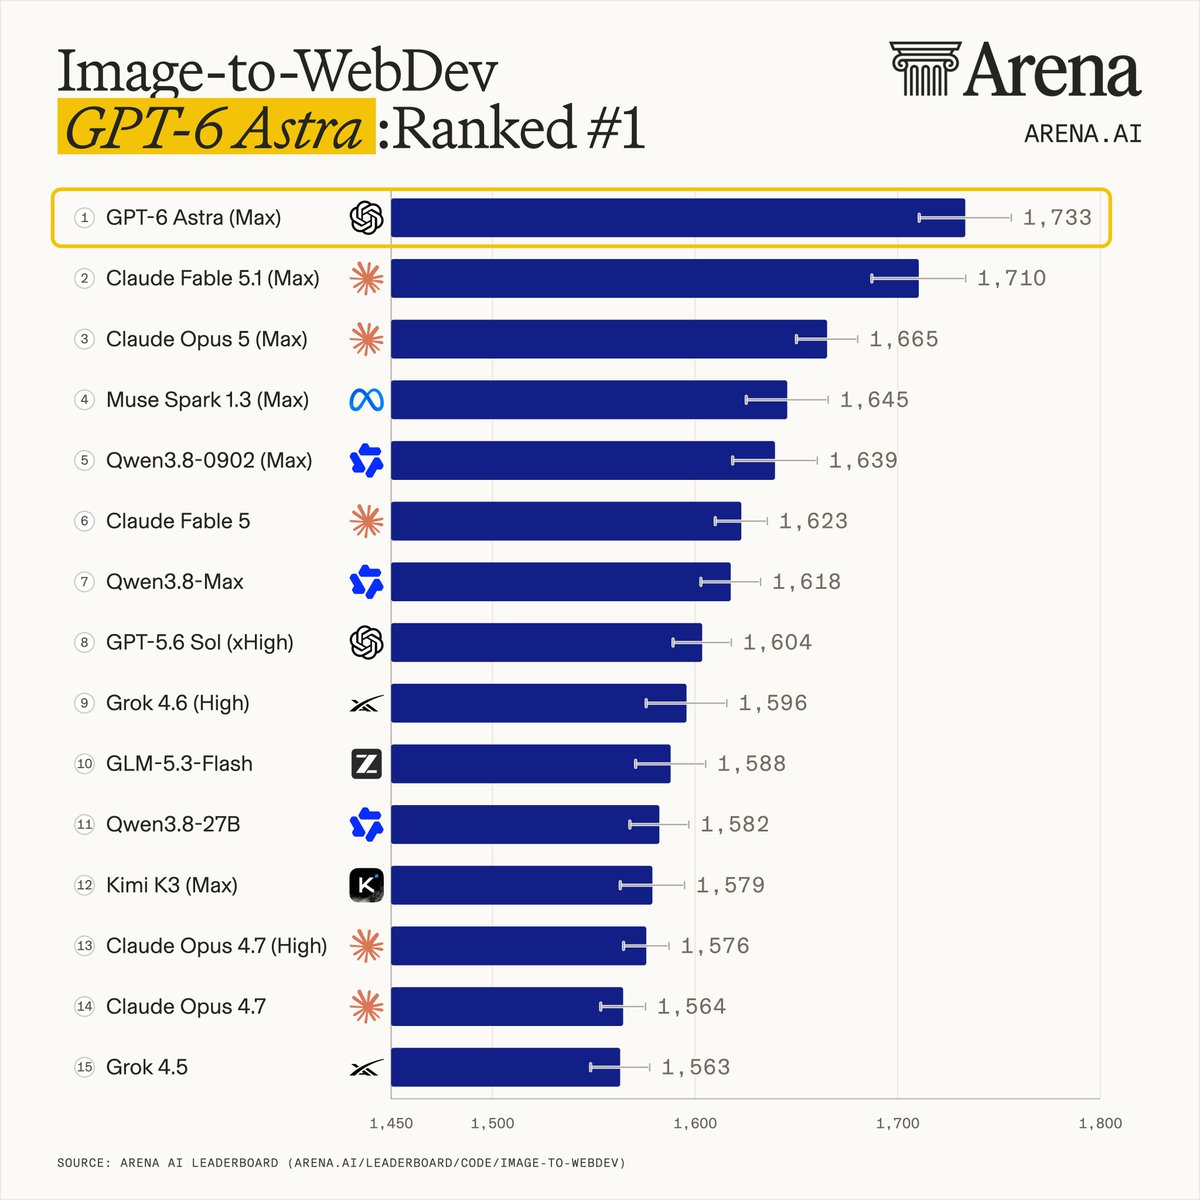
Anthropic的Claude Opus 5.5和Sonnet 5.5在Image-to-WebDev任务中分别获得1749和1740分,均位于Pareto前沿。

入选理由:Claude Opus 5.5在Image-to-WebDev任务中得分1749,排名第一

FeaturedTweet#AnthropicAI#Claude#Image-to-WebDev#Pareto frontier#Arena.ai英文
I'm seeing lots of people "one shot" games again with the new Opus 5 model by @AnthropicAI

So I wanted to try it again too

This is New Amsterdam in 1660 (current day New York City) based on real historical maps, it mostly one-shotted it doing its own research

Not perfect at all yet, and lots of issues to fix:
- weird stuff in the canal
- some house edges are open
- windmill doesn't look very Dutch

But nice!

AnthropicAI的Opus 5模型在生成历史场景时存在细节问题,但展示了AI在游戏开发中的潜力。

入选理由:Opus 5模型生成的1660年纽约市场景存在运河异常、建筑边缘缺失等问题

FeaturedTweet#AnthropicAI#AI游戏开发#历史场景生成#Seedance中英混合
Opus wrote us a VM and then Mythos verified it

Opus wrote us a VM and then Mythos verified it

Guillermo Rauch(@rauchg)100 字 (约 1 分钟)
60

文章讨论了 Mythos 验证 VM 的过程,但信息密度较低,缺乏深度技术细节。

入选理由:Mythos 用于验证 Opus 编写的 VM。

FeaturedTweet#VM#验证#AnthropicAI英文

跨材料问答 · AnthropicAI

回答基于:AnthropicAI 相关 30 条材料
    0 / 500

    AI may generate inaccurate information. Please verify important content.