Bringing Visual Graph Debugging to Custom Edge Compilers with Model Explorer
Google Model Explorer工具通过可视化调试解决边缘设备模型部署难题,支持Arm自定义编译器IR验证与性能分析。
入选理由:Model Explorer支持VGF/TOSA/PTE格式,可检测ExecuTorch后端引入的TRANSPOSE操作符问题
公司
也叫:AI Edge
Google边缘计算解决方案部门
最近变化
2026-10-20 · Model Explorer支持VGF/TOSA/PTE格式,可检测ExecuTorch后端引入的TRANSPOSE操作符问题
Google AI Edge 被反复提及时,通常意味着它正在影响产品路线、开发者工作流或 AI 产业判断。这个页面把分散材料合并成一个可持续更新的观察入口。
已收录 5 篇与「Google AI Edge」相关的 AI 资讯和分析。
Google Model Explorer工具通过可视化调试解决边缘设备模型部署难题,支持Arm自定义编译器IR验证与性能分析。
入选理由:Model Explorer支持VGF/TOSA/PTE格式,可检测ExecuTorch后端引入的TRANSPOSE操作符问题
Google通过LiteRT和Gemma模型实现Raspberry Pi边缘AI突破,实现实时本地推理与低功耗部署。
入选理由:LiteRT通过CPU/GPU优化使Raspberry Pi性能提升300%
The article introduces the collaboration between Arm and Google to optimize edge AI inference through the SME2 architecture and Google AI Edge toolchain.
入选理由:Arm SME2使CPU成为高性能AI加速器,推理速度提升5倍
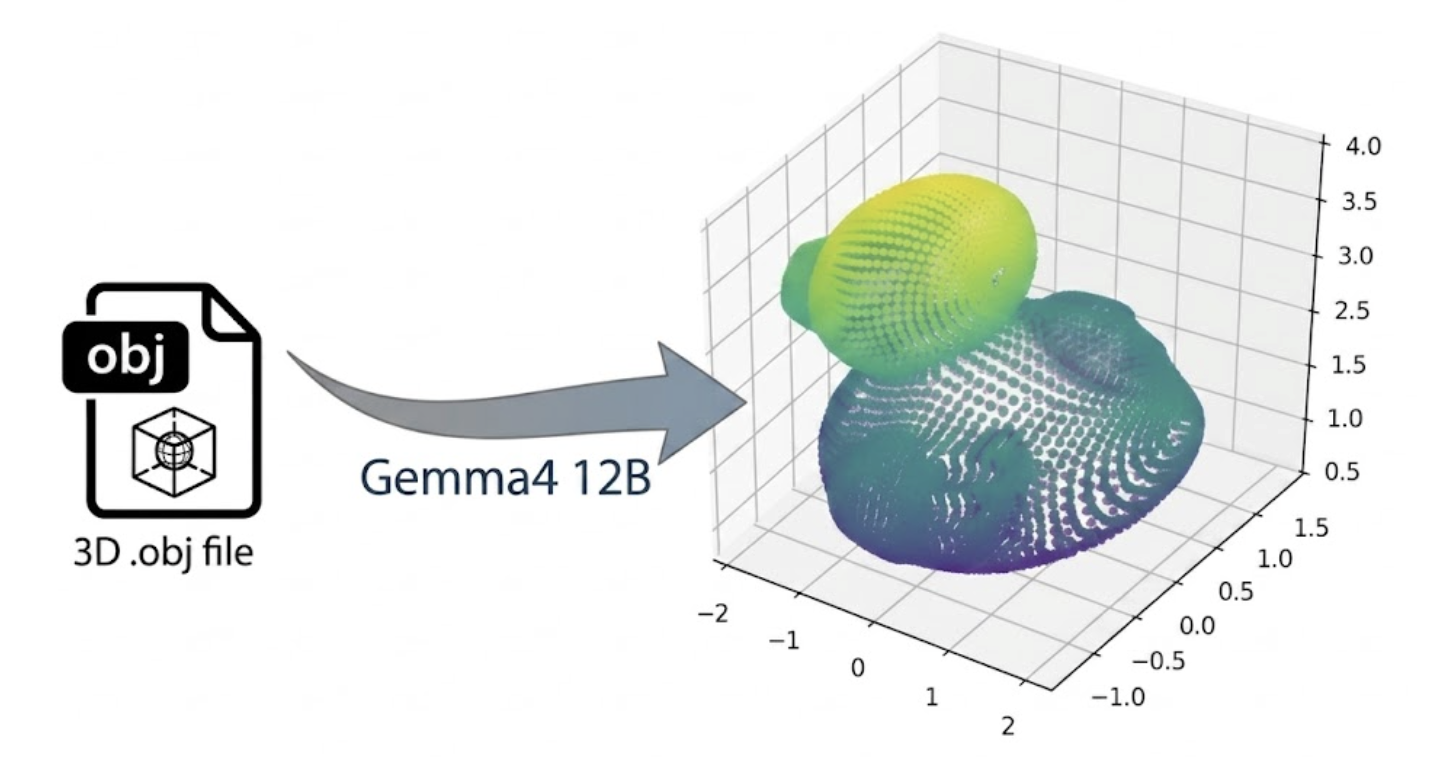
Gemma 4 12B combined with Google AI Edge enables local execution on laptops, supporting code generation, voice editing, and OpenAI-compatible APIs on macOS. This setup facilitates on-device agentic workflows with a 60%+ quality boost in instruction following while ensuring offline privacy.
入选理由:Gemma 4 12B通过LiteRT-LM在消费级笔记本运行,支持本地Agent与多模态任务。
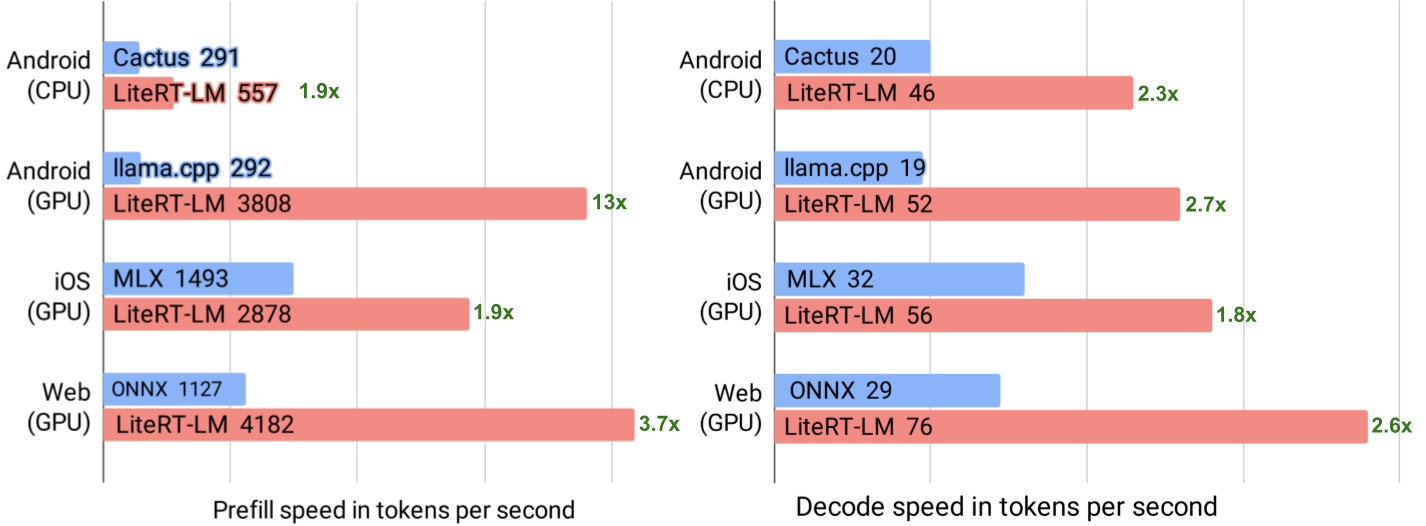
Google AI Edge introduces LiteRT-LM, an optimized inference engine for deploying Gemma 4 models on edge devices, supporting Android, iOS, and web platforms with GPU inference reaching 76 tokens/sec and Multi-Token Prediction delivering up to 2.2x speedup.
入选理由:LiteRT-LM 在 Android GPU (OpenCL) 上实现 52 tokens/sec 解码速度,iOS (Metal) 达 56 tokens/sec,WebGPU 在 MacBook Pro 上可达 76 tokens/sec
与「Google AI Edge」经常一起出现的 AI 术语。
💡 想追踪「Google AI Edge」的长期趋势?去 实体雷达 · Google AI Edge 查看详细分析和跨材料问答。