Quoting Anthropic Frontier Red Team
Simon Willison's Weblog233 字 (约 1 分钟)
85
GLM-5.3和Claude Mythos Preview在二进制利用测试中展现突破性能力,而早期模型完全失效。
入选理由:GLM-5.3在4%的测试中实现控制流劫持,Claude Mythos Preview达到6%
FeaturedArticle#AI安全#LLM#模型对比#Anthropic#GLM英文
模型
也叫:claude-opus-4.6
在二进制利用测试中未成功的早期模型版本。
最近变化
2026-09-29 · GLM-5.3在4%的测试中实现控制流劫持,Claude Mythos Preview达到6%
Claude Opus 4.6 被反复提及时,通常意味着它正在影响产品路线、开发者工作流或 AI 产业判断。这个页面把分散材料合并成一个可持续更新的观察入口。
已收录 9 篇与「Claude Opus 4.6」相关的 AI 资讯和分析。
GLM-5.3和Claude Mythos Preview在二进制利用测试中展现突破性能力,而早期模型完全失效。
入选理由:GLM-5.3在4%的测试中实现控制流劫持,Claude Mythos Preview达到6%
Qwen3.8-Flash模型可在75GB RAM上本地运行,性能超越Claude-Opus-4.6。
入选理由:125B MoE模型通过GGUF格式实现75GB RAM本地运行
Step 3.7 Flash by Yujue Star is a new-generation Flash model for production-grade AI Agents, featuring native multimodal understanding, high throughput with low latency, and enhanced web search. It achieves 97% of Claude Opus 4.6's coding performance at only 1/9 the cost per task, ideal for high-frequency, complex real-world workflows.
入选理由:Step 3.7 Flash 采用稀疏 MoE 架构,激活参数仅 11B,最高生成速度达 400 Tokens/s,支持 40 个 Agent 并行运行。
国产Agent模型SkyClaw-v1.0及其轻量版SkyClaw-v1.0-lite性能达到全球第一梯队,价格仅为主流模型的一半,且支持主流Agent框架和OpenAI接口。
入选理由:SkyClaw-v1.0性能媲美Claude Opus 4.6,价格仅为0.5元/百万tokens输入,4元/百万tokens输出。
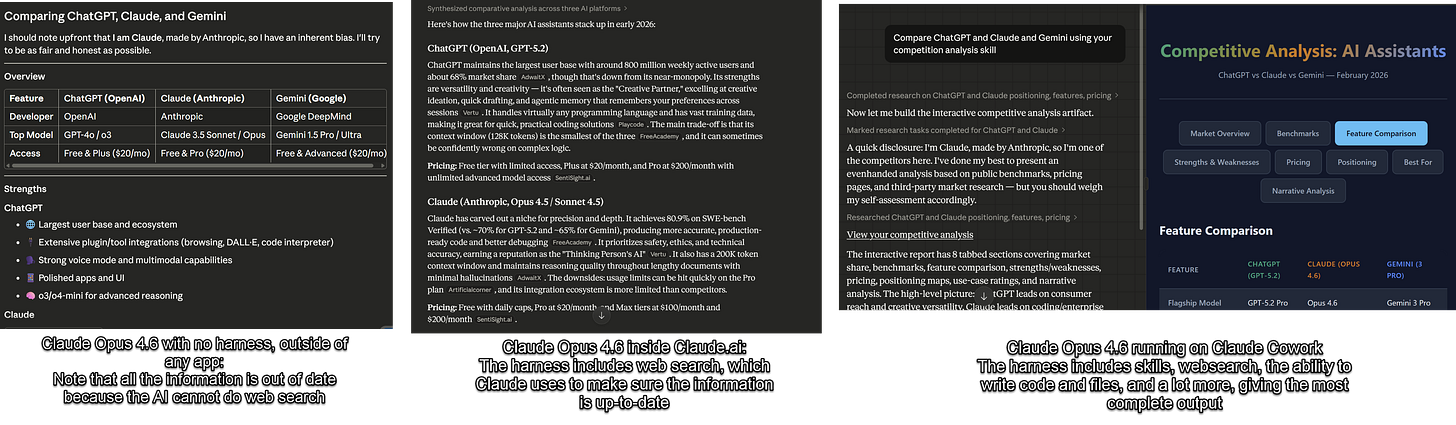
文章探讨了在代理时代如何选择合适的AI工具,强调了模型、应用和Harness的重要性。
入选理由:选择AI需考虑模型、应用和Harness。
GPT-5.5 excels in engineering scenarios with higher cost-effectiveness than Claude Opus 4.6, showing significant improvements in terminal reasoning, long-context handling, and hallucination reduction.
入选理由:GPT-5.5 终端基准测试得分 82.7%,较 GPT-5.4 提升 7.6 个百分点。
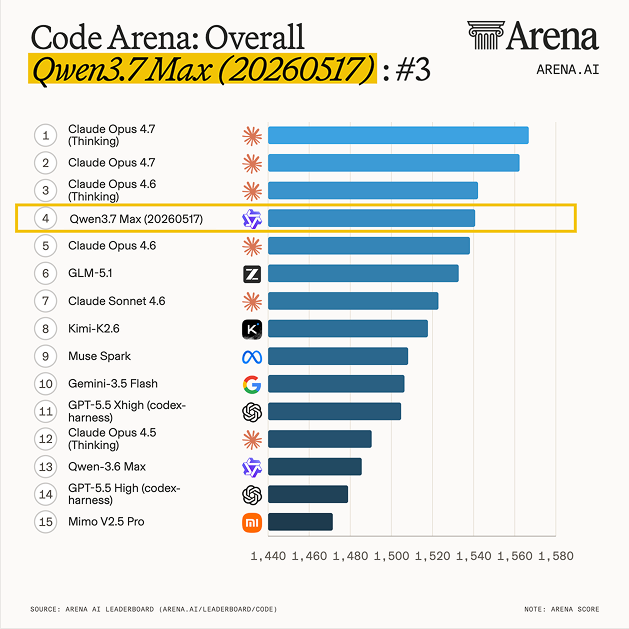
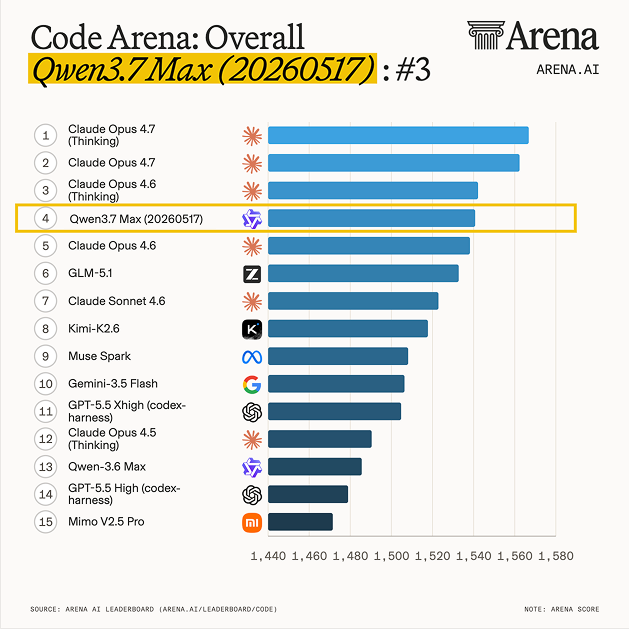
Qwen 3.7 Max ranks fourth in Arena Coding Agent, surpassing GLM-5.1 and matching Claude Opus 4.6 in agentic web development tasks.
入选理由:Qwen 3.7 Max 排名第四
Qwen3.7 Max ranks 4th in Code Arena: Frontend, surpassing GLM-5.1 and matching Claude Opus 4.6 in agent-based web development tasks.
入选理由:Qwen3.7 Max 排名第 4
该推文缺乏技术深度和系统性分析,仅包含个人模型使用偏好,未提供可验证的工程实践或技术原理。
入选理由:个人使用体验替代技术分析,缺乏数据支撑
与「Claude Opus 4.6」经常一起出现的 AI 术语。
💡 想追踪「Claude Opus 4.6」的长期趋势?去 实体雷达 · Claude Opus 4.6 查看详细分析和跨材料问答。