T
traeai
Sign in

产品

LlamaParse

别名:llama...

文档解析模型开发平台,使用ParseBench进行内部能力验证

已跟踪 30 条高相关材料

TraeAI 观察

相关材料

已收录 30 条与 LlamaParse 相关的内容,按评分排序。

A lot of real-world documents embed extremely dense charts that require humans to not only "perceive...

ExtractBench Pro基准测试揭示当前AI在处理复杂文档时的显著短板,LlamaParse工具提供针对性解决方案。

入选理由:ExtractBench Pro是首个针对密集图表+文档推理的基准测试,暴露模型在复杂场景下的性能缺陷

FeaturedTweet#文档提取#AI基准测试#LlamaParse#ExtractBench Pro中英混合
ExtractBench is now live on @Kaggle.

It tests schema-guided document extraction on the documents mo...

ExtractBench 是 LlamaIndex 推出的文档提取基准测试,覆盖 370 个企业文档和 67 种类型,用于评估长列表、手写等复杂场景下的提取效果。

入选理由:ExtractBench 包含 370 个企业文档,覆盖 8 个业务领域和 67 种文档类型。

FeaturedTweet#LlamaIndex#文档提取#Kaggle#基准测试英文
Introducing the Parse Gateway 

There's been an explosion of interest in model routing - you don't a...

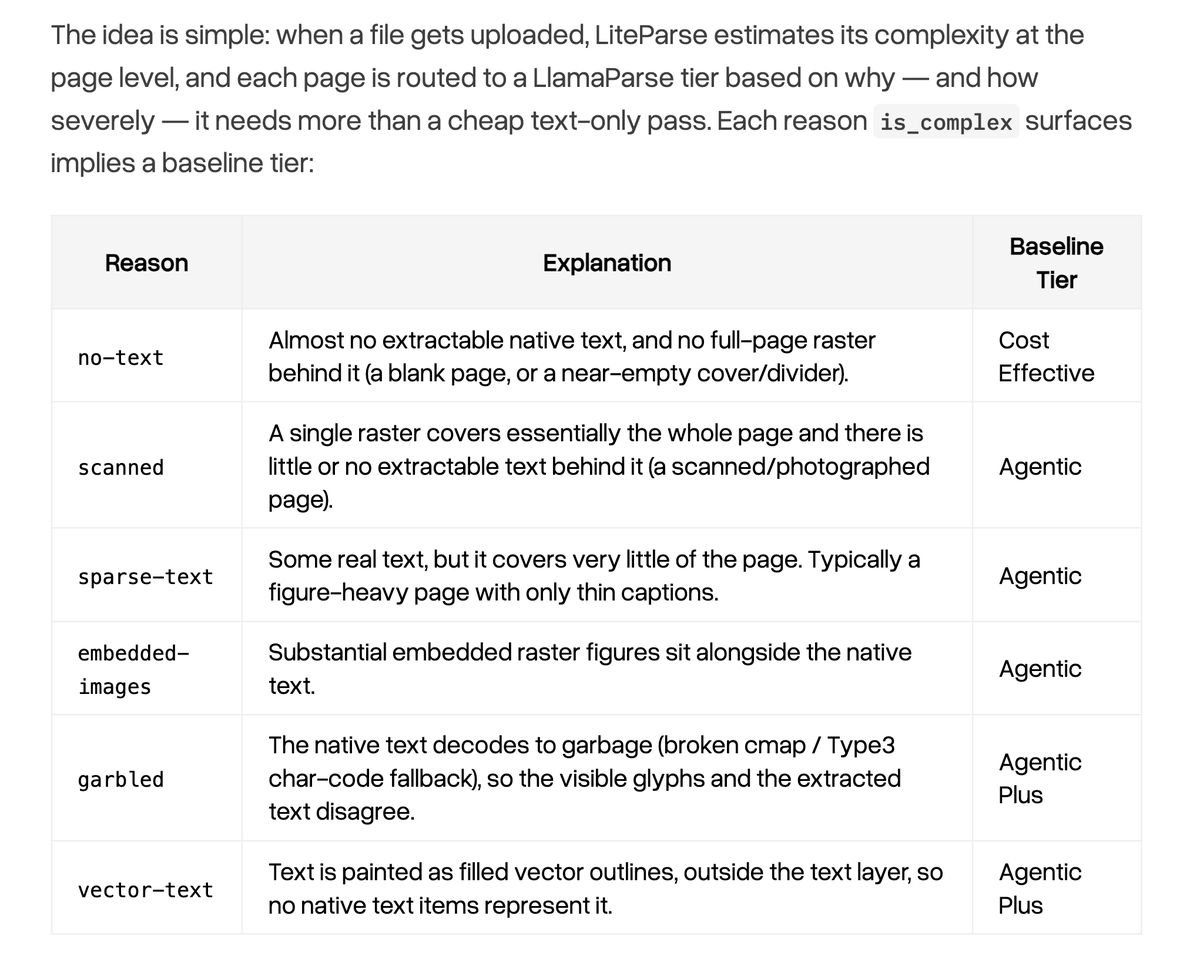
Parse Gateway通过动态路由策略优化文档解析,根据页面复杂度选择不同解析模式,提升效率与成本控制。

入选理由:Parse Gateway根据页面复杂度动态选择cost-effective/agentic/agentic plus三种解析模式

FeaturedTweet#文档解析#模型路由#LlamaParse#开源工具中英混合
Not every page in your PDF needs the same treatment.

A scanned cover, a dense table, a clean text p...

LlamaIndex推出Parse Gateway,通过动态路由解析层级优化PDF处理成本与准确性,复杂页面按需调用高级解析器。

入选理由:Parse Gateway使用LiteParse的is_complex功能评估页面复杂度,实现动态路由

FeaturedTweet#PDF解析#LlamaIndex#LiteParse#Parse Gateway#MCP服务器中英混合
I'm glad people still understand the importance of building high-quality retrieval systems in 2026, ...

构建高质量检索系统仍是2026年生产环境的核心挑战,需重点优化分块策略、混合搜索参数和权限管理,而非依赖革命性技术。

入选理由:生产级检索需精细调优分块策略与实时同步机制(如Slack线程拼接)

FeaturedTweet#检索系统#生产环境#工程实践#混合搜索中英混合
We've created a comprehensive Retrieval Harness for modern agentic retrieval in 2026.

The harness p...

LlamaIndex推出2026年代理检索工具包,提供知识库自动索引和文件系统级检索功能,适用于法律和金融科技领域复杂任务处理。

入选理由:Retrieval Harness支持语义搜索、正则表达式匹配等文件系统操作级功能

FeaturedTweet#LlamaIndex#agentic retrieval#知识库管理#AI工具包英文
Fully solving document parsing includes covering every point on the Pareto curve of accuracy, cost, ...

文档解析需兼顾准确率、成本和延迟,LlamaParse和LiteParse分别针对不同场景优化,适用于金融、保险等高要求领域及大规模处理需求。

入选理由:高精度解析要求99%+准确率,适用于金融和保险等监管行业

FeaturedTweet#文档解析#AI#LlamaParse#ParseBench中英混合
Last week I gave a talk at AI Dev ’26 by @DeepLearningAI on “AI can’t read PDFs, how do we fix it” ....

AI Can’t Read PDFs, How Do We Fix It

Jerry Liu(@jerryjliu0)444 字 (约 2 分钟)
78

PDF parsing remains a critical bottleneck for AI automation of knowledge work; current OCR and vision-language models perform poorly on complex layouts and tables, requiring specialized tooling to improve data extraction quality.

入选理由:当前主流OCR和VLM对PDF中的复杂排版与表格支持差,导致AI代理输入质量低下。

FeaturedTweet#PDF Parsing#AI Agents#LlamaParse#Document Understanding#OCR英文
Parsing PDFs is hard

This past week I gave a few talks (at both AI Dev '26 by @DeepLearningAI  and ...

PDF解析仍属开放难题,因其本质是面向打印/显示的格式,缺乏语义结构与文本顺序保证,而AI Agent对高质量OCR和结构化提取的需求正急剧提升。

入选理由:PDF设计初衷非为机器可读,文本与表格以无序字符/线条堆叠方式存储

FeaturedTweet#PDF#OCR#AI Agent#VLM#LlamaIndex中文
Building a document processing pipeline at scale is hard, and is one of the reasons that it's hard t...

构建大规模文档处理流水线极具挑战,仅靠LLM API DIY OCR方案易受速率限制、解析失败和超时重试等问题影响,需专业编排层保障弹性与可扩展性。

入选理由:文档处理规模化的核心难点不在OCR模型本身,而在工程化编排:需统一处理限流、异常、幂等重试。

FeaturedTweet#LLM#OCR#document-processing#LlamaParse#Render中文
Parsing documents with AI agents just got a lot more seamless🚀

We've rebuilt the LlamaParse MCP se...

LlamaIndex 重构 LlamaParse MCP 服务,支持文档解析、分类、分段与多方式上传,解决 OAuth 集成、文件上传缺失、可观测性等生产级挑战。

入选理由:LlamaParse 现以 MCP 协议标准服务形式提供,兼容任意 MCP 客户端

FeaturedTweet#LlamaIndex#MCP#AI Agents#Document Parsing#LLM Infrastructure中文
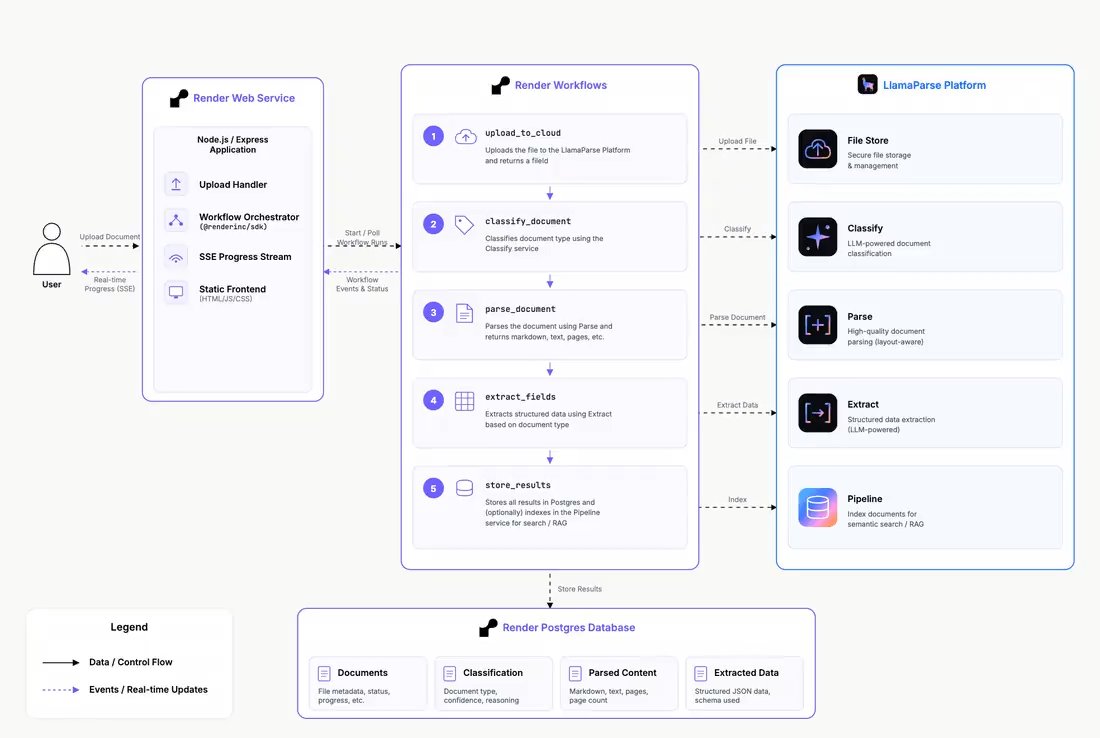
Building scalable, distributed document processing pipelines isn’t easy.
That’s why we teamed up wit...

LlamaIndex 与 Render 合作构建可扩展的分布式文档处理流水线,整合 LlamaParse 文档解析能力与 Render Workflows 分布式任务调度能力。

入选理由:LlamaParse 提供端到端文档解析、分类、信息抽取与检索能力

FeaturedTweet#LlamaIndex#LlamaParse#Render#document-processing#LLM-infrastructure中文

跨材料问答 · LlamaParse

回答基于:LlamaParse 相关 30 条材料
    0 / 500

    AI may generate inaccurate information. Please verify important content.