T
traeai
Sign in

模型

Gemma 4

别名:Gemma4

与新模型配合使用的AI模型,支持私有设备RAG。

已跟踪 30 条高相关材料

TraeAI 观察

相关材料

已收录 30 条与 Gemma 4 相关的内容,按评分排序。

Google AI Studio 3.0 (Fully Free): This is ACTUALLY AWESOME!

Google AI Studio 3.0 (Fully Free): This is ACTUALLY AWESOME!

AICodeKing979 字 (约 4 分钟)
87

Google AI Studio 3.0 launches fully free with integrated Gemma 4 model and multimodal capabilities, enabling real-time inference, custom model deployment, and API access, significantly lowering the barrier for developers.

入选理由:Gemma 4 模型在 Google AI Studio 3.0 中完全免费,支持 128K 上下文长度。

FeaturedVideo#Google AI Studio#Gemma 4#AI development tool#free AI platform中文
Machine Learning Mastery 图标

Comparing Local Tool Calling: Gemma 4 vs. Llama 3 vs. Mistral

Machine Learning Mastery2251 字 (约 10 分钟)
85

Gemma 4、Llama 3和Mistral在本地工具调用实现上各有差异,分别适用于不同硬件约束和部署场景。

入选理由:Gemma 4通过架构升级提升本地工具调用效率,但对硬件要求较高。

FeaturedArticle#本地工具调用#模型比较#Gemma 4#Llama 3#Mistral英文
DeepMind Just Changed How AI Sees The World

DeepMind Just Changed How AI Sees The World

Two Minute Papers1047 字 (约 5 分钟)
85

DeepMind的Gemma 4模型通过创新架构实现高效视觉处理,体积仅为大型模型的1%却具备多模态能力。

入选理由:Gemma 4体积仅为大型模型的1%,却具备视觉和多模态能力

FeaturedVideo#DeepMind#AI模型#视觉处理#多模态#Gemma 4英文
Introducing Ornith 1.0 - Agentic Coding LLMs

Introducing Ornith 1.0 - Agentic Coding LLMs

Sam Witteveen4075 字 (约 17 分钟)
85

Ornith 1.0 是 Deep Reinforce 推出的自构建 LLM 系列,支持动态生成代码框架,适用于代理式编程。

入选理由:Ornith 1.0 支持模型自动生成代码框架,提升编程效率。

FeaturedVideo#LLM#代理式编程#Deep Reinforce#Ornith英文
Quantization: The Size vs Quality Trade-Off

Quantization: The Size vs Quality Trade-Off

Hugging Face409 字 (约 2 分钟)
85

量化技术通过减少模型参数的位数,显著降低模型大小和推理速度,但会牺牲部分精度。

入选理由:Q8量化使模型大小减少约4倍,Q4量化减少约8倍。

FeaturedVideo#量化#AI模型#Hugging Face#模型压缩英文
EP219: 12 Open-source LLMs

EP219: 12 Open-source LLMs

ByteByteGo Newsletter1046 字 (约 5 分钟)
85

2026 年值得关注的 12 个开源大语言模型,涵盖性能、成本、应用场景等关键信息。

入选理由:DeepSeek V4 以 MIT 许可证提供,支持百万级上下文窗口,性能接近前沿模型。

FeaturedArticle#LLM#开源#AI#模型英文
SuperTechFans 图标

2026 06 17 HackerNews

SuperTechFans9952 字 (约 40 分钟)
85

LinkedIn 招聘诈骗利用 npm install 触发后门,本地大语言模型性能提升显著,Fabrice Bellard 被赞为更全面的程序员。

入选理由:LinkedIn 招聘诈骗通过 npm install 触发后门,需警惕虚假邀请。

FeaturedArticle#安全#AI#编程#HackerNews中文
KDnuggets 图标

Local Agentic Programming on the Cheap: Claude Code + Ollama + Gemma4

KDnuggets4352 字 (约 18 分钟)
85

Gemma 4 26B MoE 在多代理编程任务中表现优异,结合 Ollama 和 Claude Code 可构建本地高效代理系统。

入选理由:Gemma 4 26B MoE 在 τ2-bench 上得分 79%,显著优于 Gemma 3 27B 的 6.6%。

FeaturedArticle#AI#编程#Ollama#Gemma#Claude Code英文
Google Developers Blog 图标

DiffusionGemma: The Developer Guide

Google Developers Blog1223 字 (约 5 分钟)
85

DiffusionGemma 是基于 Gemma 4 的模型,通过并行生成和双向上下文机制,显著提升生成速度和推理效率。

入选理由:DiffusionGemma 在 NVIDIA H100 上实现每秒 1000+ tokens 的生成速度。

FeaturedArticle#DiffusionGemma#Gemma#AI模型#GPU优化英文
Google DeepMind Blog 图标

DiffusionGemma: 4x faster text generation

Google DeepMind Blog1006 字 (约 5 分钟)
85

DiffusionGemma 模型通过并行生成文本块,实现高达 4 倍的文本生成速度,适用于需要高速处理的本地交互场景。

入选理由:DiffusionGemma 在 NVIDIA H100 上每秒生成 1000+ tokens,速度比传统模型快 4 倍。

FeaturedArticle#DiffusionGemma#文本生成#AI模型#Google DeepMind英文
Hugging Face Blog 图标

Introducing North Mini Code: Cohere’s First Model For Developers

Hugging Face Blog2871 字 (约 12 分钟)
85

Cohere 发布 North Mini Code,一个 30B 参数的 Mixture-of-Experts 模型,专为开发者设计,在多个代码生成基准测试中表现优异。

入选理由:North Mini Code 是 Cohere 首个专为开发者设计的模型,参数量为 30B,其中 3B 为活跃参数。

FeaturedArticle#Cohere#模型#代码生成#Mixture-of-Experts#AI英文
Gemma 4 QAT models: Optimizing model compression for mobile and laptop efficiency

Gemma 4 QAT models: Optimizing model compression for mobile and laptop efficiency

The Keyword (blog.google)766 字 (约 4 分钟)
85

Google releases Gemma 4 QAT models with quantization-aware training, achieving 1GB memory footprint for E2B model.

入选理由:QAT技术使Gemma 4 E2B模型内存占用降至1GB

FeaturedArticle#Model Compression#Quantization Training#Mobile Optimization英文
Building a Multi-Tool Gemma 4 Agent with Error Recovery

Building a Multi-Tool Gemma 4 Agent with Error Recovery

Machine Learning Mastery3497 字 (约 14 分钟)
85

通过构建一个具有错误恢复机制的多工具 Gemma 4 代理,学习如何优雅地处理工具调用中的失败。

入选理由:迭代代理循环需设置最大迭代次数以防止无限循环。

FeaturedArticle#Gemma 4#工具调用#错误恢复#迭代代理英文
Hugging Face Blog 图标

Reachy Mini goes fully local

Hugging Face Blog1966 字 (约 8 分钟)
85

Reachy Mini now runs its voice backend locally, eliminating the need for cloud servers.

入选理由:部署本地语音后端于 Reachy Mini 上。

FeaturedArticle#Reachy Mini#Voice Backend#Local Service中文
Easy Agentic Tool Calling with Gemma 4

Easy Agentic Tool Calling with Gemma 4

KDnuggets2859 字 (约 12 分钟)
85

Gemma 4 enables true agentic behavior through local sandboxed tools like filesystem exploration and restricted Python execution.

入选理由:Gemma 4 支持本地工具调用,如文件系统探索和受限 Python 执行,增强模型自主性

FeaturedArticle#Gemma 4#Agent#Tool Calling#Security#Python英文
TLMs: Tiny LLMs and Agents on Edge Devices with @cormacb 

https://t.co/u0fHD7j5kZ

Function Gemma s...

本文介绍了Tiny LLMs和Agents在边缘设备上的应用,特别是Function Gemma模型在Pixel 7上的性能表现,以及开发者在设备上实现AI的两种路径:基于Gemma 4的技能框架和Eloquent生产转录应用。

入选理由:Function Gemma模型在Pixel 7上以270M参数运行,预填处理速度达到近2000 token/秒,出厂时在固定应用意图上准确率达到46%。

FeaturedTweet#Tiny LLMs#Edge Devices#Function Gemma#AI on Devices#Machine Learning中文
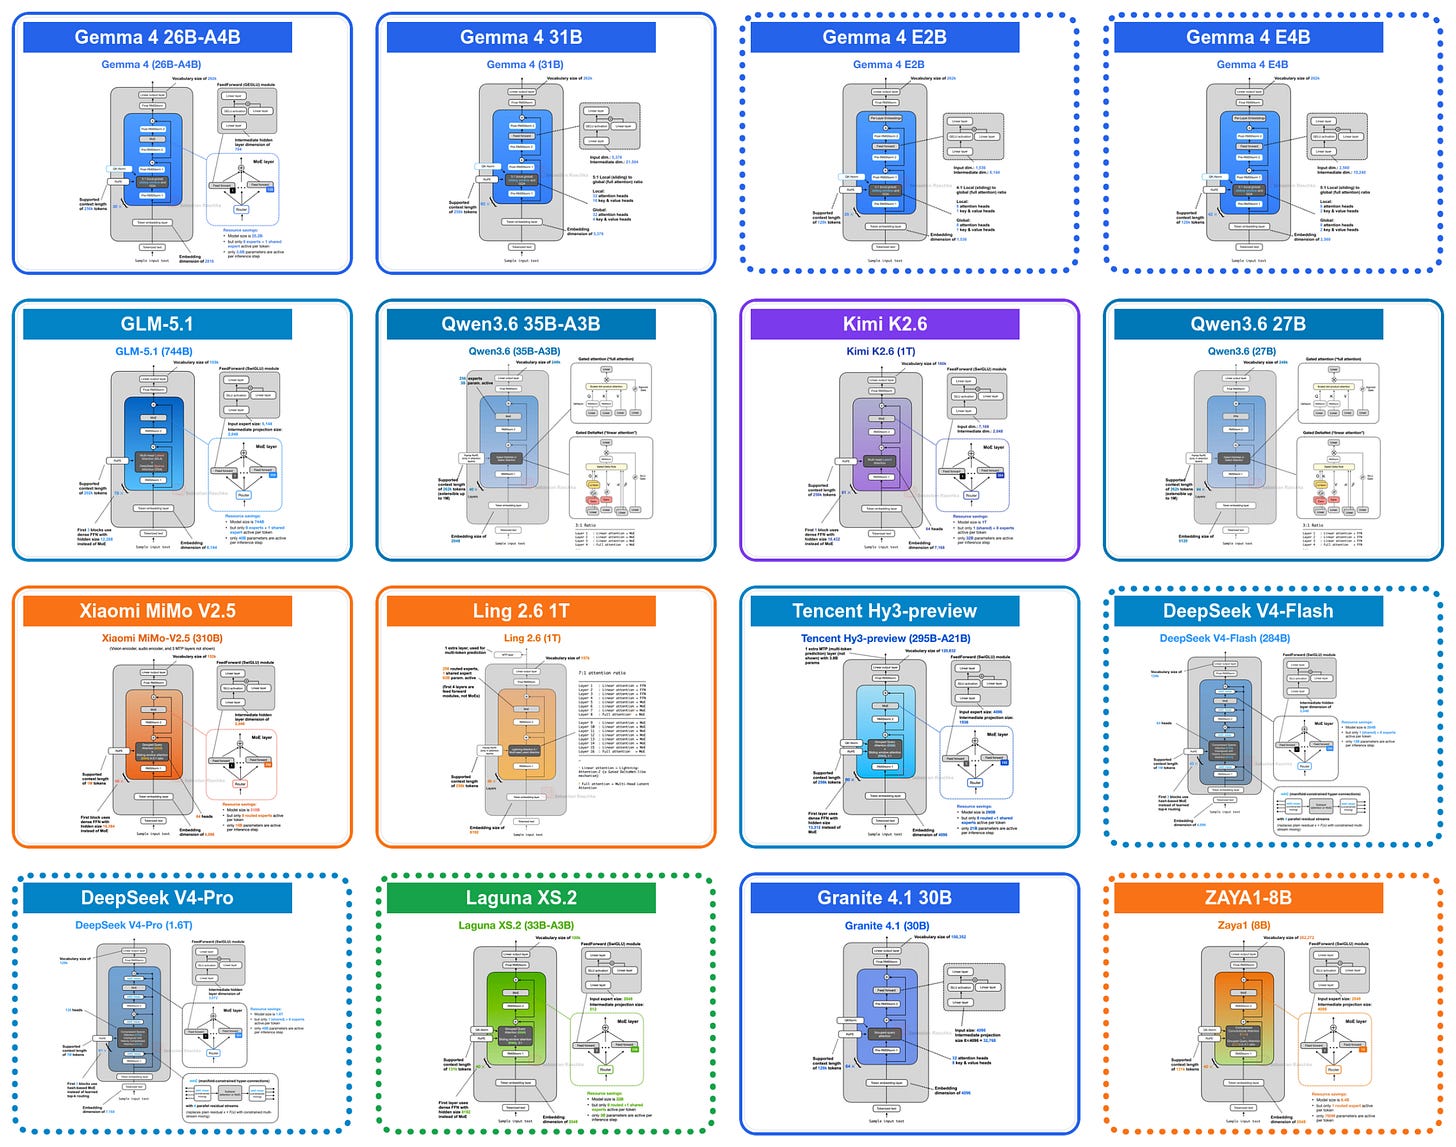
Recent Developments in LLM Architectures: KV Sharing, mHC, and Compressed Attention

Recent developments in LLM architectures focus on KV sharing, mHC, and compressed attention to improve long-context efficiency.

入选理由:Gemma 4引入KV共享和每层嵌入,优化内存使用。

FeaturedArticle#LLM#Architecture Optimization#Attention Mechanism英文
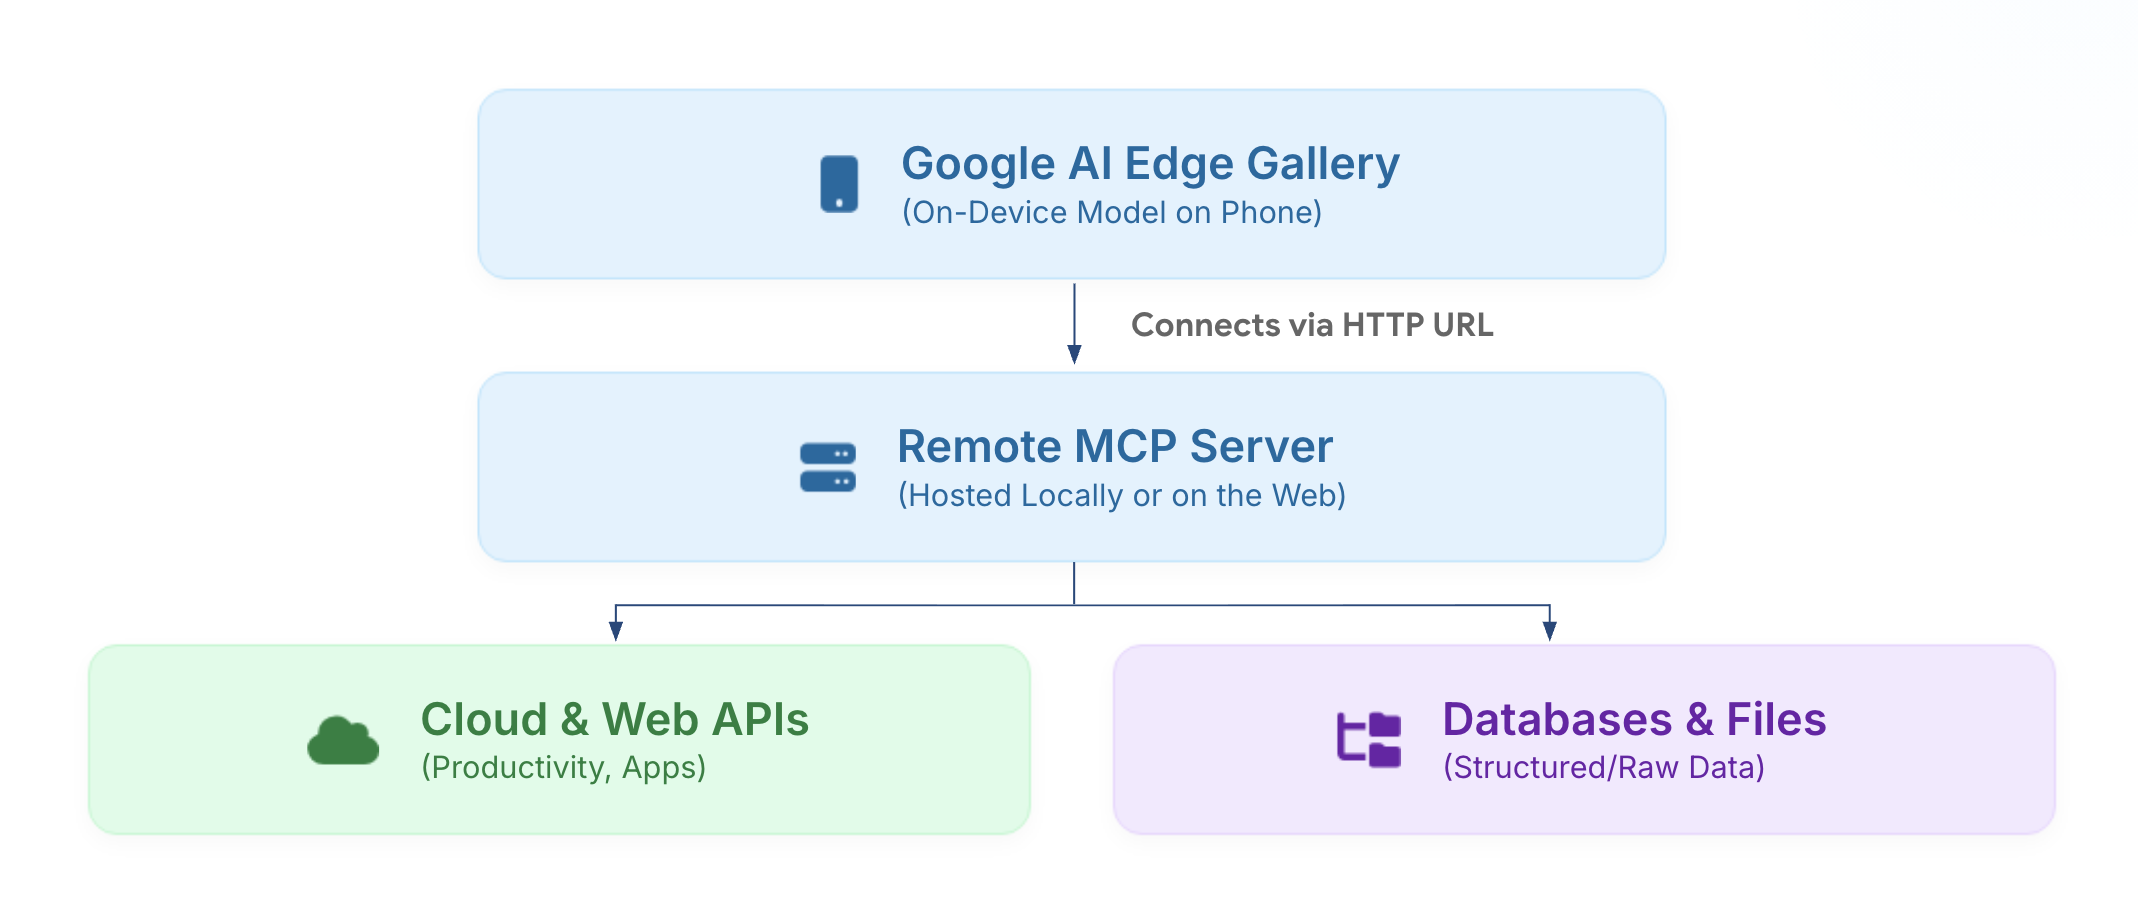
A Smarter Google AI Edge Gallery: MCP integration, notifications, and session continuity

A Smarter Google AI Edge Gallery: MCP integration, notifications, and session continuity

Google Developers Blog1169 字 (约 5 分钟)
80

Google AI Edge Gallery introduces three major capabilities: MCP protocol support for cross-data-source tool calling, local notification scheduling for proactive interactions, and persistent chat history, shifting mobile Agent development from reactive to automated and continuous experiences.

入选理由:通过注册MCP URL,应用可将工具定义动态导入本地模型系统提示词,推理完全在手机端完成,请求由MCP服务器执行

FeaturedArticle#Google AI Edge Gallery#MCP#On-device AI#Gemma 4#Mobile Agent英文
Ok that's so cool

Multi-token prediction makes Gemma 4 run way faster locally!

Same model, same la...

Ok that's so cool

Paul Couvert(@itsPaulAi)281 字 (约 2 分钟)
78

Multi-token prediction technology makes Gemma 4 run 1.5 times faster locally, reaching 138 tokens/s.

入选理由:Gemma 4使用MTP后,性能从97 tokens/s提升至138 tokens/s。

FeaturedTweet#Gemma 4#MTP#Open Source中文
We released Gemma 4 12B yesterday. Here is a visual guide that explains the full architecture.

→ Ho...

Gemma 4 12B Released: Visual Guide to Native Multimodal Architecture

Philipp Schmid(@_philschmid)169 字 (约 1 分钟)
75

Gemma 4 12B achieves native multimodal processing for text, images, and audio by removing separate vision and audio encoders. This architecture replaces traditional encoder-patching approaches with joint representation learning, reducing inference latency and improving edge deployment efficiency.

入选理由:Gemma 4 12B移除独立视觉/音频编码器,采用原生多模态统一架构

FeaturedTweet#Gemma 4#Multimodal LLM#Native Multimodality#Edge AI英文

跨材料问答 · Gemma 4

回答基于:Gemma 4 相关 30 条材料
    0 / 500

    AI may generate inaccurate information. Please verify important content.