T
traeai
Sign in

产品

Apache Spark

别名:spark

大数据处理引擎

已跟踪 14 条高相关材料

TraeAI 观察

相关材料

已收录 14 条与 Apache Spark 相关的内容,按评分排序。

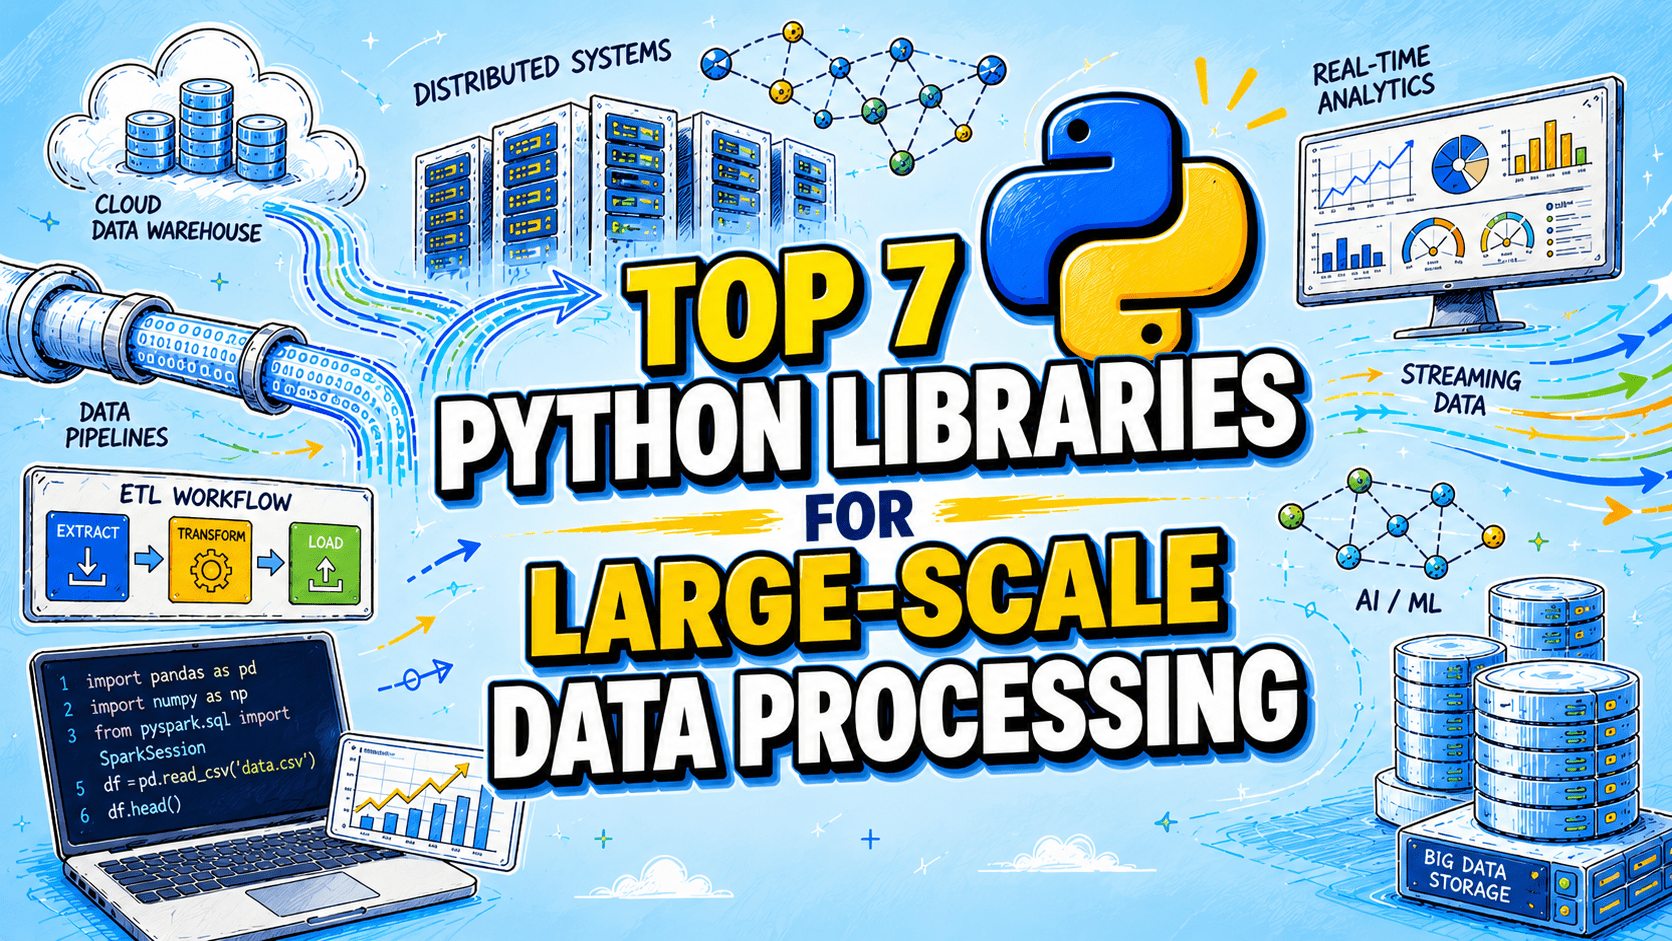
Top 7 Python Libraries for Large-Scale Data Processing

Top 7 Python Libraries for Large-Scale Data Processing

KDnuggets1233 字 (约 5 分钟)
90

This article lists and reviews seven top Python libraries for large-scale data processing, including PySpark, Dask, Polars, Ray, Vaex, Vaex-Java, and Vaex-Python.

入选理由:PySpark is ideal for distributed ETL and cluster-scale pipelines.

FeaturedArticle#Python#Data Processing#Libraries英文
Databricks 图标

Leverages Apache Spark Real-Time Mode and transformWithState to deliver a unified, sub-second real-time sessionization architecture, replacing Flink or in-house solutions to power personalization, recommendation engines, and dynamic content scheduling for millions of players.

入选理由:使用 transformWithState + Real-Time Mode 实现单引擎统一架构,输入处理与定时触发均可达亚秒级精度。

FeaturedArticle#Apache Spark#Real-Time Mode#transformWithState#Structured Streaming#Gaming英文
Accelerating data lakes: Optimizing Apache Iceberg and Spark with gcs-analytics-core

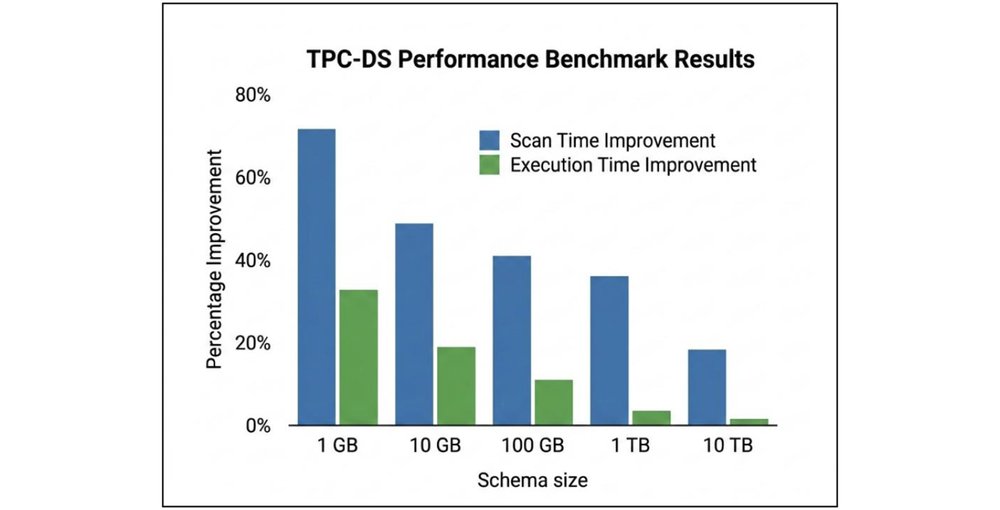
Google Cloud announces gcs-analytics-core, an open-source Java library designed to optimize Apache Iceberg and Spark workloads on Google Cloud Storage, achieving significant performance improvements through parallel I/O and smart Parquet prefetching.

入选理由:gcs-analytics-core 是一个开源 Java 库,用于优化 GCS 上的 Apache Iceberg 和 Spark 工作负载。

FeaturedArticle#Apache Iceberg#Apache Spark#GCS#Data Lake#Performance Optimization英文
Databricks 图标

How to teach with Databricks Free Edition

Databricks1530 字 (约 7 分钟)
85

Databricks Free Edition为教育提供免费的生产级数据和AI平台,支持课程教学和学生实践。

入选理由:Databricks Free Edition支持从数据科学到AI的完整课程体系,无需云合同或安装。

FeaturedArticle#Databricks#教育技术#数据科学#AI教学英文
Databricks 图标

Databricks的Unity Catalog管理表允许用户在自有云存储中控制数据位置,支持Iceberg和Delta格式,并通过开放API实现数据治理。

入选理由:Unity Catalog管理表数据存储在用户拥有的S3/ADLS/GCS等云存储中

FeaturedArticle#Unity Catalog#云存储#数据治理#Delta#Iceberg英文
Databricks 图标

Databricks在Apache Spark 4.2中扩展AUTO CDC功能,支持Bitemporal和Partial Updates,解决数据工程中的复杂问题。

入选理由:Bitemporal CDC通过双时间轴(业务时间+系统时间)满足SEC合规要求

FeaturedArticle#Spark#CDC#数据工程#Apache Spark 4.2英文
Towards Data Science 图标

The Medallion Data Architecture: An Introduction

Towards Data Science3354 字 (约 14 分钟)
85

Medallion数据架构通过Bronze、Silver、Gold三层分层处理数据,提升数据质量和可维护性。

入选理由:Bronze层存储原始数据,需记录数据源、加载时间等元数据

FeaturedArticle#数据工程#数据架构#Databricks#Delta Lake英文
Databricks 图标

Introducing Apache Spark 4.2

Databricks2112 字 (约 9 分钟)
85

Apache Spark 4.2通过metric views、Spark Connect和Auto CDC等特性,强化了数据治理与AI原生分析能力,提升跨生态数据处理效率。

入选理由:Metric Views统一业务指标定义,避免多系统重复计算导致的语义偏差

FeaturedArticle#Apache Spark#数据治理#AI原生分析#实时计算英文
Synthesize the big picture and analyze trends with BigQuery's AI.AGG function

Synthesize the big picture and analyze trends with BigQuery's AI.AGG function

Google Cloud Blog2087 字 (约 9 分钟)
85

BigQuery推出AI.AGG函数,通过自然语言指令分析非结构化数据,提升日志分析效率。

入选理由:AI.AGG支持在单行SQL中处理非结构化数据,如日志和文档分析

FeaturedArticle#BigQuery#AI#数据分析#SQL英文
Deep dive: How Lightning Engine delivers 4.9x faster Apache Spark performance

Deep dive: How Lightning Engine delivers 4.9x faster Apache Spark performance

Google Cloud Blog912 字 (约 4 分钟)
85

Lightning Engine 提升 Apache Spark 性能达 4.9 倍,通过原生执行和优化连接器实现。

入选理由:Lightning Engine 提供高达 4.9 倍于标准 Spark 的性能提升。

FeaturedArticle#Apache Spark#性能优化#Google Cloud#大数据英文
What's new for Managed Service for Apache Spark clusters

Google Cloud Announces Enhancements to Managed Spark Clusters

Google Cloud Blog1353 字 (约 6 分钟)
85

Google Cloud has introduced several enhancements to Managed Spark clusters, including Lightning Engine, Flexible VMs, and Gemini-powered extensions, significantly improving performance and flexibility.

入选理由:Lightning Engine 可使 Spark 性能提升最高 4.9 倍。

FeaturedArticle#Apache Spark#Google Cloud#Lightning Engine#Gemini#Data Analytics英文
What’s new in serverless Managed Service for Apache Spark

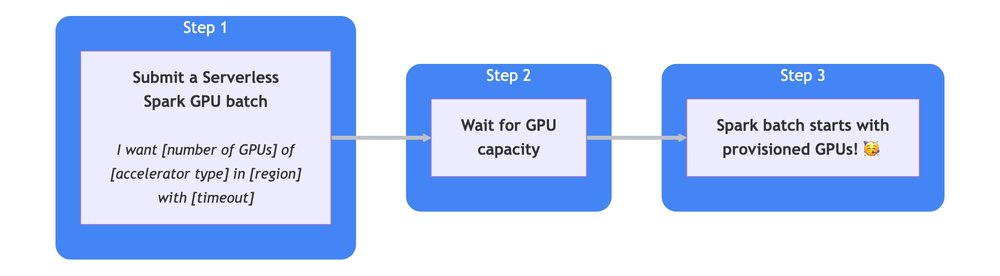
Google Cloud has announced the general availability of the serverless Managed Service for Apache Spark runtime version 3.0, prioritizing speed, simplicity, and reliability. This update reduces startup times by 75%, improves GPU obtainability with Dynamic Workload Scheduler Flex Start Mode, and supports Apache Spark 4.x innovations.

入选理由:Serverless Managed Service for Apache Spark runtime 3.0 reduces startup times by 75%.

FeaturedArticle#serverless#Apache Spark#runtime中文
Article: Architecting Cloud-Native Kafka: From Tiered Storage Towards a Diskless Future

Apache Kafka is transitioning towards a cloud-native architecture, changing its economic model through storage disaggregation, reducing operational costs, and improving flexibility.

入选理由:存储去耦合使 Kafka 经济模式发生变化,将成本从基础设施预配转移到云 API 使用,减少了不高效的消费者访问模式带来的运营费用。

FeaturedArticle#Kafka#Cloud Native#Storage Disaggregation中文
Towards Data Science 图标

PySpark for Beginners: Mastering the Basics

Towards Data Science2548 字 (约 11 分钟)
80

This article introduces the basic concepts and core mechanisms of PySpark to help beginners understand how to process large-scale data with Python.

入选理由:PySpark是Apache Spark的Python API,用于分布式数据处理。

FeaturedArticle#PySpark#Big Data中文

跨材料问答 · Apache Spark

回答基于:Apache Spark 相关 14 条材料
    0 / 500

    AI may generate inaccurate information. Please verify important content.